Qwen Releases Wan 2.2, a 5B Open Video AI Model
The new Apache 2.0 licensed model from Alibaba's team can generate video from both text and image prompts, adding a powerful new tool to the open-source creative ecosystem.
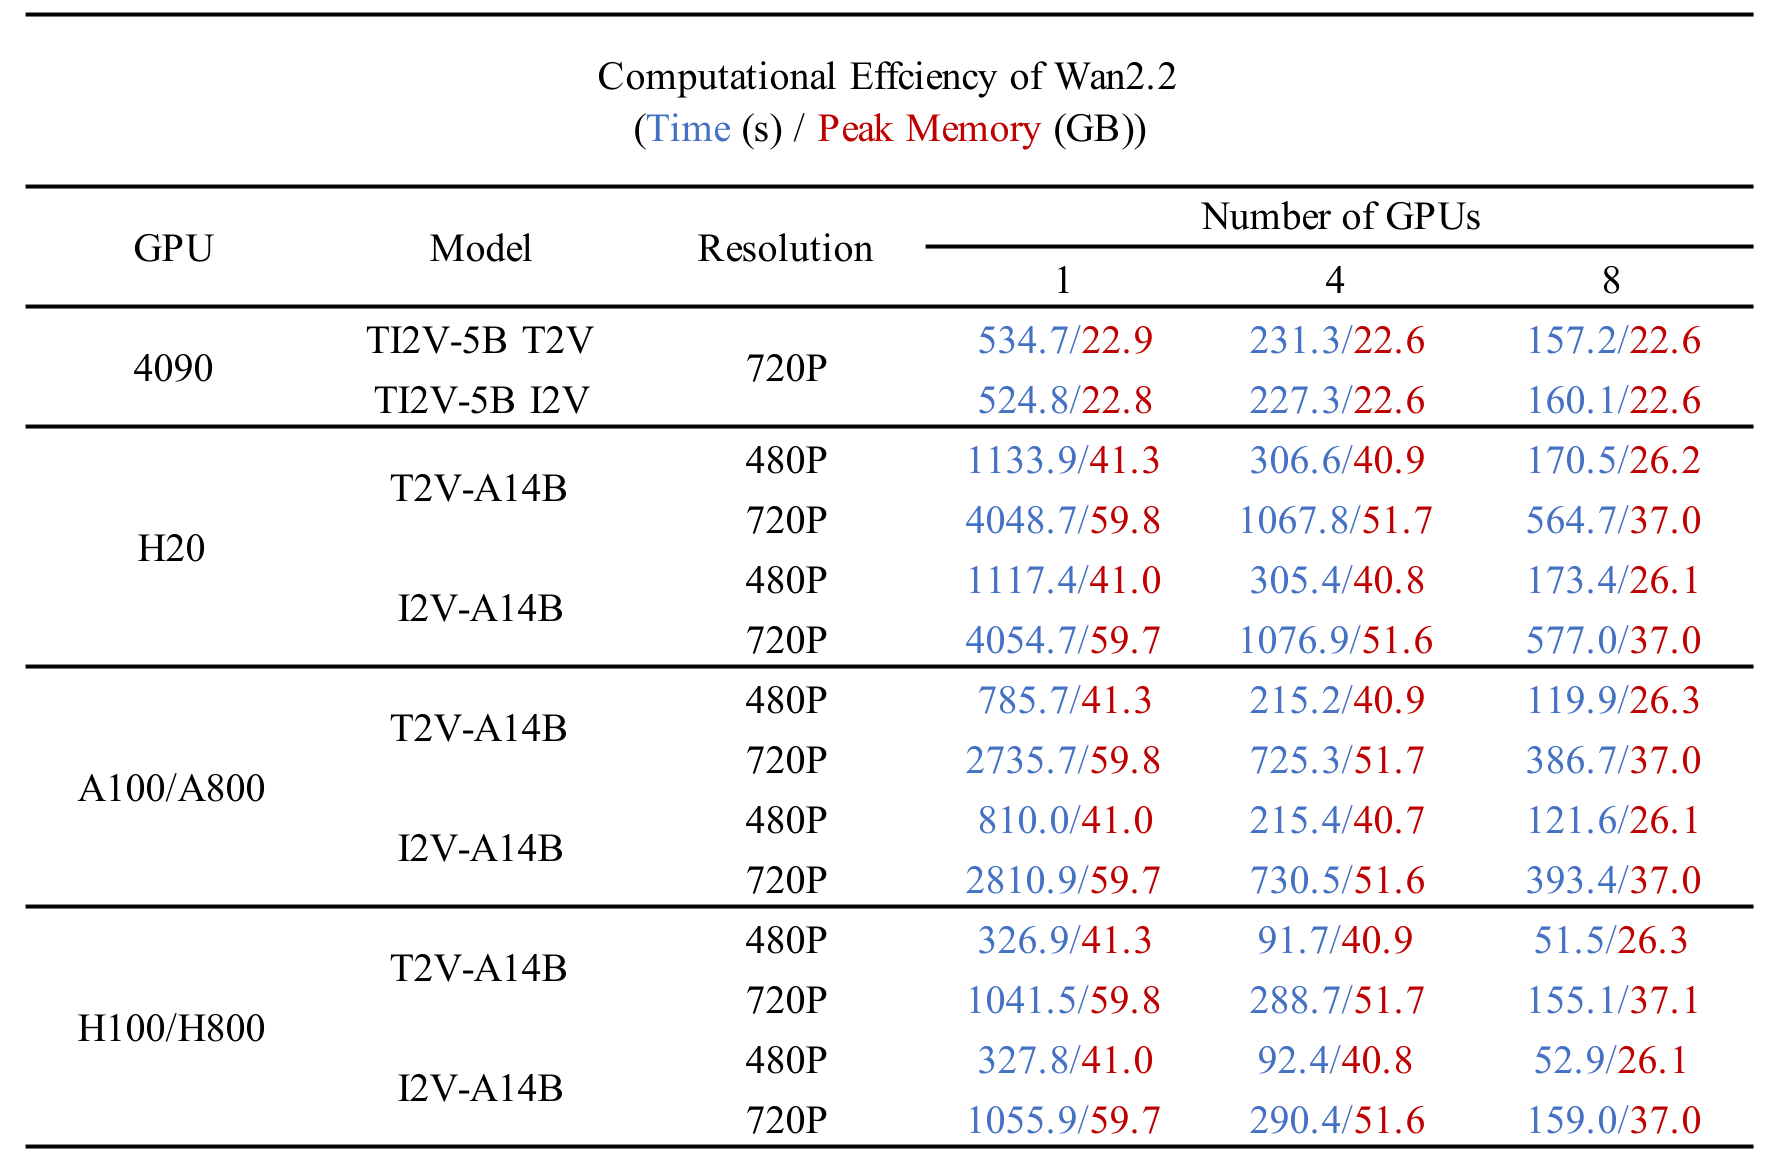
Alibaba's Qwen team has released Wan2.2-TI2V-5B, a new open-source model for video generation. With 5 billion parameters, the model is a significant contribution to the rapidly evolving field of open AI video, and is available under the permissive Apache 2.0 license.
The model is notable for its unified architecture, which allows it to generate video from either a text prompt or a combination of a static image and a text prompt. This dual capability provides a flexible starting point for creative workflows, enabling users to animate existing images or generate entirely new scenes from scratch.
Why It Matters
While proprietary models like OpenAI's Sora have demonstrated remarkable capabilities, the open-source community is actively building alternatives. The release of a competent video model from a major lab like Alibaba gives researchers and developers a powerful new tool to build upon. The Apache 2.0 license is particularly important, as it permits commercial use and modification, encouraging broader adoption and innovation.
Developers can access the model and its weights directly from the official Hugging Face repository. The release provides another foundational block for building open, transparent, and accessible generative video applications.
Sources
- Visit
Wan-AI/Wan2.2-TI2V-5B
Hugging Face
More from Qwen · Alibaba
All Qwen · Alibaba releases →Qwen-Audio-3.1-ASR Adds Speaker-Aware Transcription
Alibaba's new open audio-language model transcribes and diarizes speech across 30 languages under an Apache 2.0 license.
Qwen-Image-2.1-Turbo targets faster generation
Alibaba's Qwen team ships a distilled, few-step variant of its image model built for speed.
Qwen-Image-2.1 Adds RGBA to Image Generation
Alibaba's Qwen team updates its open image model with transparency support and joint text-to-image and editing capabilities.
More in Text → Video
All Text → Video →
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
Kandinsky 6.0 Generates Video and Audio Together
Kandinsky Lab's new foundation models produce synchronized sound and motion from a text prompt, in 3B and 29B sizes.
MiniMax Releases H3 Video Model on Hugging Face
The company's new diffusion model handles text-to-video and image-to-video, with support for joint audio-video generation.
0 comments
No comments yet. Be the first to weigh in.