Mistral debuts Shieldstral, a 3B safety model
The open-weights multimodal moderation model brings content safety checks to both text and images under an Apache 2.0 license.
Mistral AI has released Shieldstral, a 3-billion-parameter open-weights model built specifically for content moderation across both text and images. According to Mistral's announcement, the model is aimed at helping developers screen inputs and outputs in AI applications, and it ships under a permissive Apache 2.0 license.
Unlike a general-purpose chat model, Shieldstral is a dedicated safety classifier. Its multimodal design means it can evaluate not just text but also images, an increasingly important capability as more applications accept mixed inputs and generate visual content.
Why it matters
Safety tooling has often been the least open part of the modern AI stack, with many moderation systems locked behind proprietary APIs. A compact, openly licensed model changes that calculus for teams that need to run checks themselves.
- At roughly 3B parameters, it is small enough to deploy affordably alongside larger systems.
- The Apache 2.0 license permits commercial use and modification.
- Multimodal coverage lets it handle both text and image moderation in one model.
The release fits a broader industry pattern of shipping guardrail models as companions to frontier systems, echoing efforts like Meta's Llama Guard. For developers building on open weights, having a moderation layer from the same ecosystem lowers the friction of assembling a safer pipeline without giving up control of their data.
Sources
More from Mistral AI
All Mistral AI releases →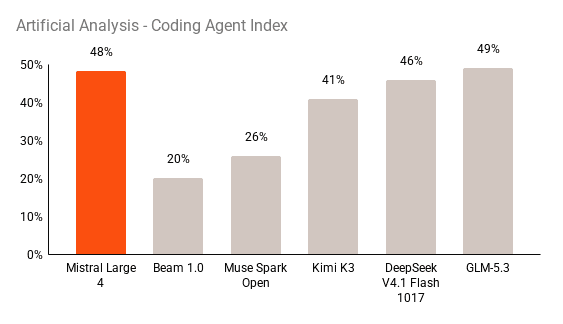
Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.
Mistral's Timestral brings forecasting to open weights
The French lab releases a compact 209M-parameter foundation model aimed squarely at time-series prediction.
Mistral Large 4 arrives as a trillion-param MoE
The new flagship is a sparse mixture-of-experts model with roughly 49B active parameters per token.
More in Vision-Language
All Vision-Language →
SenseTime Releases Looped 9B Multimodal Model
The company's new SenseNova-Loop-9B pairs vision-language capabilities with a recurrent looped-transformer design.

Tencent releases Hunyuan Hy4-flash multimodal MoE
The lightweight, mixture-of-experts model adds vision and text instruction-following to Tencent's open Hunyuan lineup.
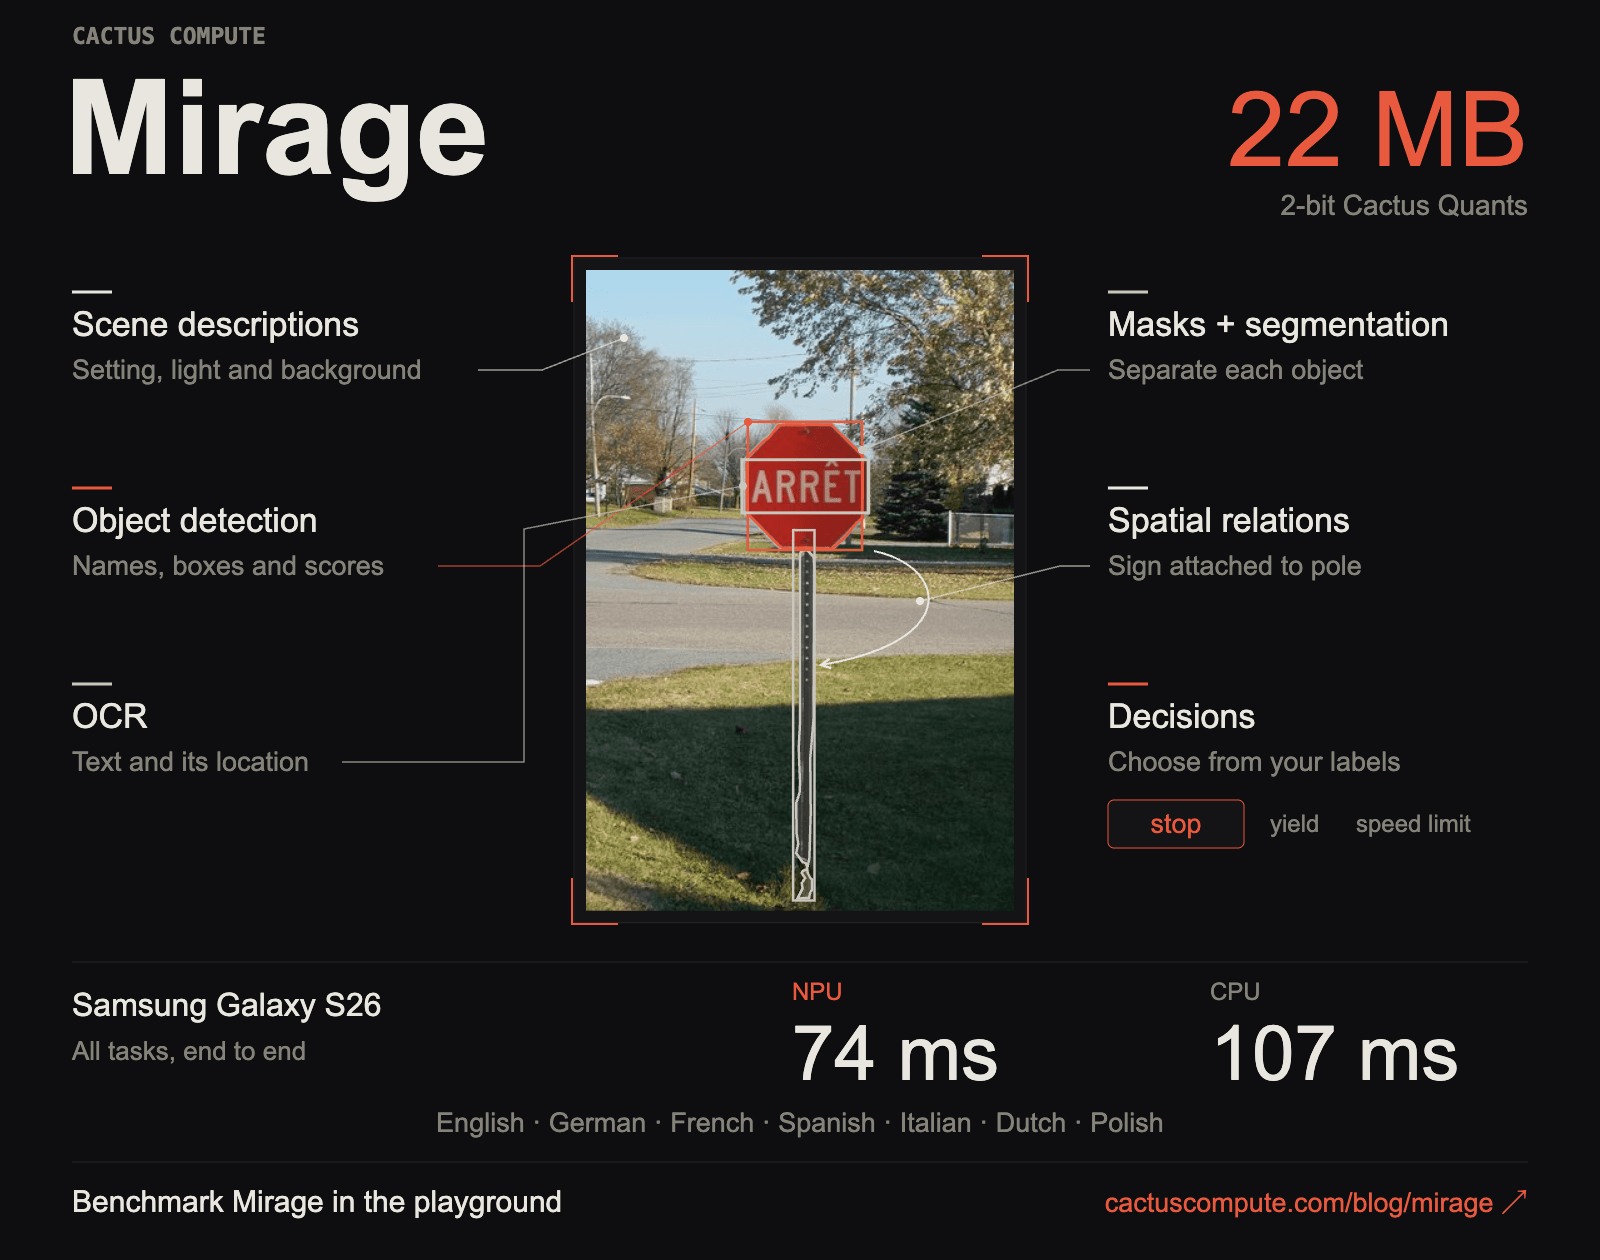
Cactus Compute's Mirage brings vision tasks on-device
The new open vision-language model targets detection, segmentation, and visual Q&A without relying on the cloud.
0 comments
No comments yet. Be the first to weigh in.