OVHcloud enters AI race with Olala, a Mamba/MoE model
The French cloud provider's first language model is a compact hybrid architecture built with EU public funding.
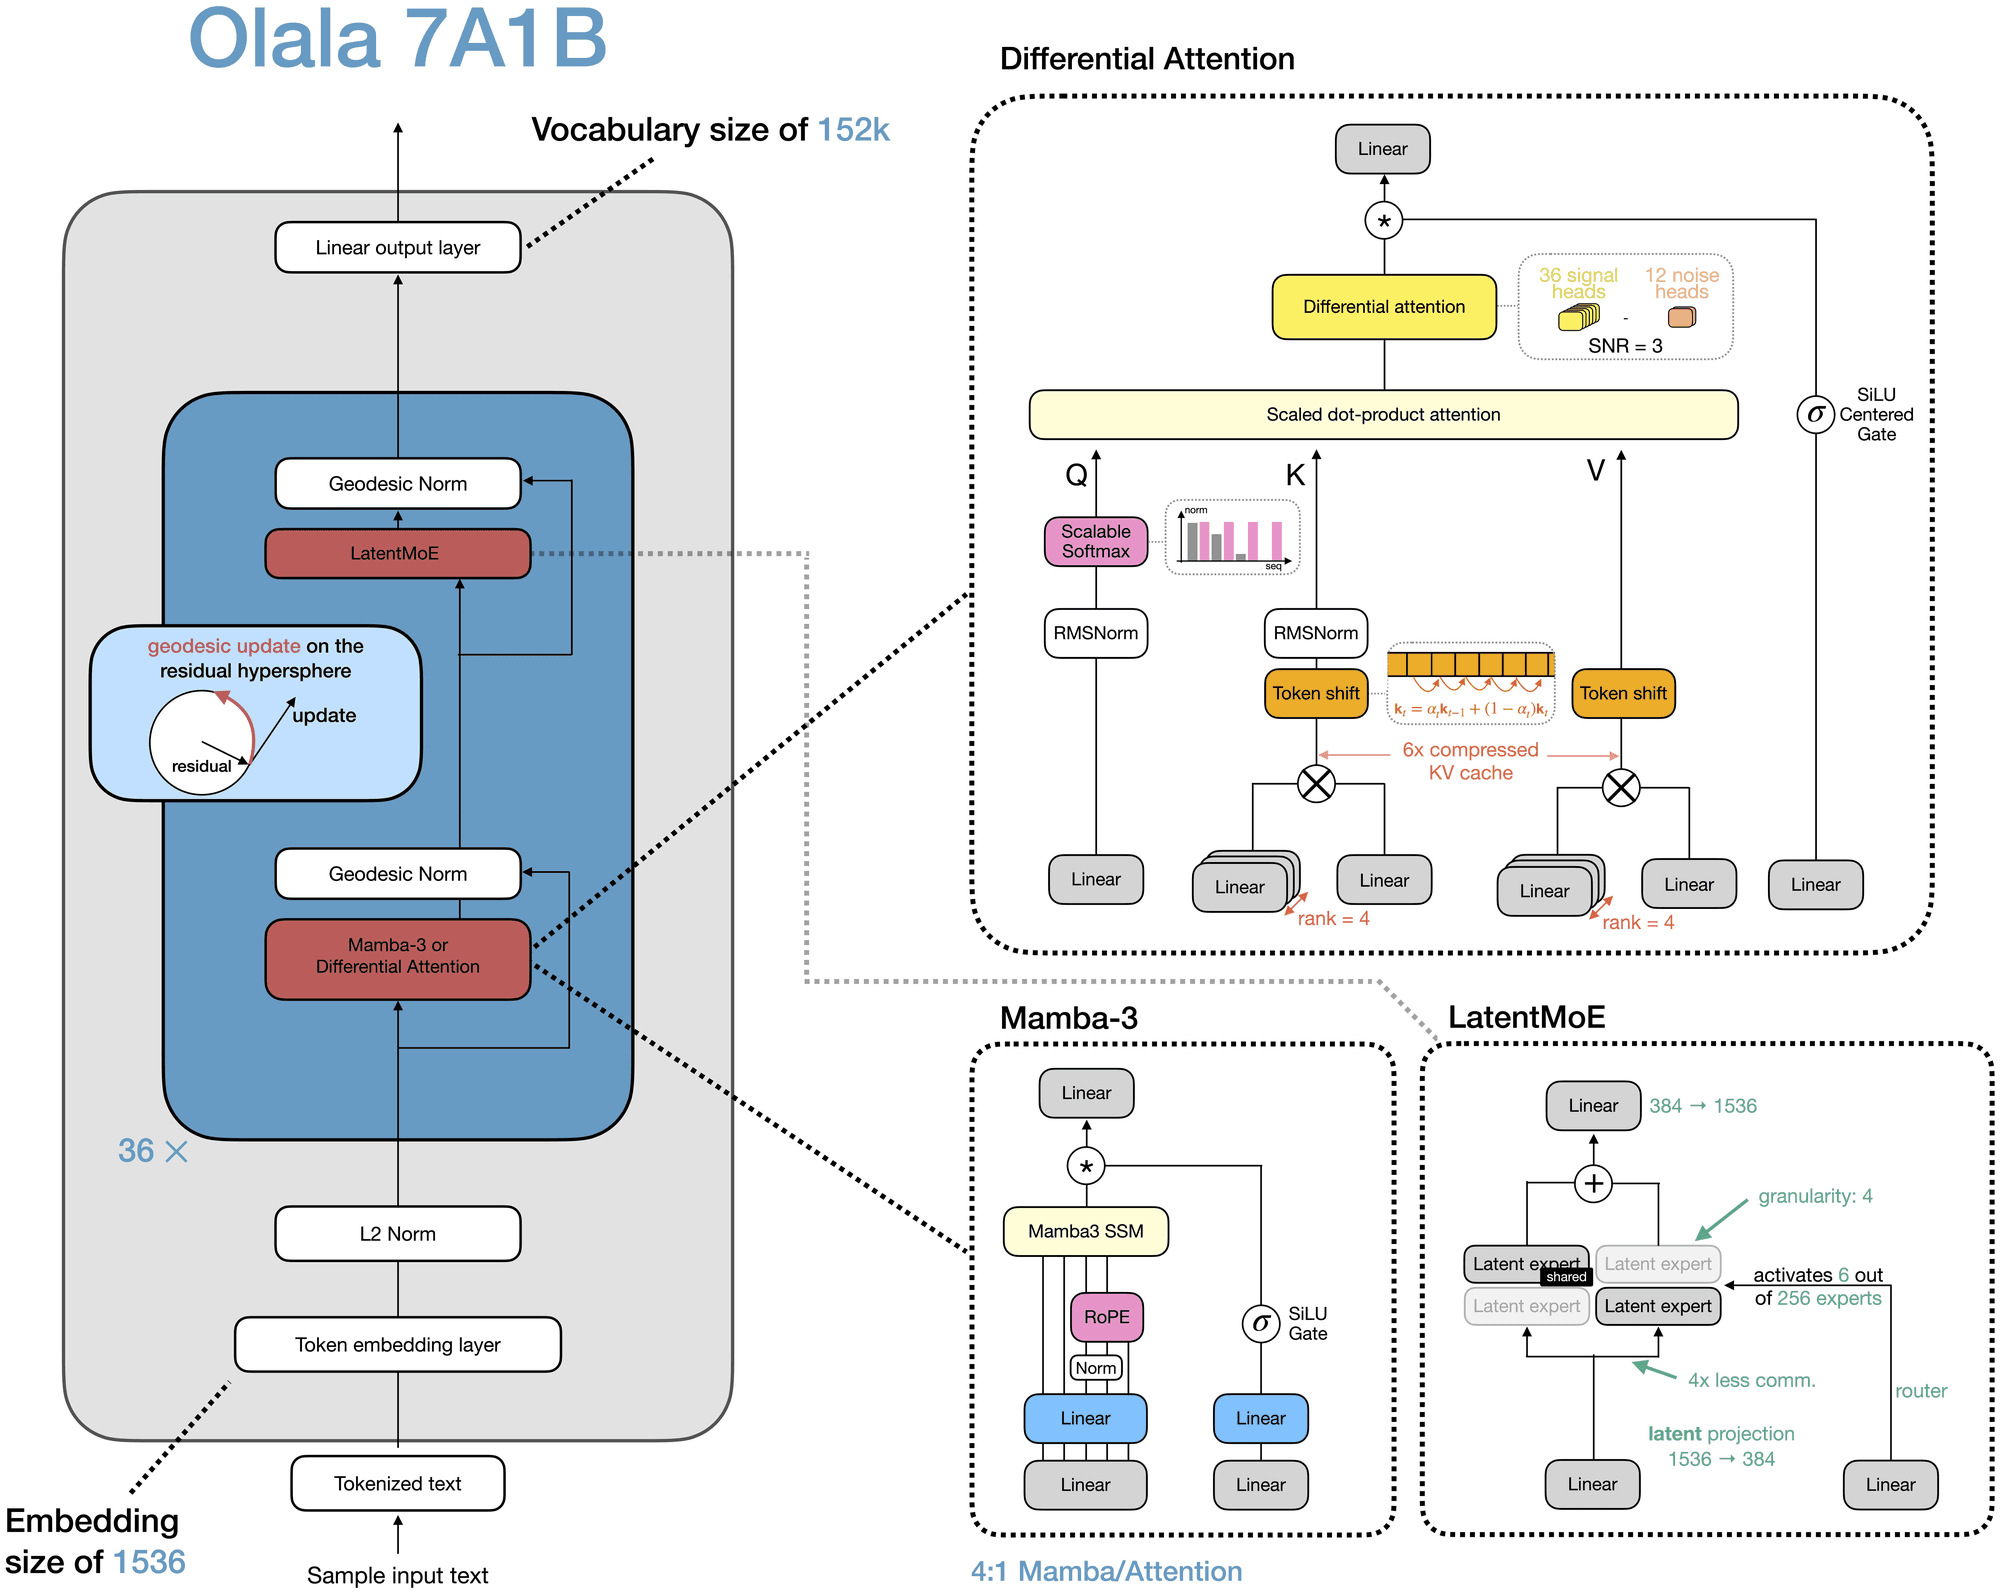
OVHcloud, the French cloud and hosting company, has released its first language model. Called Olala v1.0 mini 7A1B, the model marks the provider's entry into building its own open-weight AI rather than simply hosting others' systems.
The design is unusual for a debut. Olala combines a Mamba-style state-space backbone with a mixture-of-experts layer, giving it 7 billion total parameters but only around 1 billion active per token. That approach aims to keep inference costs low while retaining the capacity of a larger network — a sensible priority for a company whose business is efficient infrastructure.
Why it matters
The release is notable less for raw benchmarks, which the record does not detail, than for who is behind it. Olala was built with EU public funding, part of a broader European push to develop sovereign AI capabilities that don't depend on US or Chinese labs.
- Hybrid Mamba plus mixture-of-experts architecture
- 7B total parameters, roughly 1B active
- Listed for text generation and reasoning
- Released under an "other" license, so terms warrant a close read
As a "mini" first version, Olala reads more like a statement of intent than a flagship. The real test will be whether OVHcloud follows with larger models and clearer licensing — and whether a European cloud provider can turn infrastructure scale into competitive open models.
Sources
- Visit
OVHaiLLM/Olala-v1.0-mini-7A1B
Hugging Face
More in Text / LLM
All Text / LLM →
Microsoft's Aion 1.0 Instruct is a compact 2.3B chat model
A small, multilingual instruction-tuned model aimed at chat and summarization lands on Hugging Face.

SenseTime Releases Looped 9B Multimodal Model
The company's new SenseNova-Loop-9B pairs vision-language capabilities with a recurrent looped-transformer design.

Tencent releases Hunyuan Hy4-flash multimodal MoE
The lightweight, mixture-of-experts model adds vision and text instruction-following to Tencent's open Hunyuan lineup.
0 comments
No comments yet. Be the first to weigh in.