Meta's Muse Spark Open brings a frontier MoE to open weights
The 816B-parameter mixture-of-experts model activates just 42B per token and targets agentic coding across a million-token context.

Meta AI has released Muse Spark Open, an open-weight multimodal model built on a mixture-of-experts design. The model totals 816 billion parameters but activates only 42 billion for any given token, a structure meant to deliver frontier-scale capability without the full compute cost of a dense model of the same size.
The headline capability is reach. Muse Spark Open supports a context window of up to one million tokens and handles text and vision inputs, positioning it for agentic coding workflows where a model needs to keep an entire codebase, long logs, or multi-step task histories in view at once.
Why it matters
Open releases at this scale remain rare. Most models that compete at the frontier stay behind APIs, so weights that developers can inspect, fine-tune, and self-host change what independent teams can build.
- 816B total parameters, 42B active per token
- Multimodal: text and vision inputs
- Up to 1,000,000-token context
- Oriented toward agentic coding
The sparse-activation approach is the practical hook here: it lets a very large parameter count run with the inference footprint closer to a mid-size dense model. Licensing is listed as a custom "other" license rather than a standard permissive one, so teams planning production use should read Meta's terms closely. Full details are available on the model's Hugging Face page.
Sources
- Visit
meta-models/Muse-Spark-Open-816B-A42B
Hugging Face
More from Meta AI
All Meta AI releases →
Meta's Muse Glimmer 30B Targets Local Agentic Coding
A 30-billion-parameter multimodal model built to run locally, released under Apache 2.0 with an eye on agentic coding workflows.
Meta releases SAM 3 for image and video segmentation
The latest Segment Anything Model extends Meta's mask-generation lineage from still images into video, now available on Hugging Face.

Meta Releases DINOv3 ViT-L/16 Vision Backbone
The self-supervised feature extractor arrives on Hugging Face as a general-purpose backbone for downstream vision tasks.
More in Any-to-Any
All Any-to-Any →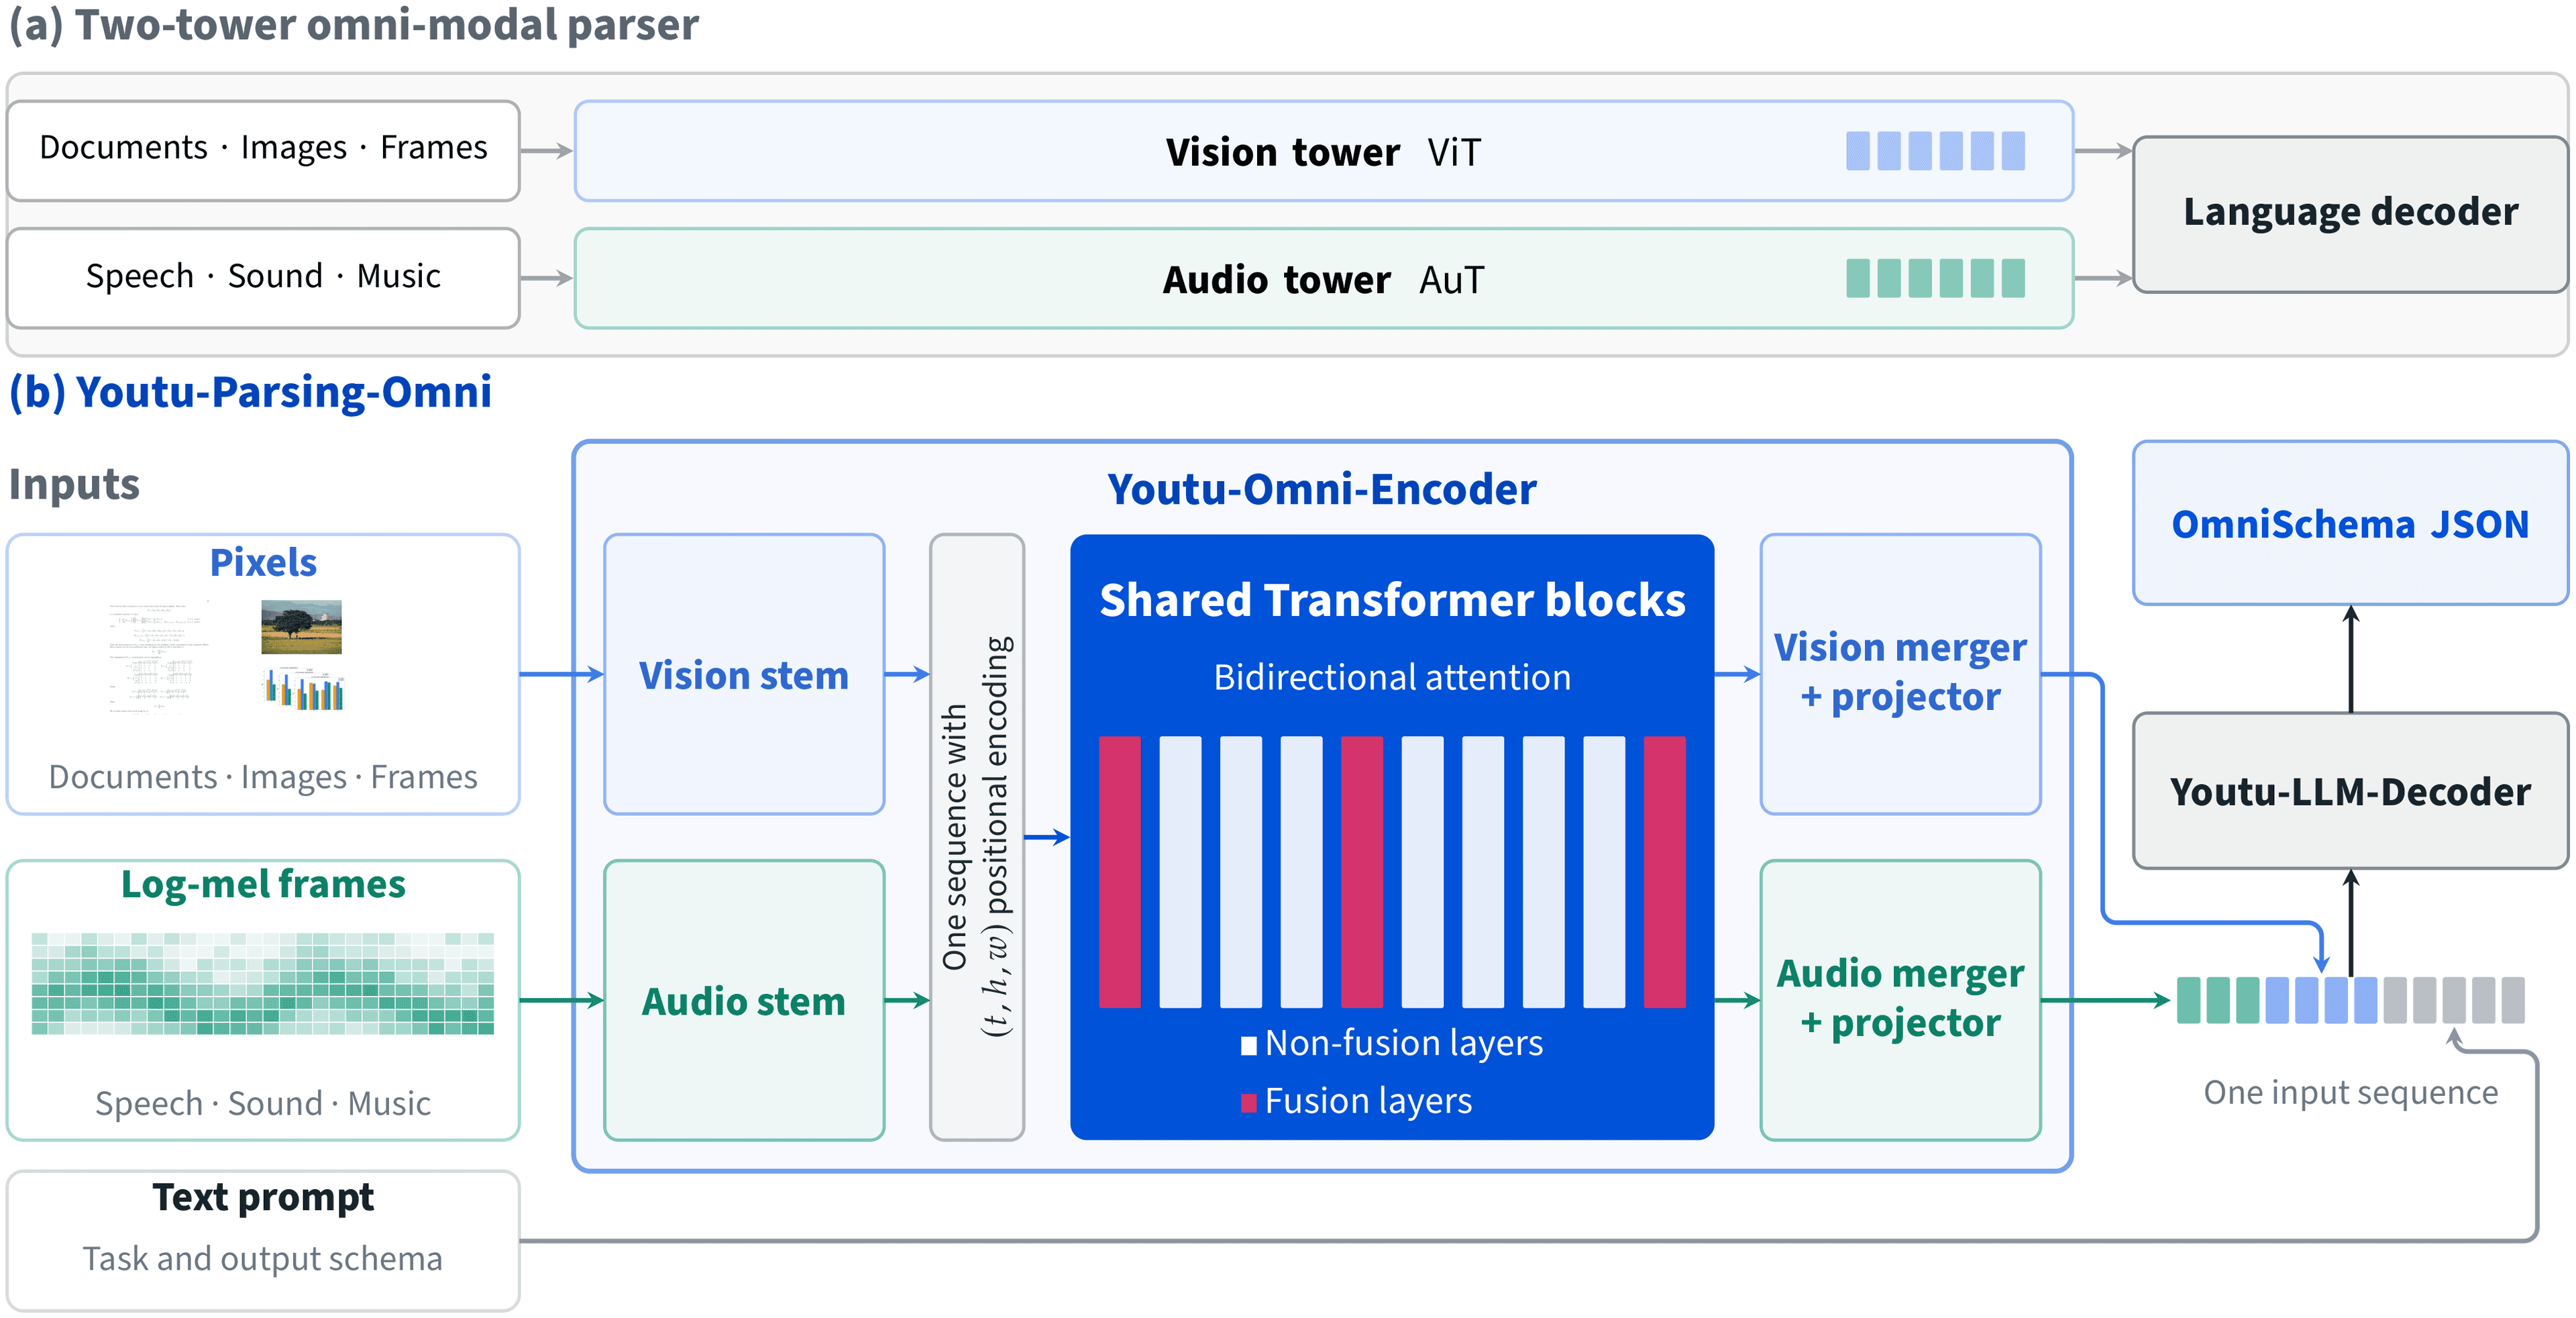
Tencent's Youtu-Parsing-Omni tackles docs, audio, video
A new open-weights parsing model from Tencent extends OCR beyond the page into audio and video inputs.
Xiaomi's MiMo-V2.6 bets on RL for self-improvement
The omni-modal model family leans on reinforcement learning to push reasoning without endless new supervised data.
Cloudflare's Clef brings structured decisions to open models
The new open-weight vision-language family outputs typed, structured results and arrives alongside a reinforcement-learning fine-tuning platform.
0 comments
No comments yet. Be the first to weigh in.