OpenMOSS Releases MOVA, a 720p Multimodal Video Generator
The new open model can generate high-definition video with synchronized audio from a flexible combination of text and image prompts.
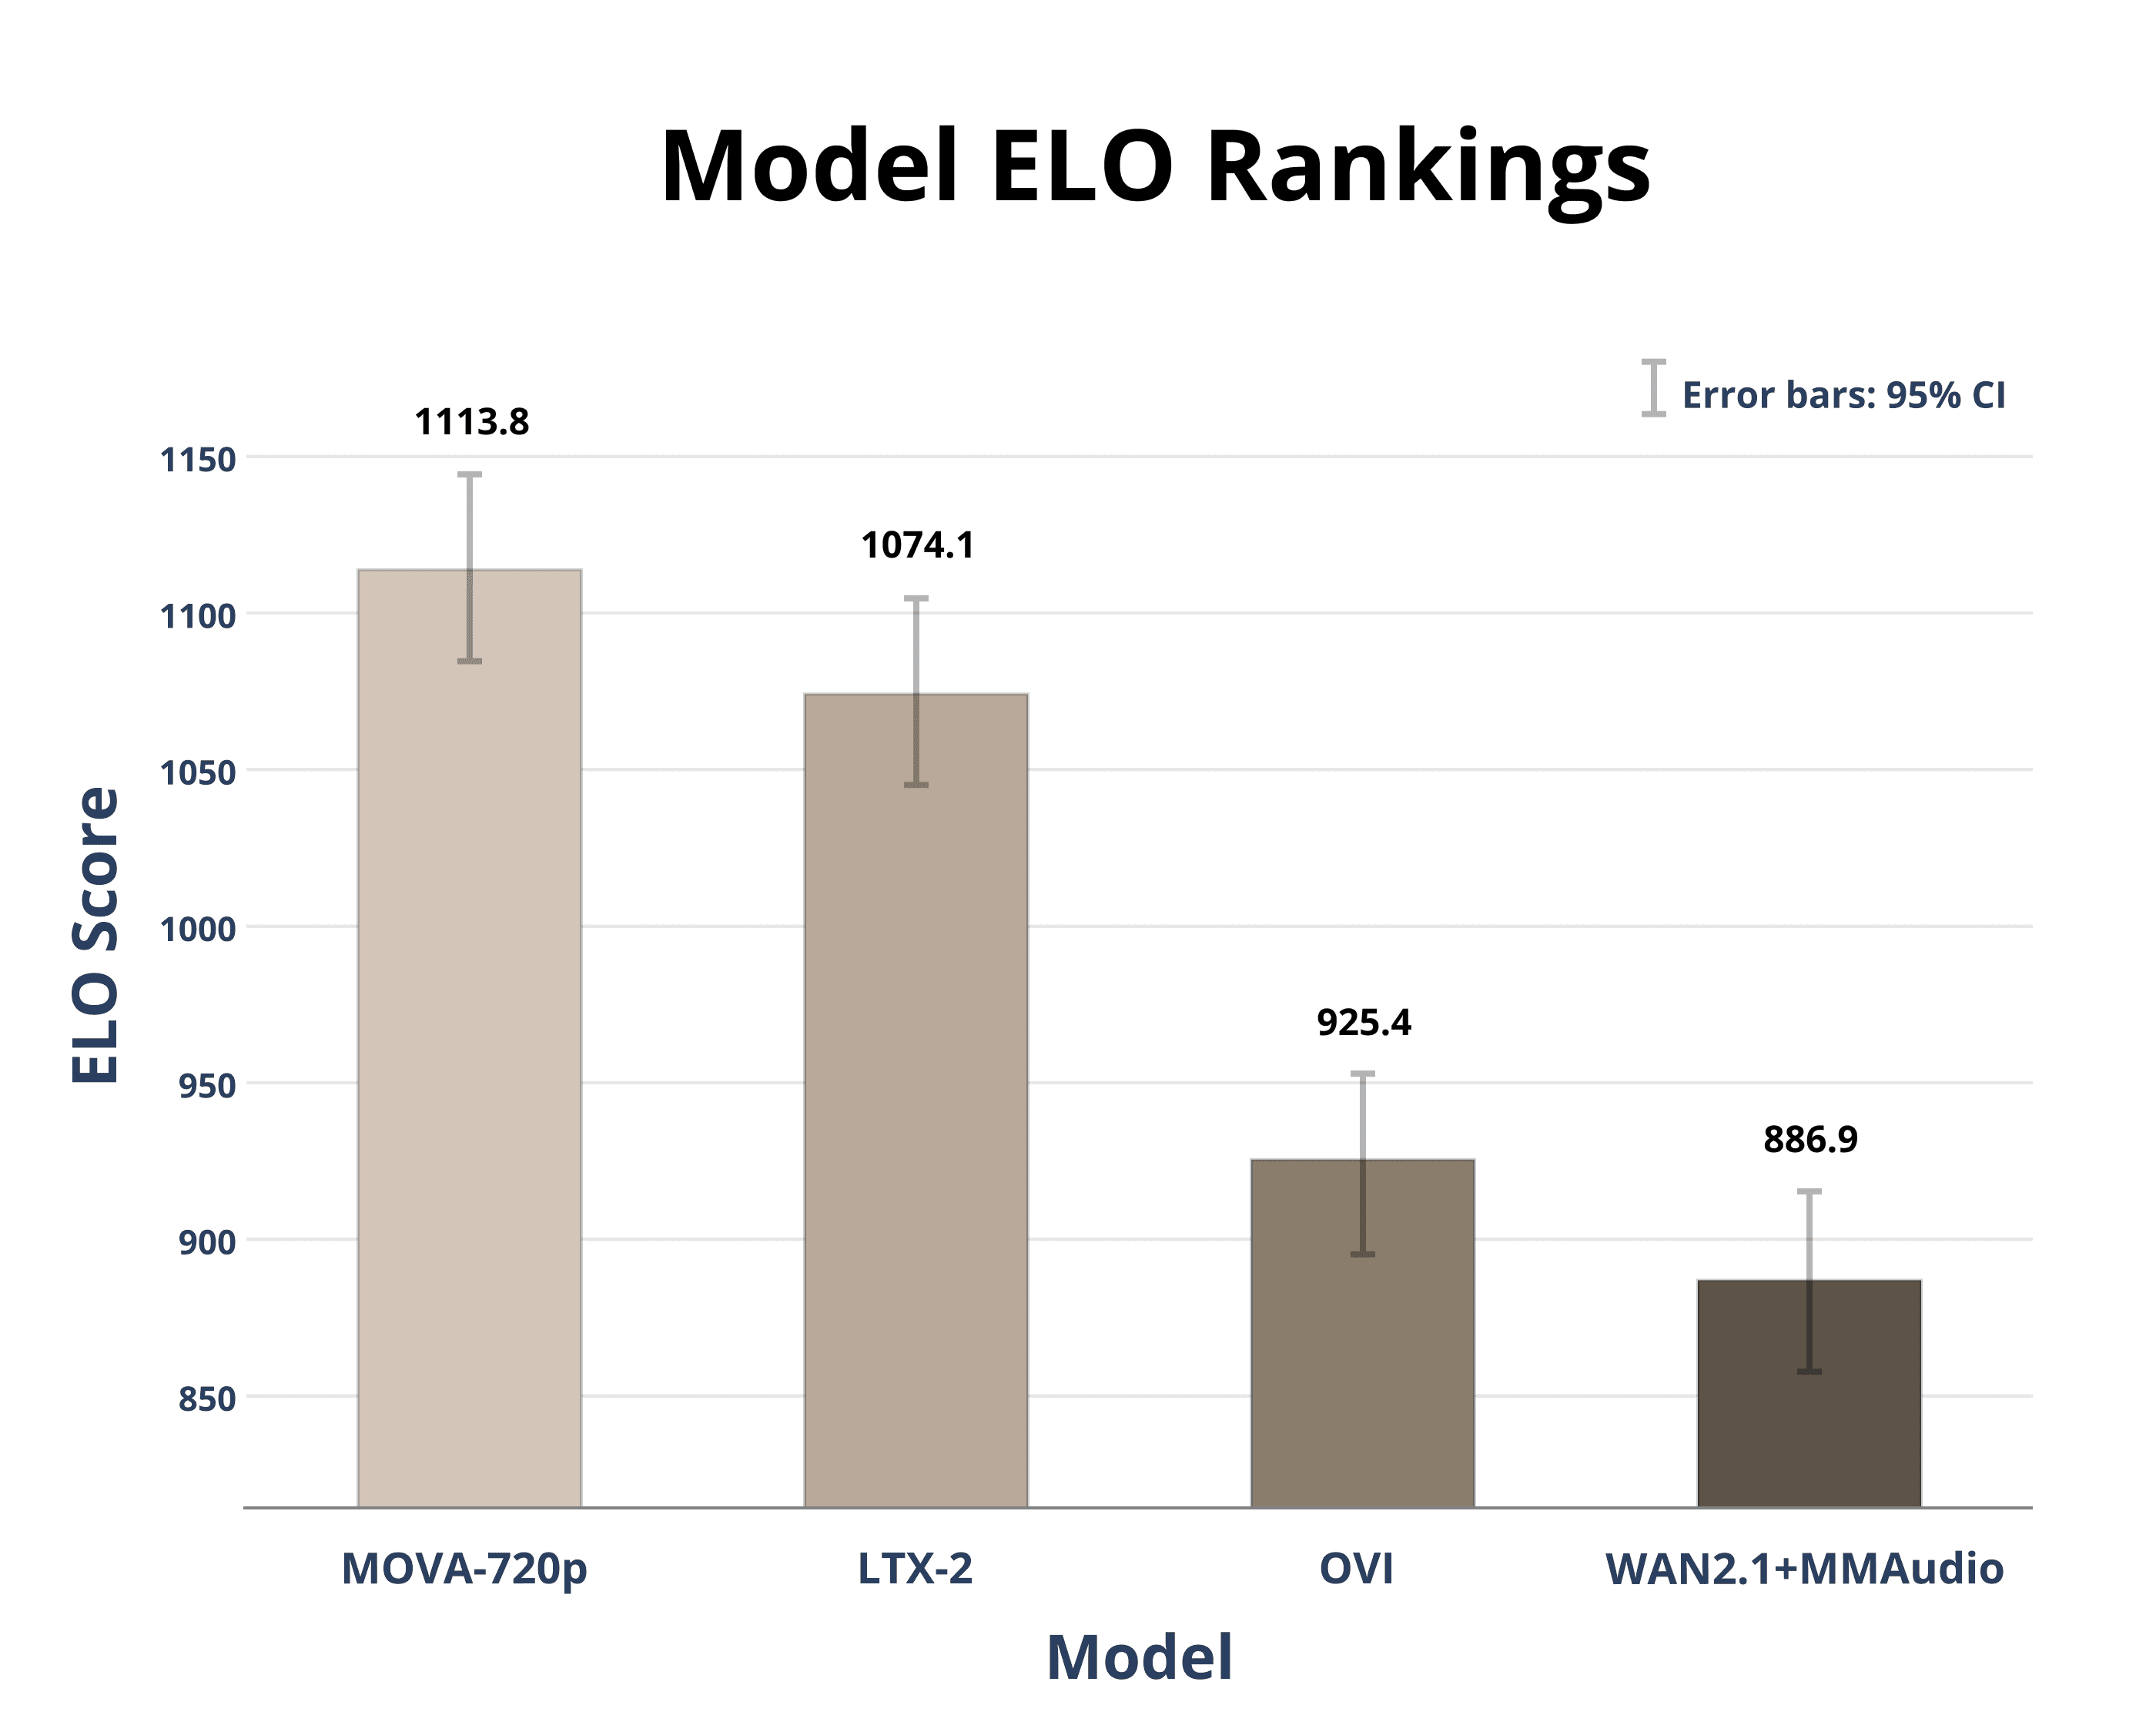
The OpenMOSS team has released MOVA 720p, a new model for generating video with synchronized audio. Unlike many generative tools that rely on a single input type, MOVA is designed for flexible, multimodal prompts, capable of creating high-definition video from text, images, or a combination of both.
This "any-to-any" architecture is the model's key feature. It allows a creator to provide an image as a starting point and then guide the animation with a text prompt, offering more direct control over the subject, action, and style of the final video. The model processes these varied inputs to produce a coherent visual sequence complete with a relevant soundtrack.
Why It Matters
Generating video at a 720p resolution (1280x720) marks a notable step for open multimodal models, which often operate at lower resolutions to manage computational demands. By integrating audio generation and supporting complex prompts, MOVA 720p pushes the capabilities of open-source video synthesis forward, narrowing the gap with proprietary systems from major tech labs.
The model and its components are available for developers to explore on the OpenMOSS team's Hugging Face repository. It is released under a custom license, so users should review the specific terms of use before integrating it into their work.
Sources
- Visit
OpenMOSS-Team/MOVA-720p
Hugging Face
More from OpenMOSS
All OpenMOSS releases →
OpenMOSS Releases MOSS-Image Under Apache 2.0
The academic team behind the MOSS project moves into text-to-image generation with a permissively licensed model and a fine-tuned SFT variant.
OpenMOSS Releases Apache-2.0 Bilingual Image Model
MOSS-Image Base arrives as a permissively licensed text-to-image foundation with English and Chinese support.
OpenMOSS Debuts MOSS-VL for Real-Time Vision Interaction
A new open vision-language model family uses gated cross-attention to enable streaming, low-latency multimodal exchanges.
More in Any-to-Any
All Any-to-Any →
Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.

MiniMax Debuts M3.1 Flash, a Multimodal MoE Model
The new release pairs a mixture-of-experts design with agentic, coding, and video-understanding abilities in a single open model.
IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.
0 comments
No comments yet. Be the first to weigh in.