OpenBMB Releases 'Any-to-Any' Multimodal Model
The new MiniCPM-o 4.5 model from the open-source research group can process and generate interleaved combinations of images, text, and audio.
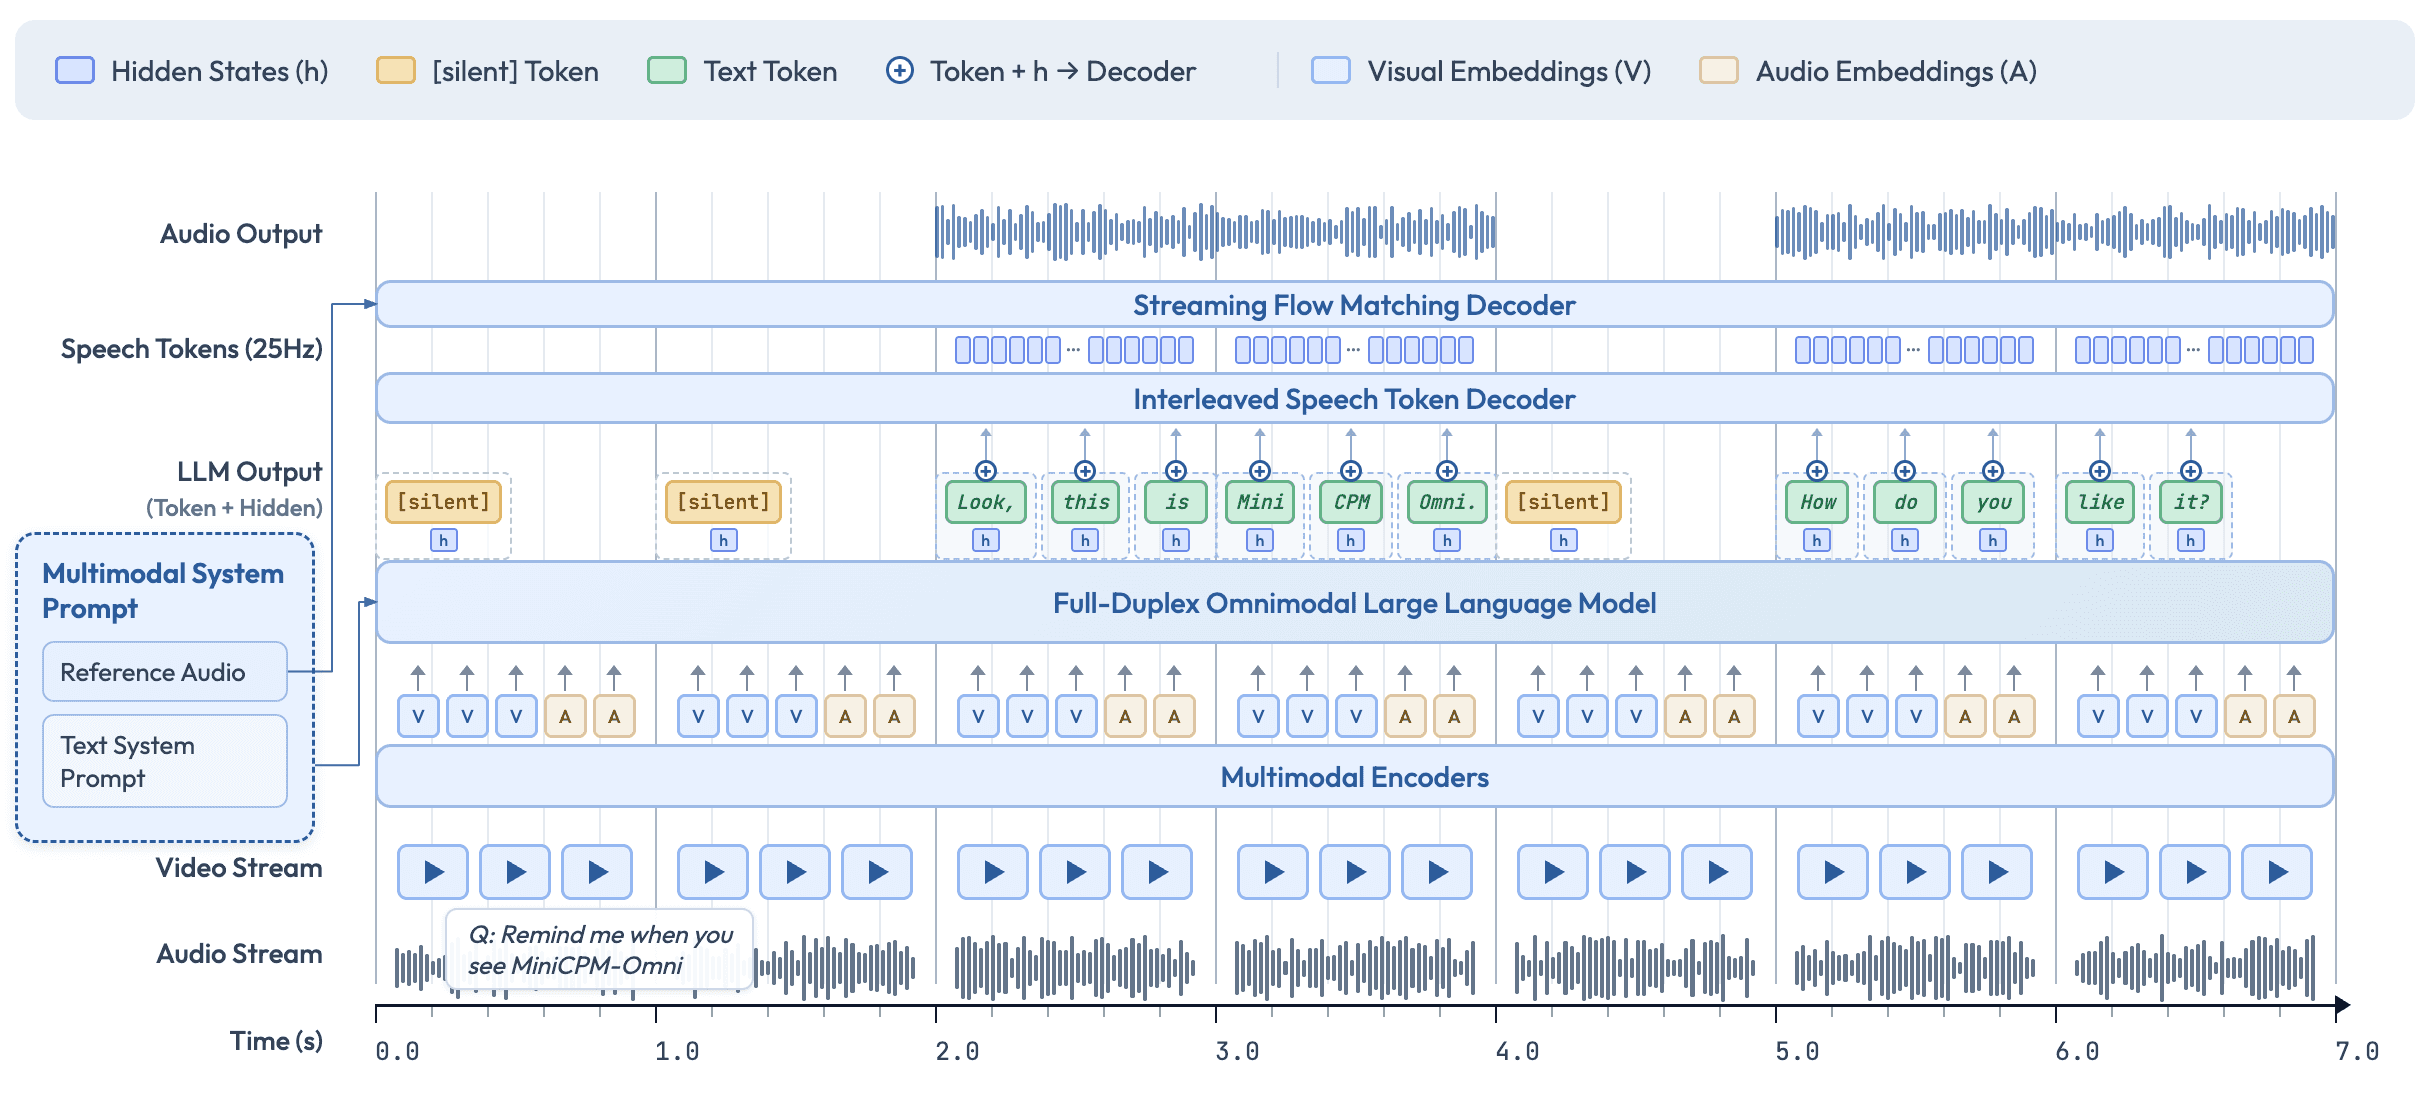
The open-source AI community OpenBMB has released MiniCPM-o 4.5, a new model that significantly expands the possibilities for multimodal interaction. Unlike many models that process one type of input to produce a single type of output, MiniCPM-o is designed for "any-to-any" communication, capable of handling a mix of text, images, and audio in a single conversational flow.
This approach aims to create more natural and fluid interactions with AI. The model's "full-duplex" support suggests it can understand interleaved inputs—for example, a user could provide an image, ask a question in text, and follow up with a spoken clarification. In response, the model could generate its own combination of text, a new image, and synthesized speech.
Why It Matters
This release represents a move beyond simple, turn-based tasks like image captioning. It points toward AI systems that can participate in dynamic, multi-format conversations. By handling various data streams simultaneously, MiniCPM-o could power more sophisticated applications in areas like:
- Interactive educational tools
- Advanced accessibility software
- Complex creative and design assistants
While technical details like parameter count were not specified in the release record, the model's architecture itself is the key development. Researchers can explore its capabilities directly, as it is available on Hugging Face. The model provides an open-source foundation for building the next generation of conversational AI agents.
Sources
- Visit
openbmb/MiniCPM-o-4_5
Hugging Face
More from OpenBMB
All OpenBMB releases →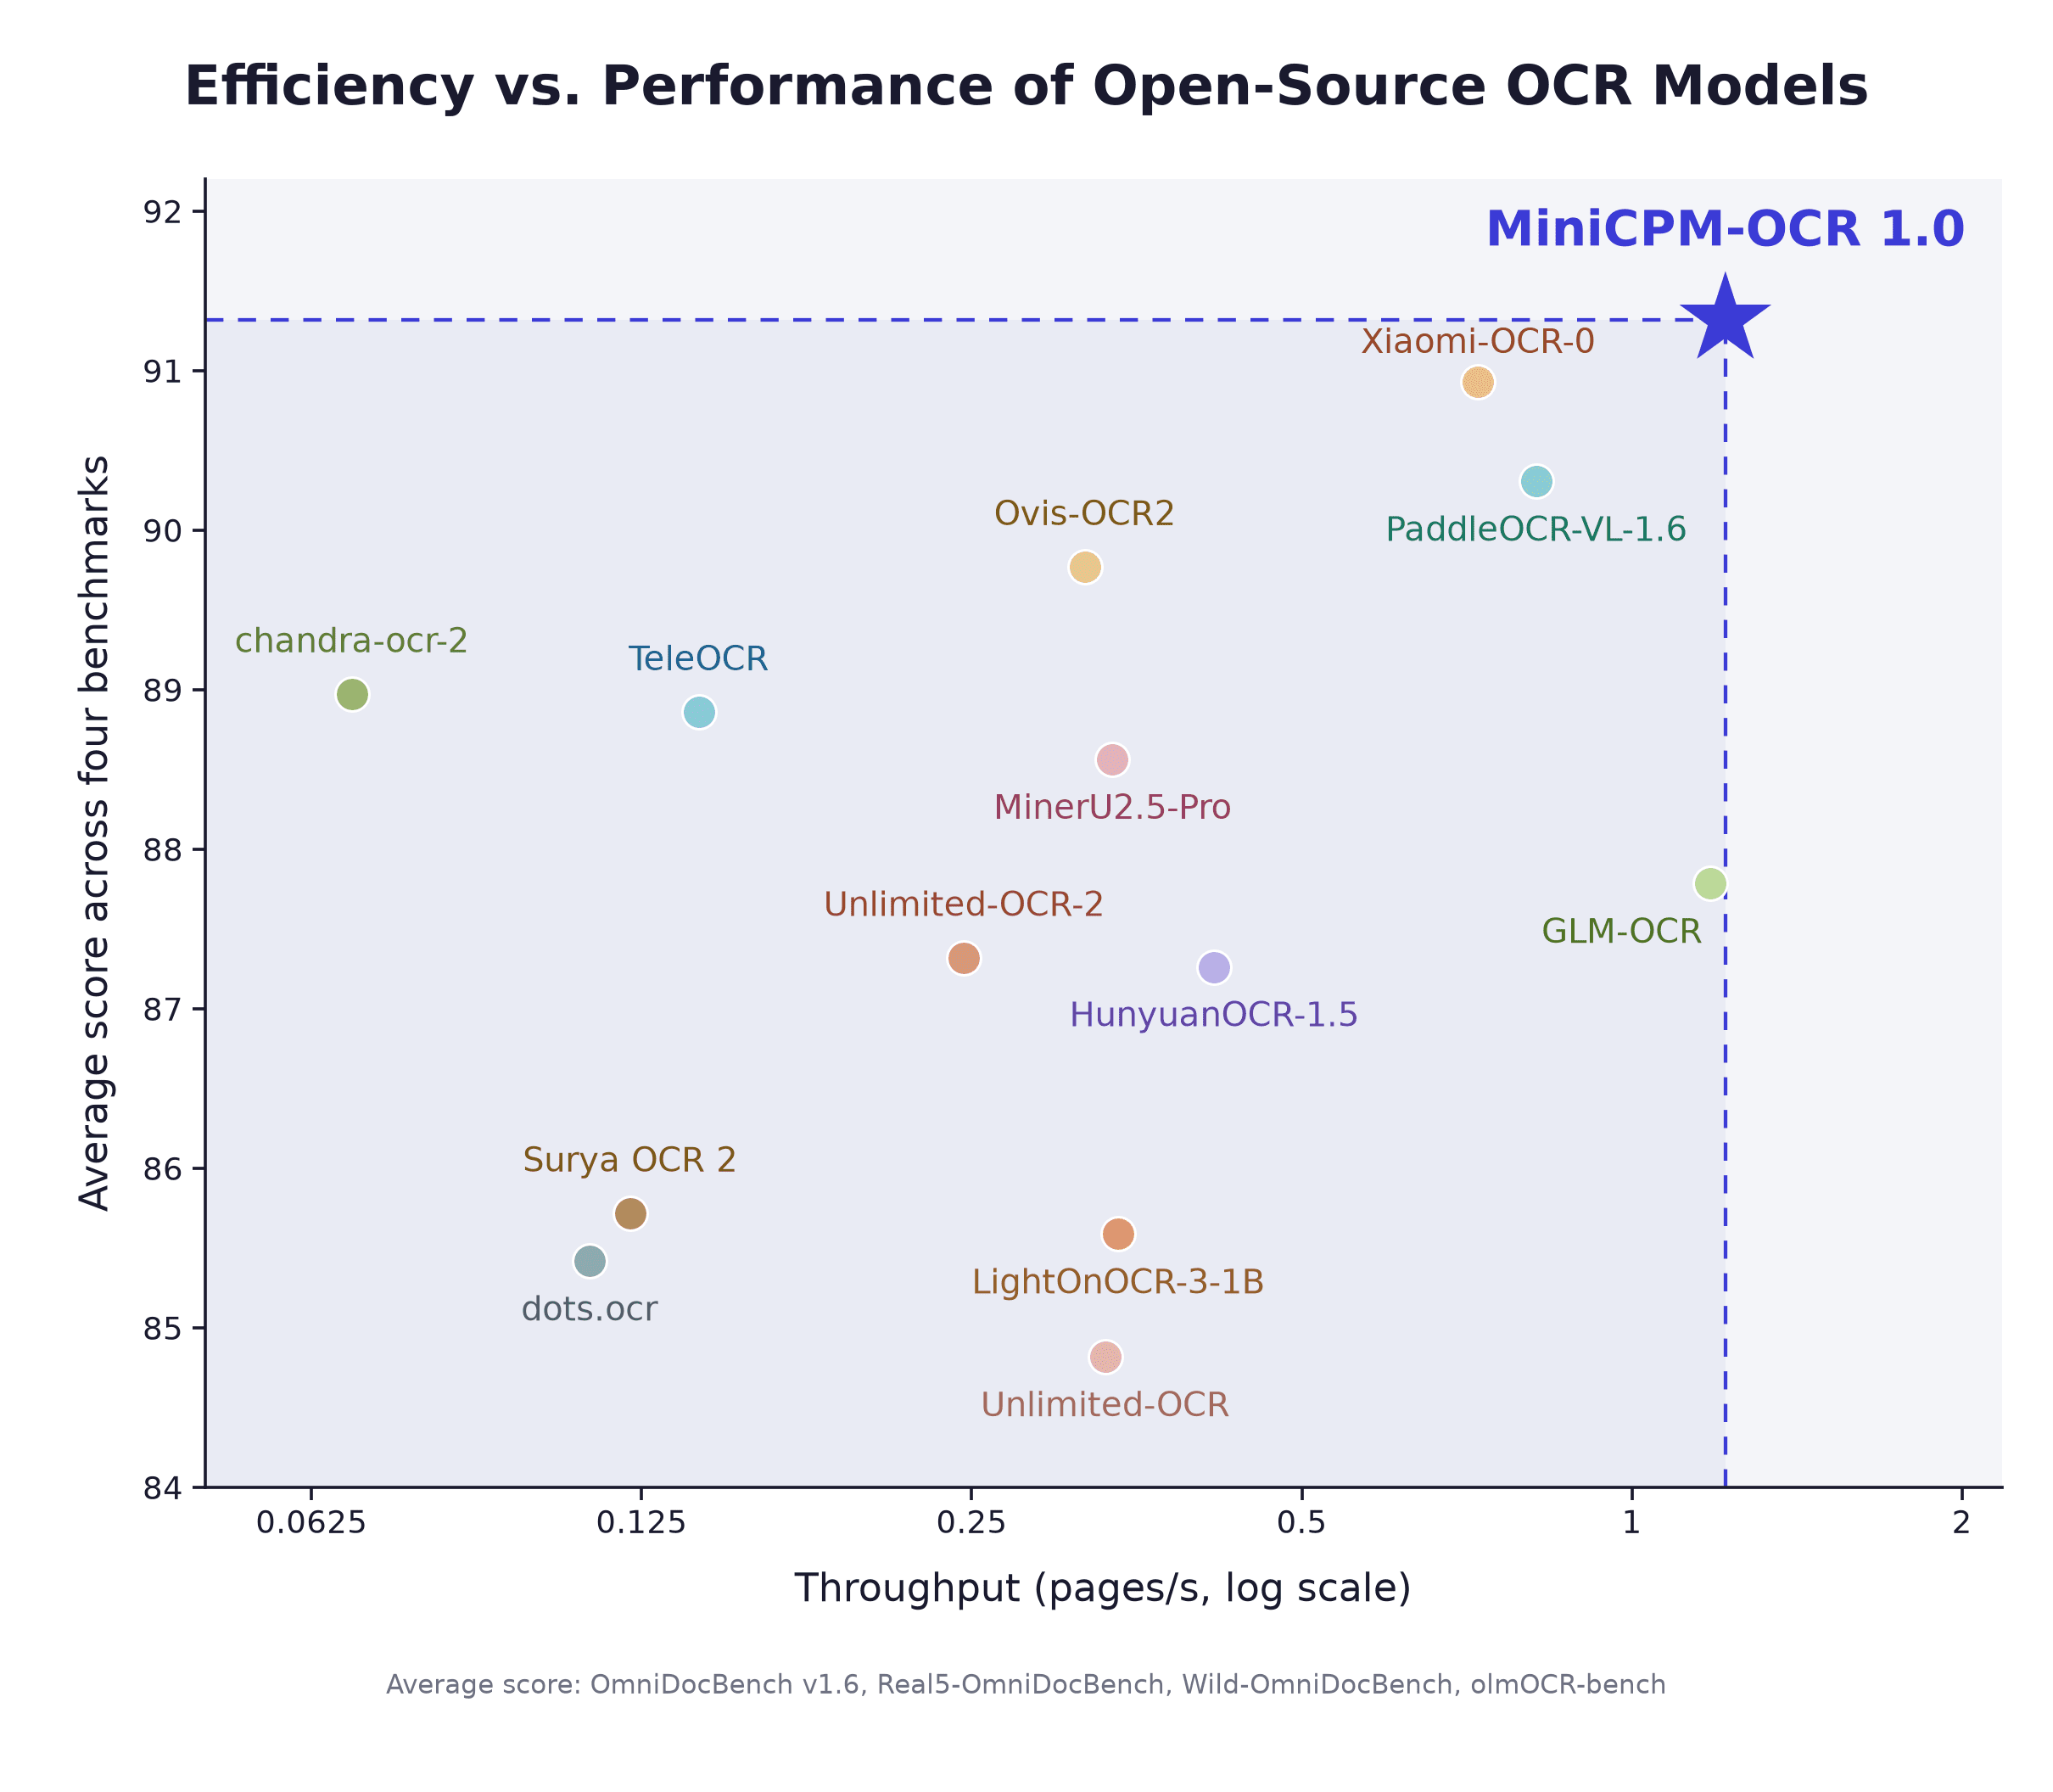
OpenBMB's MiniCPM-OCR 1.0 Targets Document Parsing
A compact vision-language model built to read tables, formulas, and complex page layouts arrives on Hugging Face.
OpenBMB's MiniCPM-V 4.7 brings MoE to vision models
The new 35B-parameter vision-language model activates just 3B parameters per pass, aiming for efficiency without sacrificing capability.
MiniCPM-V 4.7 brings a 35B MoE vision model on-device
OpenBMB's latest multimodal release activates just 3B parameters per token, aiming to keep capable image understanding local.
More in Any-to-Any
All Any-to-Any →
Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.

MiniMax Debuts M3.1 Flash, a Multimodal MoE Model
The new release pairs a mixture-of-experts design with agentic, coding, and video-understanding abilities in a single open model.
IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.
0 comments
No comments yet. Be the first to weigh in.