Microsoft Releases Fara-7B Vision Agent Model
The 7-billion-parameter model is designed to understand and interact with graphical user interfaces, building on Alibaba's open-source Qwen2.5-VL.
Microsoft has introduced Fara-7B, a new 7-billion-parameter vision-language model aimed at a specific and challenging task: controlling a computer. Unlike general-purpose multimodal models, Fara-7B is designed to function as an agent, interpreting graphical user interfaces (GUIs) to understand and execute tasks.
This specialization allows the model to go beyond simply describing what's on a screen. The goal is for Fara-7B to comprehend the layout, elements, and interactive possibilities within an application, paving the way for more sophisticated AI-powered automation and assistance.
Interestingly, Fara-7B is not built from the ground up. According to its official model card, the model is based on Alibaba's recently released Qwen2.5-VL. This approach highlights a growing trend of major AI labs building upon and refining foundational models released by others, accelerating the pace of innovation across the open-source community.
Why it matters
The release of specialized agent models like Fara-7B under a permissive MIT license provides a powerful building block for developers. It opens up new possibilities for creating advanced accessibility tools, automating repetitive software tasks, and developing more capable personal AI assistants that can interact with technology the same way humans do: by seeing and clicking.
Sources
- Visit
microsoft/Fara-7B
Hugging Face
More from Microsoft
All Microsoft releases →
Microsoft's Mage-VL-Cowork takes on computer-use tasks
A new vision-language agent model aims to operate GUIs, write code, and work the terminal.
Microsoft Releases FrogNano-4B Under MIT License
The compact 4-billion-parameter text model lands on Hugging Face with a permissive license aimed at developers.
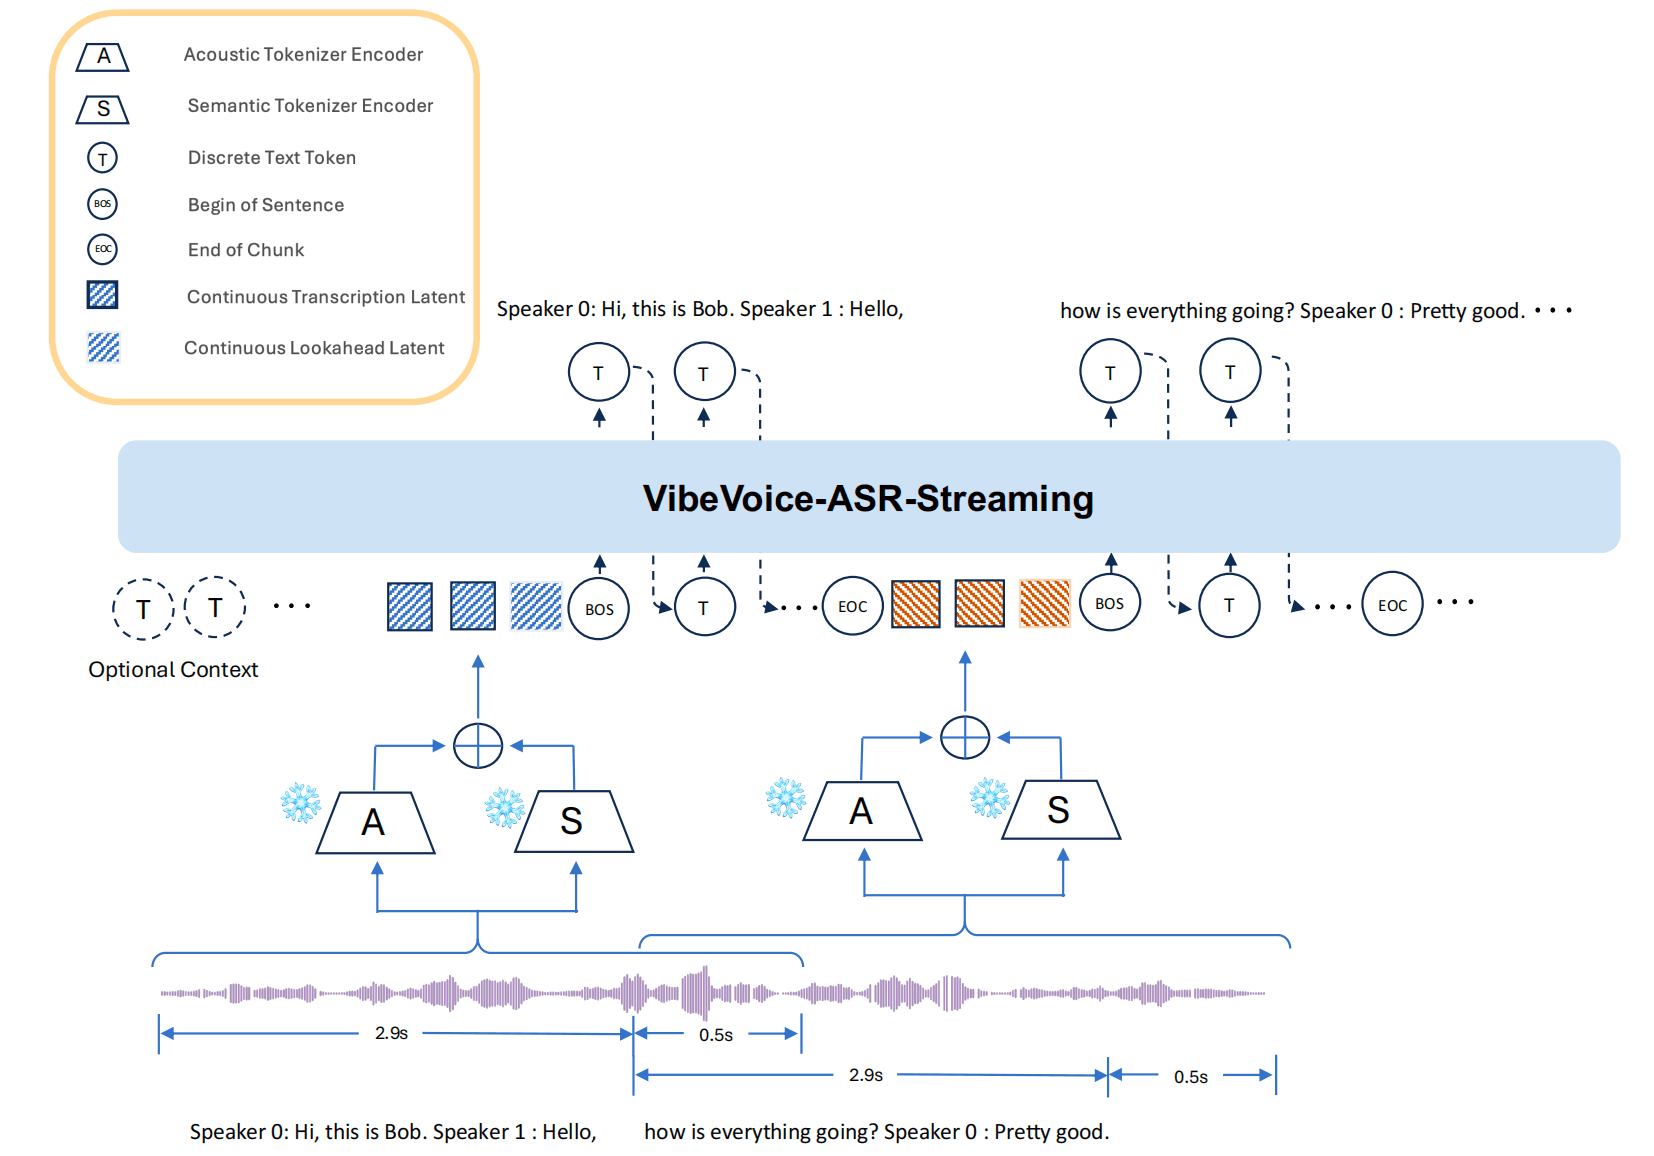
Microsoft's VibeVoice ASR brings streaming speech-to-text
A 7-billion-parameter model targets real-time, multilingual transcription with an open release on Hugging Face.
More in Vision-Language
All Vision-Language →
Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Baidu releases Unlimited-OCR 2 under MIT license
The multilingual vision-language model targets document text recognition and ships with a permissive license for commercial use.

Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.
0 comments
No comments yet. Be the first to weigh in.