dots3-note preview brings audio and vision to one model
An early build of a multimodal, long-context agentic system arrives on Hugging Face with support for both images and sound.
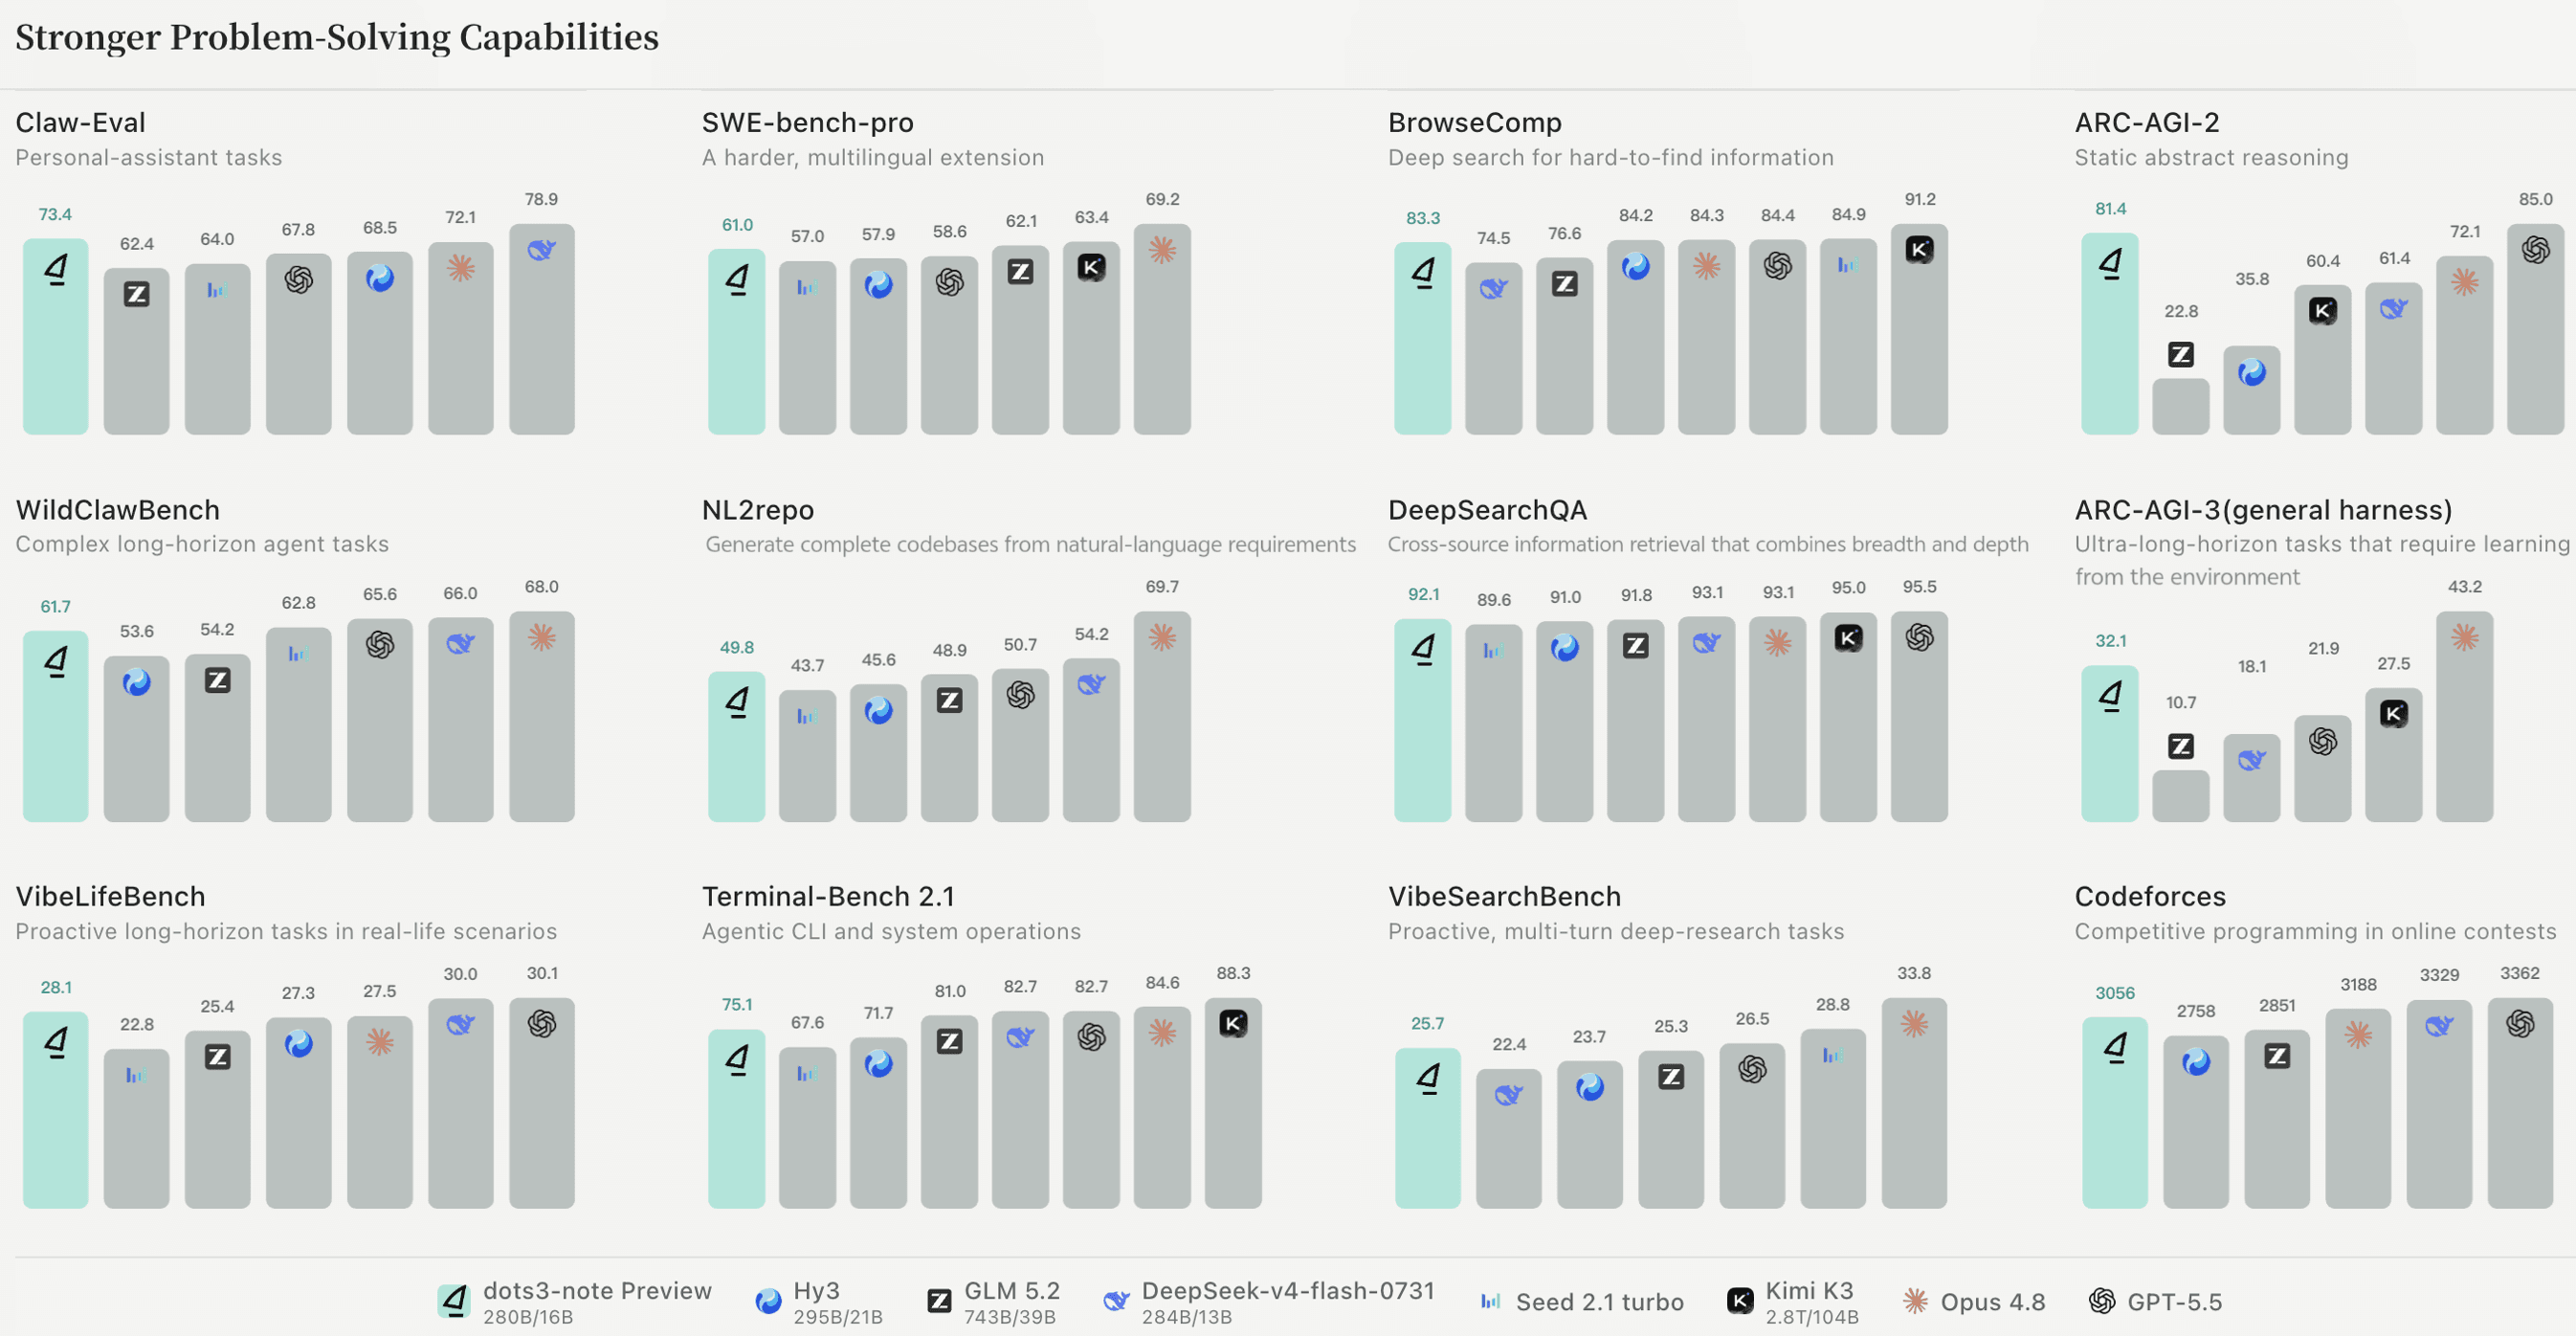
dots-studio has published an early preview of dots3-note, a multimodal model designed to handle images, audio, and text within a single long-context, agentic framework. The release is available now on Hugging Face.
The model is described as "multimodal-any," meaning it aims to accept a range of input types rather than specializing in a single one. Vision-language capabilities sit alongside audio understanding, positioning dots3-note as a general-purpose system for tasks that blend perception with reasoning.
What we know
- Multimodal support spanning vision and audio, plus text
- A long-context, agentic design intended for multi-step tasks
- Distributed under a non-standard "other" license
- Published as a preview, so specifications may still shift
Key technical details remain unpublished at this stage. The record lists no confirmed parameter count, context length, or benchmark results, and the license is marked simply as "other" — worth checking carefully before any commercial use.
Why it matters: Combining audio and vision in one openly available agentic model is still relatively uncommon, and preview releases like this offer early hands-on access for developers experimenting with cross-modal workflows. As with any preview, expect the details to firm up as the family matures.
Sources
- Visit
dots-studio/dots3-note-prev
Hugging Face
More in Any-to-Any
All Any-to-Any →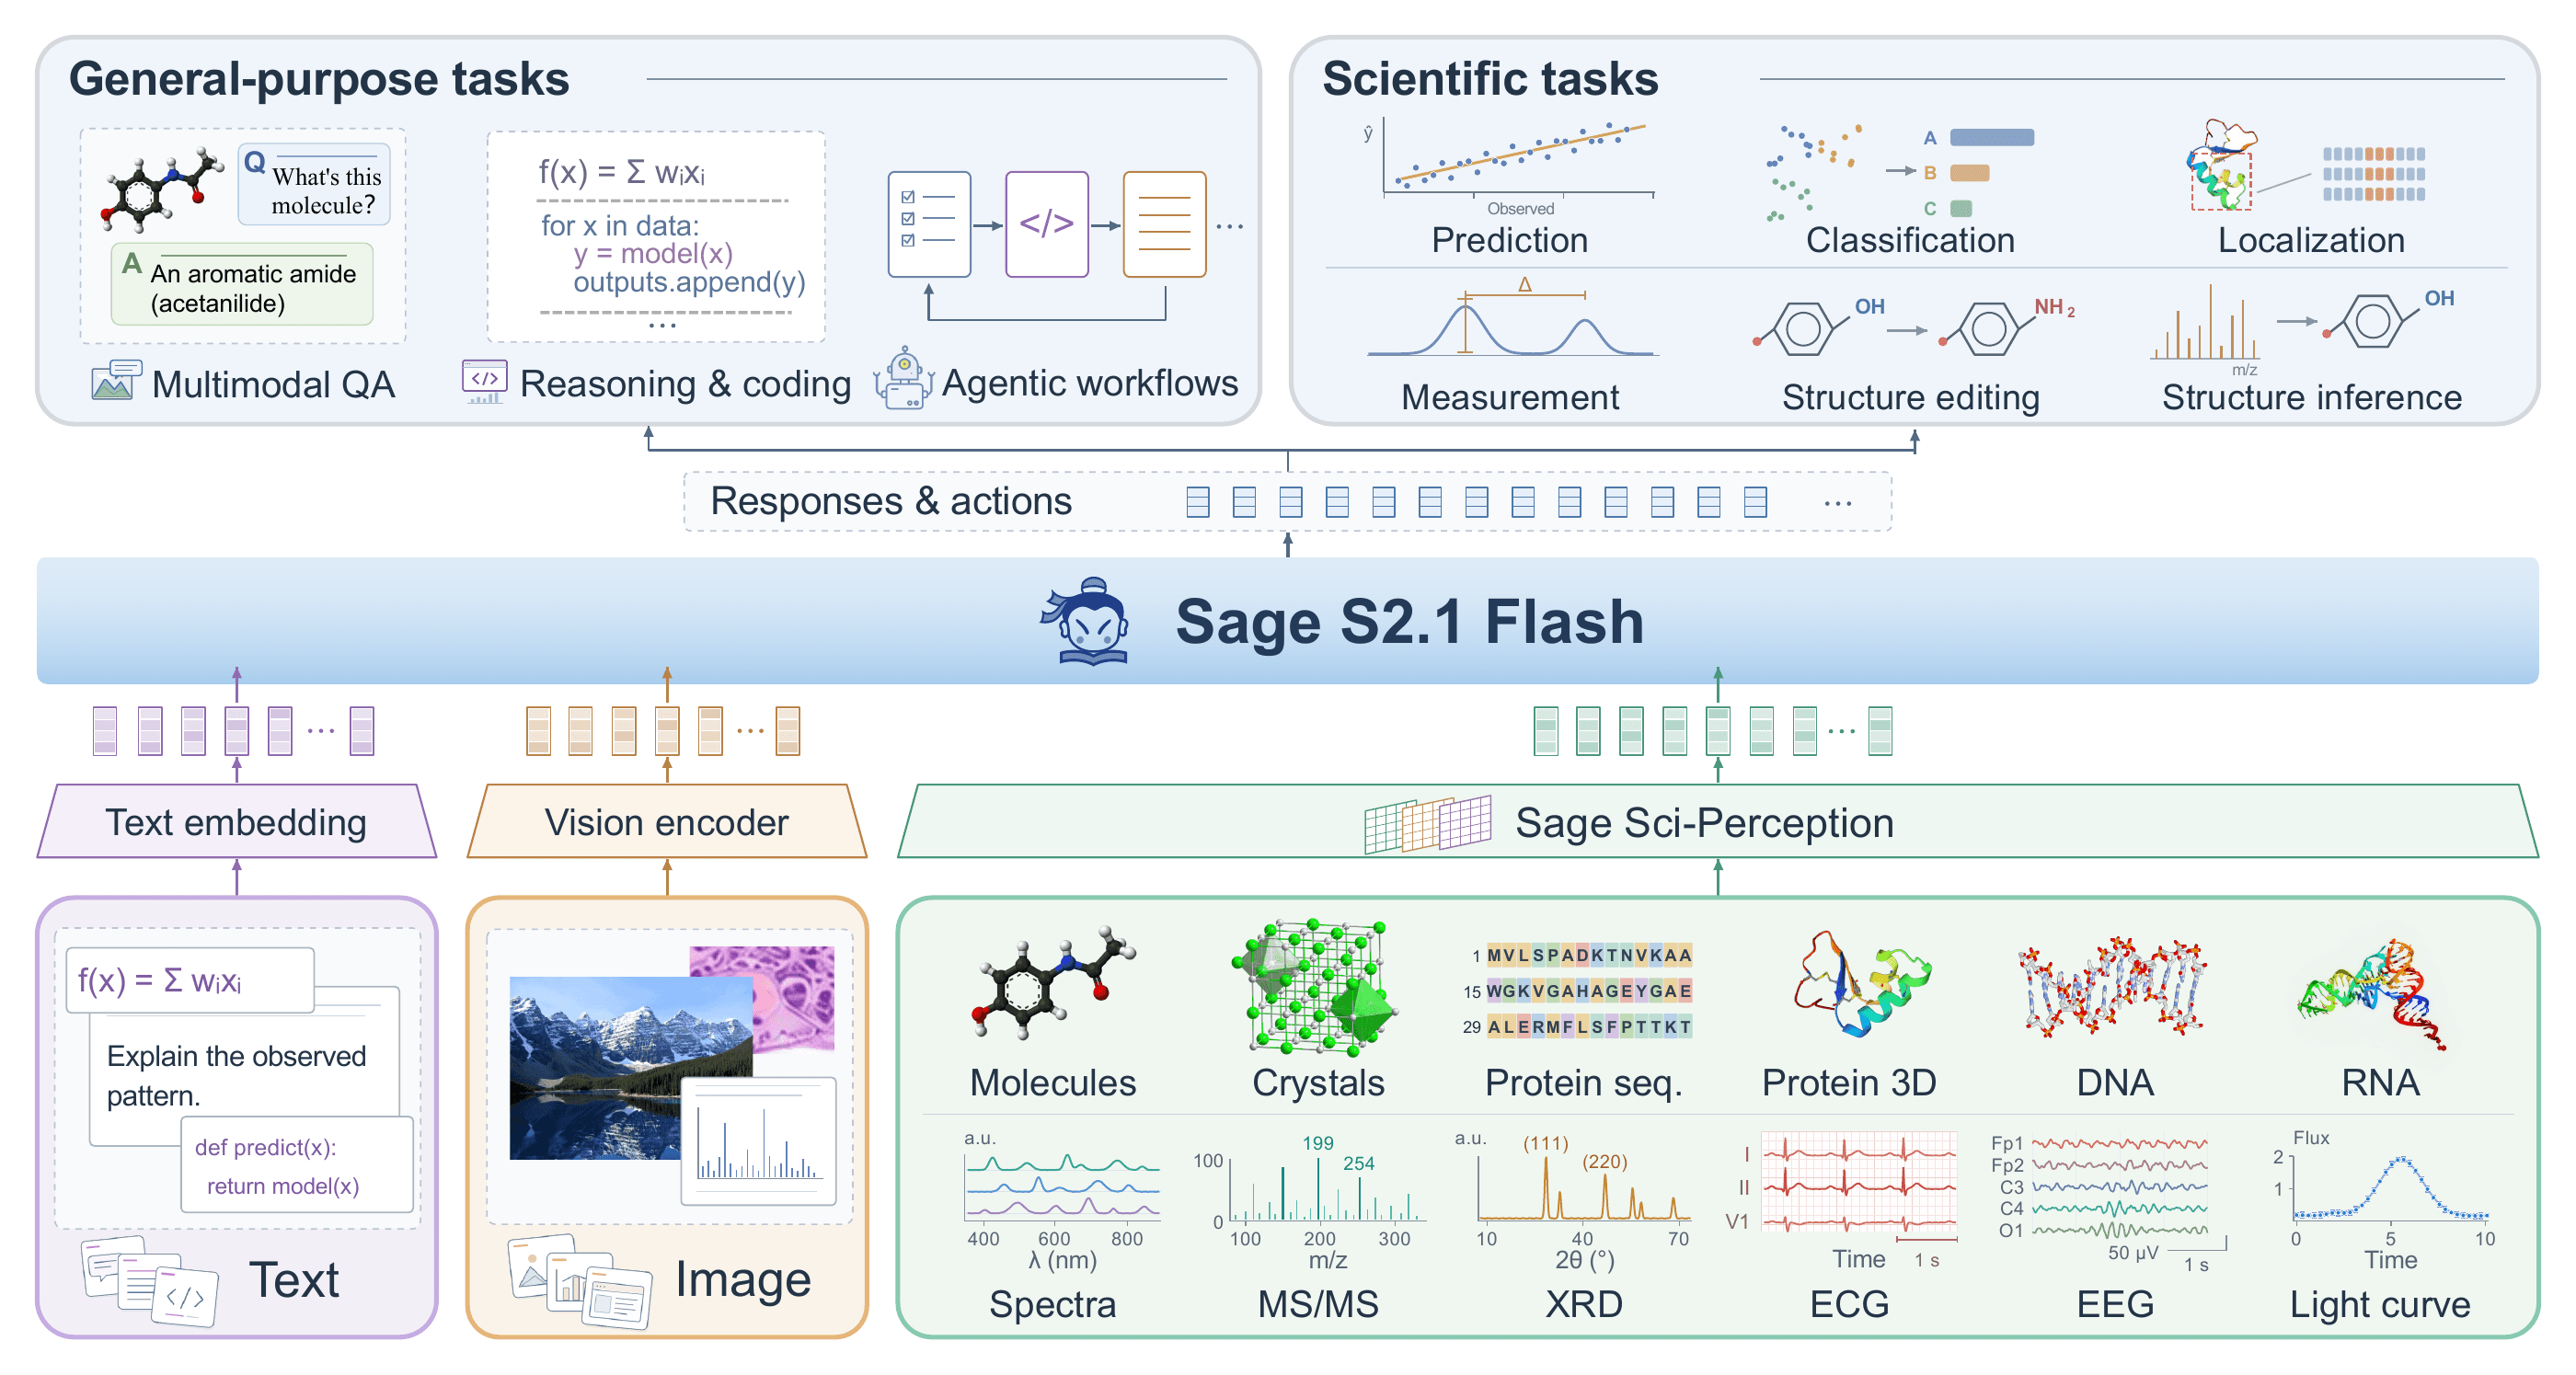
InternLM's Sage S2.1 Flash targets scientific reasoning
The 320B mixture-of-experts model is built to reason over scientific evidence and act inside interactive environments.

Haru-4B Brings Full-Duplex Speech to Six Languages
A compact 4-billion-parameter model handles real-time, two-way voice conversation across six languages in a single system.
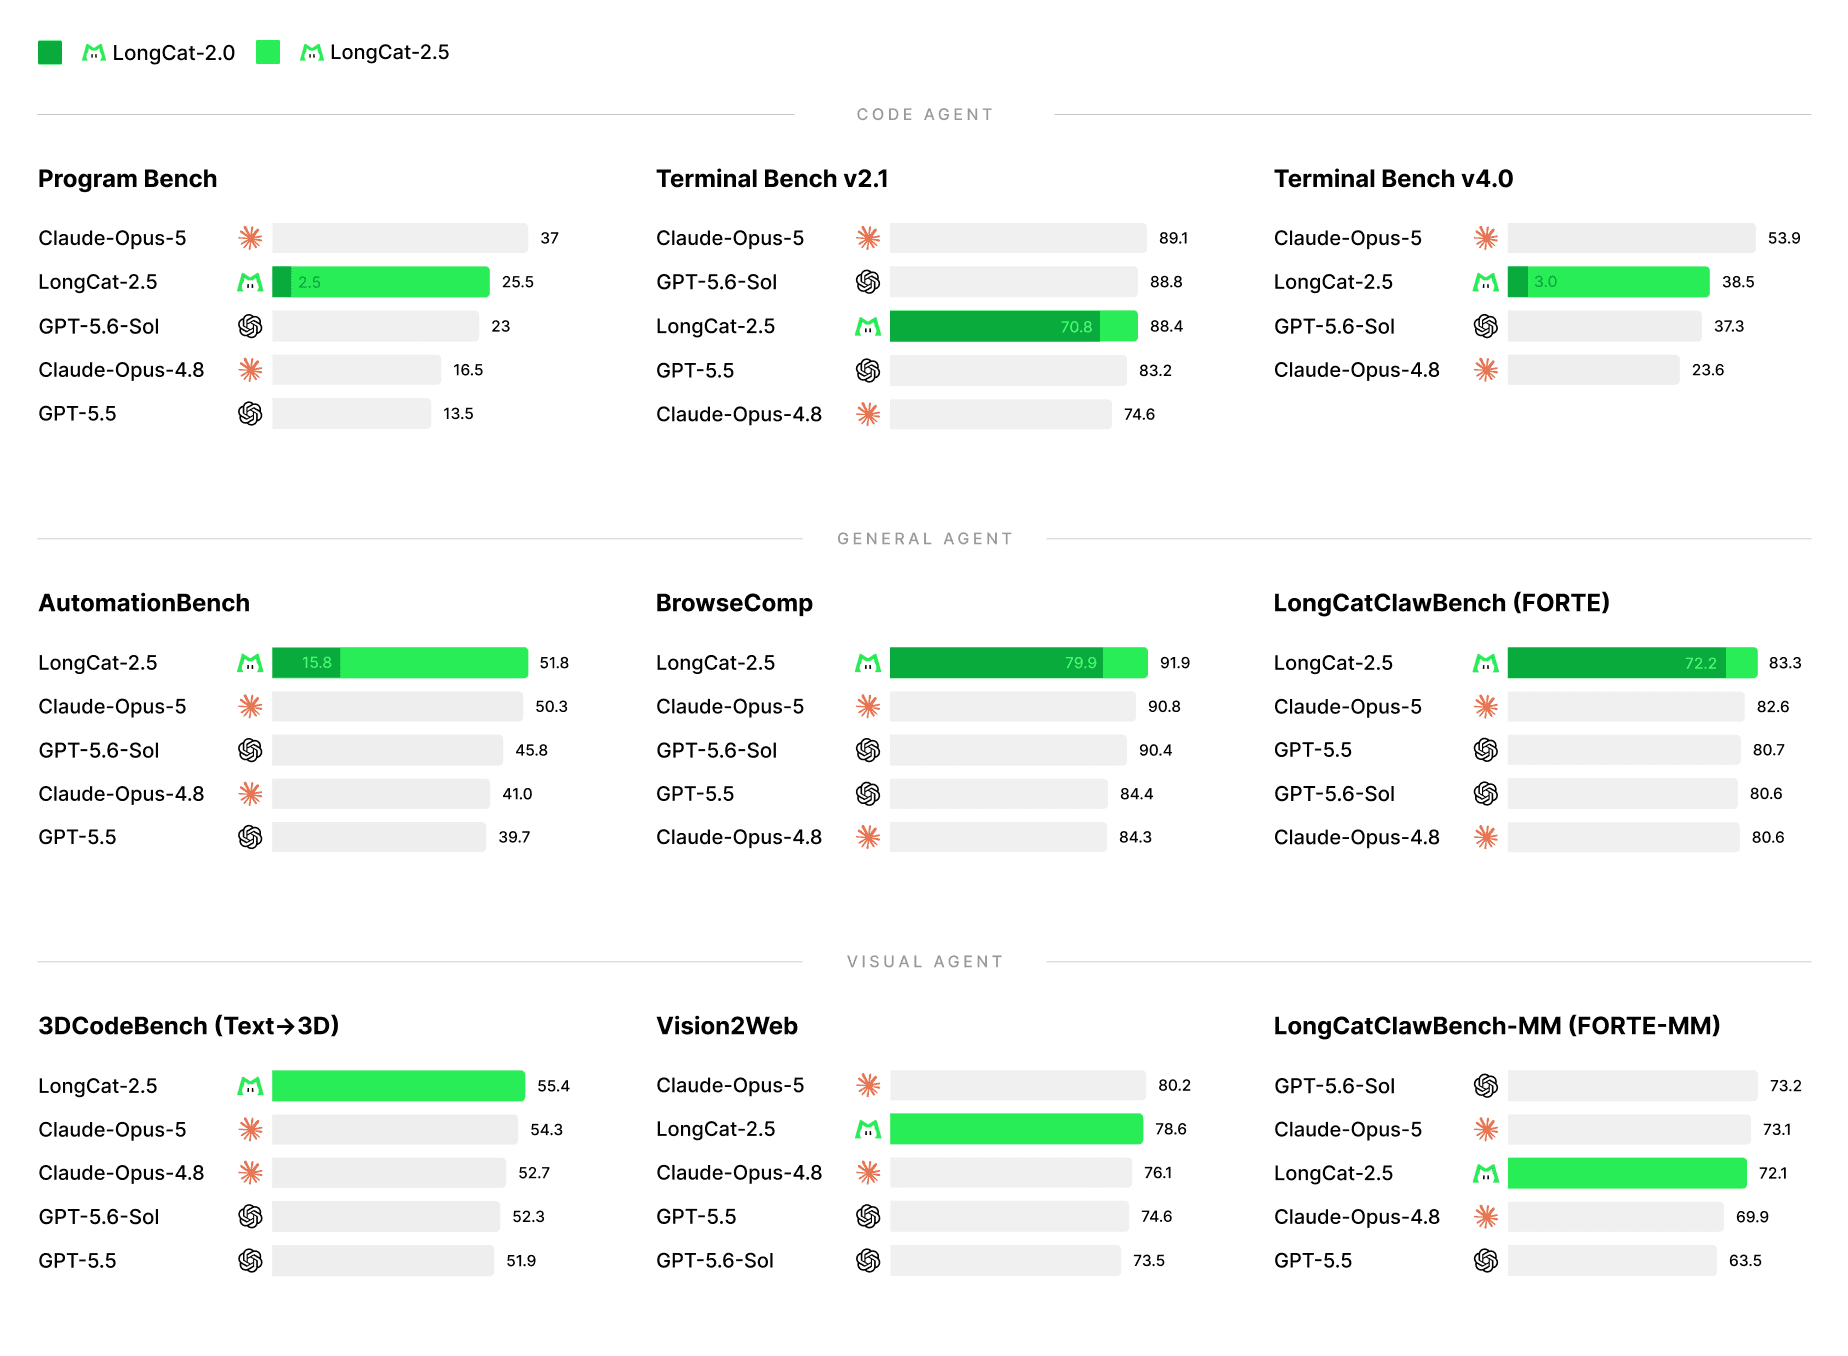
Meituan Releases LongCat 2.5, an MIT-Licensed MoE
The Chinese delivery giant expands its open-model push with a multimodal, agentic mixture-of-experts system.
0 comments
No comments yet. Be the first to weigh in.