DeepSeek-OCR-2 Tackles Multilingual Document AI
The new open vision-language model is designed to extract text and understand structure from complex, multilingual documents.
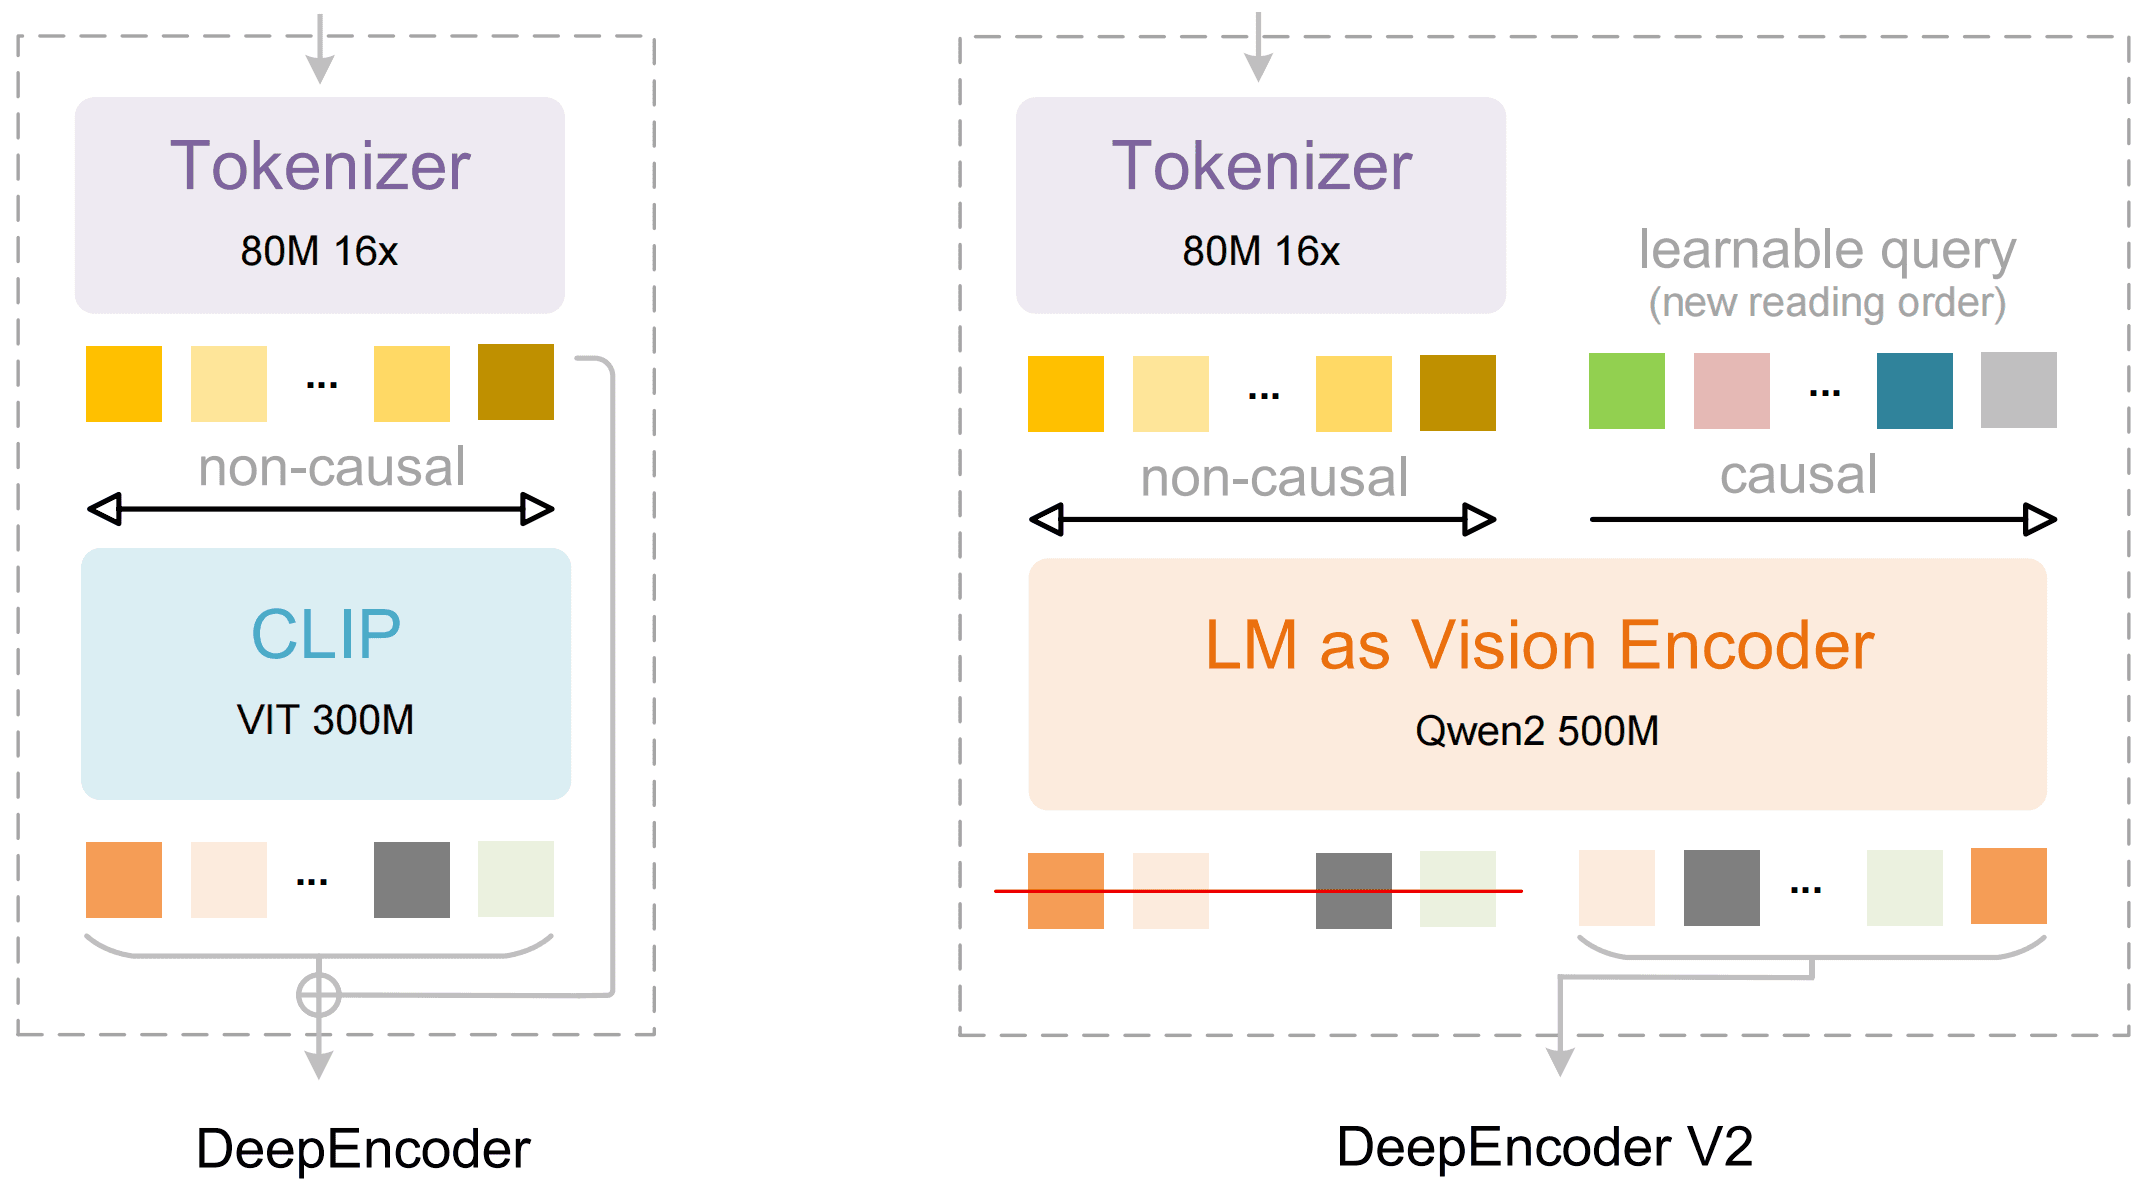
AI company DeepSeek has released DeepSeek-OCR-2, a powerful vision-language model specialized for Optical Character Recognition (OCR). The model is designed to go beyond simple text extraction, aiming to provide a deeper understanding of document structure and content across multiple languages.
Unlike traditional OCR tools that follow a rigid pipeline, DeepSeek-OCR-2 operates as a vision-language model. It processes an image of a document and a user's prompt to generate structured output, allowing it to handle complex layouts, tables, and mixed-language text found in real-world documents like invoices, forms, and academic papers.
A New Open Alternative
The release of DeepSeek-OCR-2 on Hugging Face provides developers with a strong open-source alternative to proprietary document intelligence APIs from major cloud providers. Its key capabilities include:
- Multilingual Support: Handles a wide range of languages within the same document.
- Layout Understanding: Recognizes and preserves the structure of tables and multi-column text.
- Versatility: Processes both scanned and digitally-born documents effectively.
The model is available under a custom license that permits commercial use, though it includes restrictions against using the model to create competing products. This move gives developers and businesses a new, powerful tool for building applications that require sophisticated document processing without relying on closed, pay-per-use services.
Sources
- Visit
deepseek-ai/DeepSeek-OCR-2
Hugging Face
More from DeepSeek
All DeepSeek releases →
DeepSeek V4.1-Flash Adds Vision and Reasoning
The new MIT-licensed checkpoint folds image understanding and reasoning into DeepSeek's fast, mixture-of-experts Flash line.

DeepSeek adds vision to its V4 Flash line
An experimental, MIT-licensed vision-language model brings image understanding to DeepSeek's fast V4 Flash architecture.
DeepSeek Releases V4-Pro-0813 With Open Weights
The Chinese lab pushes a higher-capability checkpoint of its V4 line to Hugging Face under a permissive MIT license.
More in Vision-Language
All Vision-Language →
Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Baidu releases Unlimited-OCR 2 under MIT license
The multilingual vision-language model targets document text recognition and ships with a permissive license for commercial use.

Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.
0 comments
No comments yet. Be the first to weigh in.