Alibaba Releases Z-Image-Turbo, A Fast Open Image Model
The new text-to-image model from the team behind Qwen uses a diffusion transformer to generate high-resolution images in just a single step.
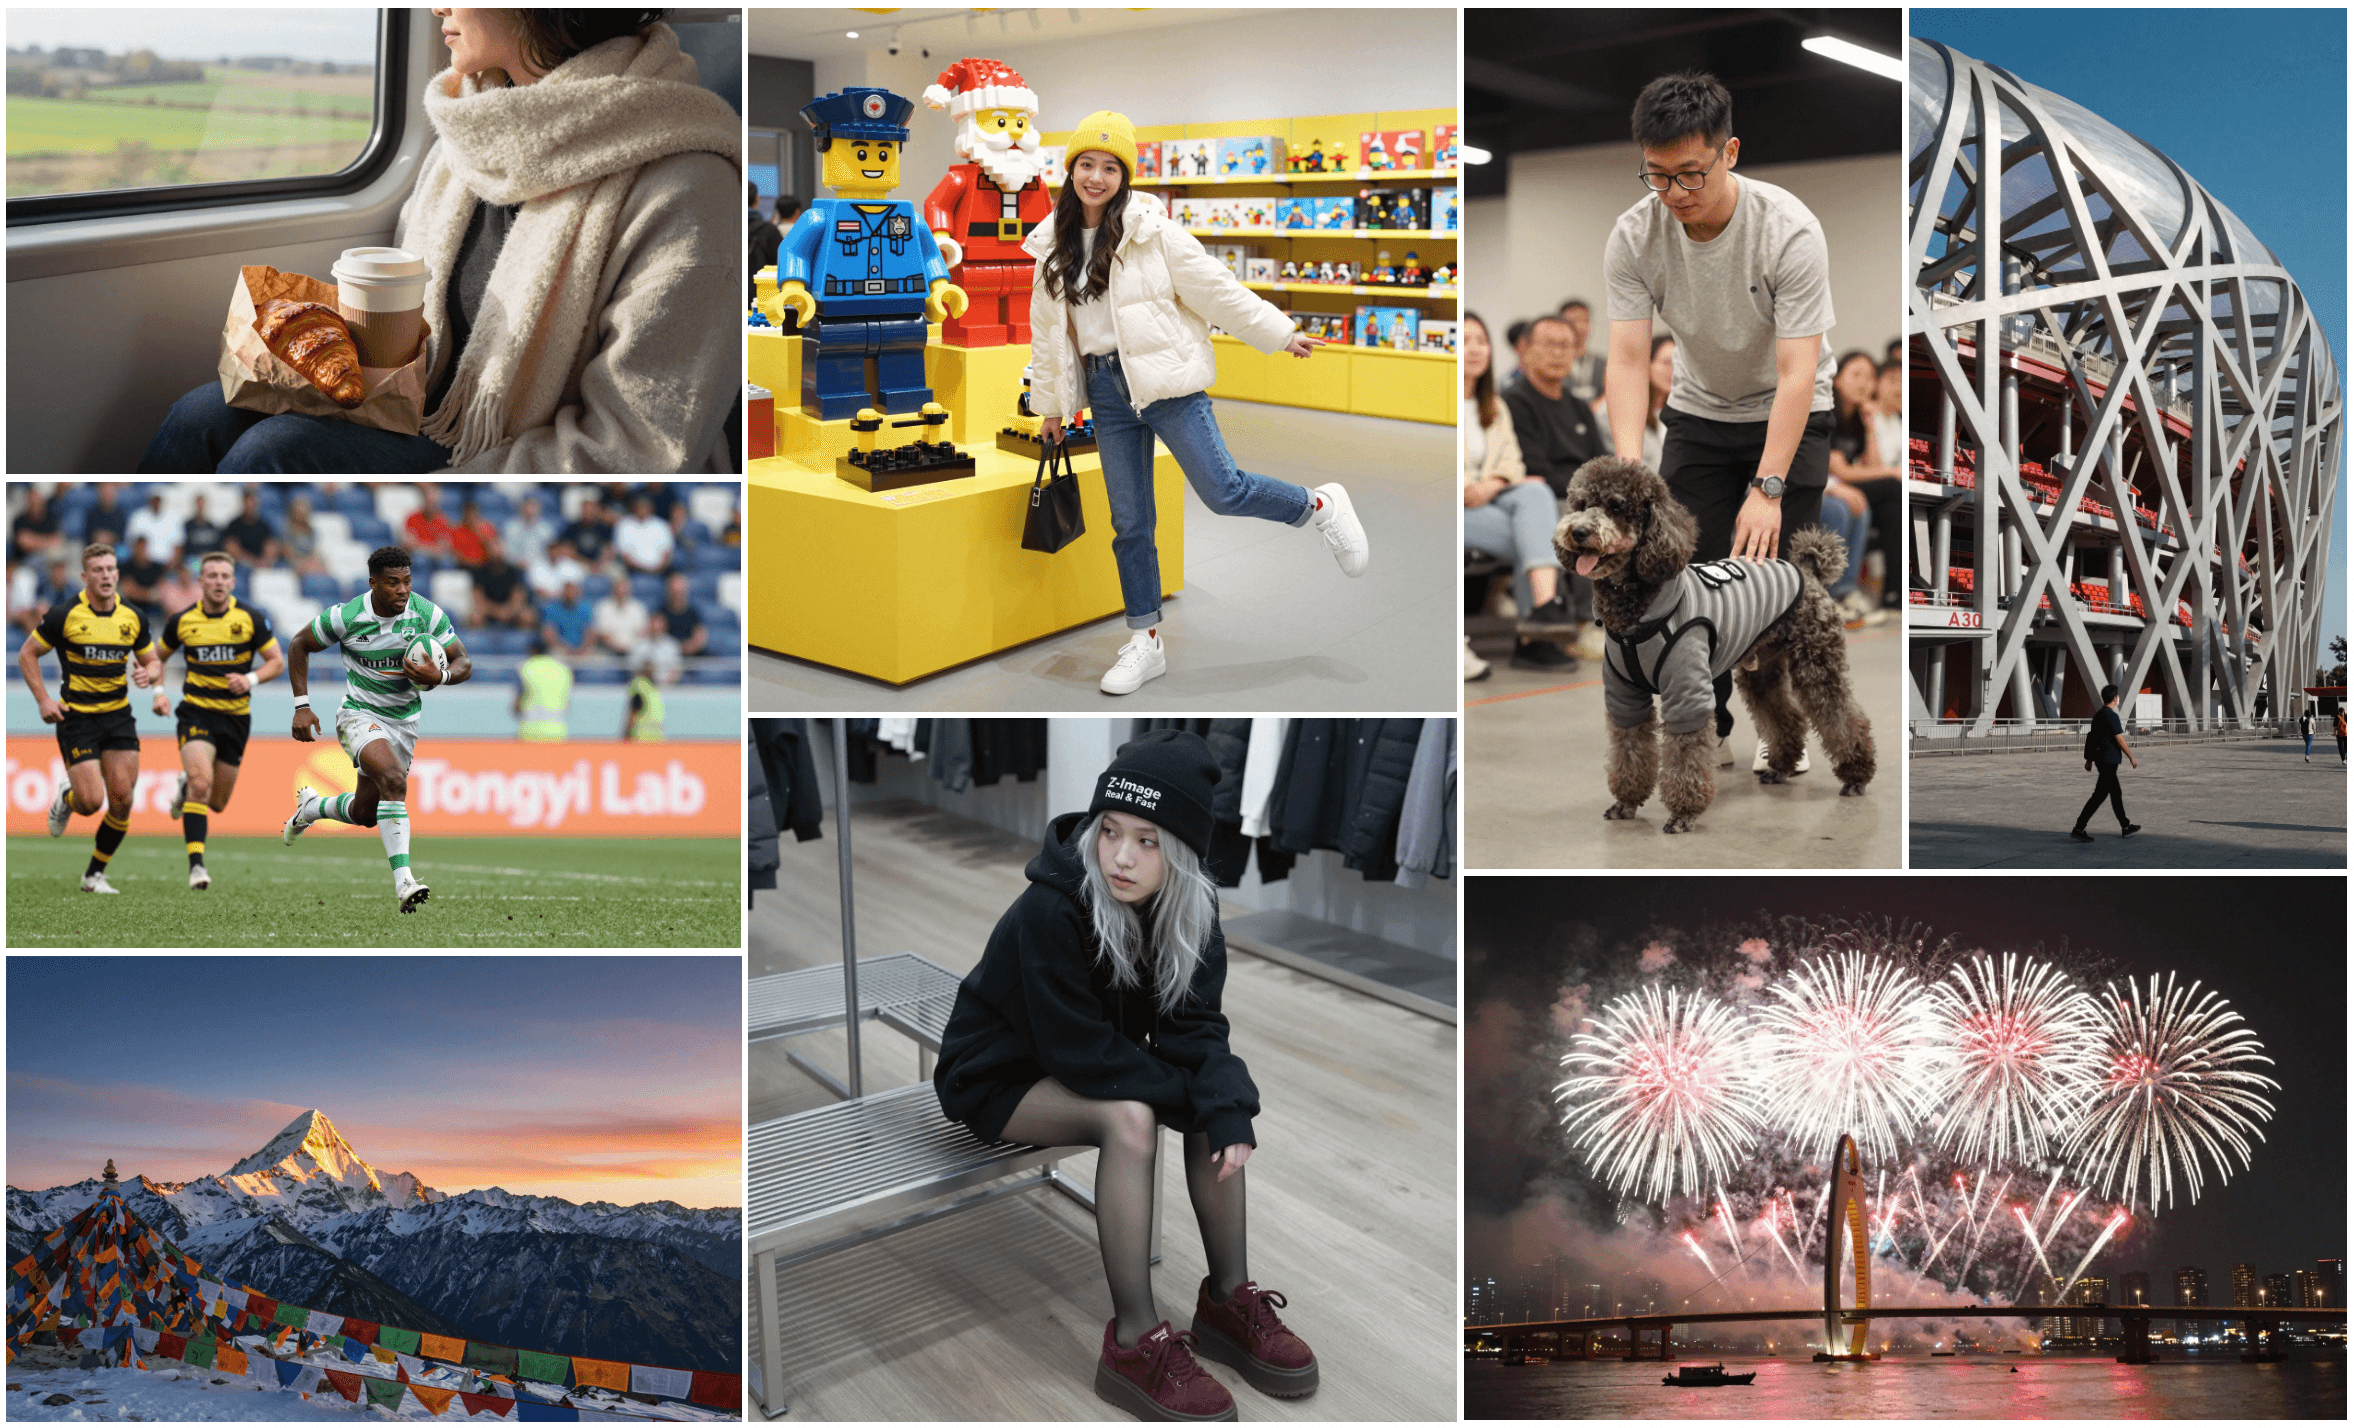
Alibaba's Tongyi-MAI team, the creators of the Qwen model family, has released Z-Image-Turbo, a new open-source text-to-image model designed for speed. The model stands out for its ability to generate a 1024x1024 pixel image in a single inference step, a significant departure from the multi-step sampling process required by most diffusion models.
This efficiency is achieved by using a Diffusion Transformer (DiT) architecture. This approach, which has gained prominence in models like Sora, moves away from the U-Net architectures common in earlier Stable Diffusion versions. By building on a transformer backbone, Z-Image-Turbo can capture complex relationships in text prompts more effectively and streamline the generation process.
The combination of speed and a modern architecture makes Z-Image-Turbo a compelling new option for developers. The model and its weights are available on Hugging Face under the permissive Apache 2.0 license, which allows for commercial use.
For the open-source AI ecosystem, Z-Image-Turbo represents another powerful, commercially-friendly alternative to established models. Its single-step generation offers a practical advantage for applications where low latency is critical, such as real-time previews or interactive image creation tools.
Sources
More from Qwen · Alibaba
All Qwen · Alibaba releases →Qwen-Audio-3.1-ASR Adds Speaker-Aware Transcription
Alibaba's new open audio-language model transcribes and diarizes speech across 30 languages under an Apache 2.0 license.

Qwen-Image-2.1-Turbo targets faster generation
Alibaba's Qwen team ships a distilled, few-step variant of its image model built for speed.

Qwen-Image-2.1 Adds RGBA to Image Generation
Alibaba's Qwen team updates its open image model with transparency support and joint text-to-image and editing capabilities.
More in Text → Image
All Text → Image →
Bria's Fibo 2.0 Brings Structured Prompts to Open Image AI
The new text-to-image and editing model leans on structured prompts and multi-reference inputs for more controllable generation.

Black Forest Labs ships FLUX.3 Image Klein for ComfyUI
The lab's latest open image model arrives packaged for ComfyUI with both generation and editing built in.

Black Forest Labs ships FLUX.3 Image Klein
The latest open image model from the FLUX team handles both text-to-image generation and editing, and arrives ready to run in Diffusers.
0 comments
No comments yet. Be the first to weigh in.