Alibaba's Qwen Team Releases Z-Image Diffusion Model
The makers of the popular Qwen language models have published their first open-source text-to-image generator with a permissive Apache 2.0 license.
Alibaba's Tongyi lab, the research group behind the well-regarded Qwen family of large language models, has released Z-Image, its first open-source text-to-image model. This release marks the team's expansion from open-source text generation into the competitive field of image synthesis.
The new model is a diffusion-based generator, a common architecture for creating high-fidelity images from text prompts. While the team has not disclosed specific architectural details or training data, the model is positioned as a new, capable foundation for developers and artists working with open-source tools.
Perhaps most significantly, Z-Image is available under the permissive Apache 2.0 license. This allows for broad use, including commercial applications, which could foster a new ecosystem of tools and services built on the model. It represents another major technology player contributing a commercially viable model to the open-source community, following a trend that has accelerated innovation in the space.
The model weights and usage instructions are now available on the Hugging Face Hub. As a new entrant from a team known for high-quality LLMs, Z-Image is a notable addition for anyone tracking the rapidly evolving landscape of generative AI.
Sources
- Visit
Tongyi-MAI/Z-Image
Hugging Face
More from Qwen · Alibaba
All Qwen · Alibaba releases →Qwen-Audio-3.1-ASR Adds Speaker-Aware Transcription
Alibaba's new open audio-language model transcribes and diarizes speech across 30 languages under an Apache 2.0 license.
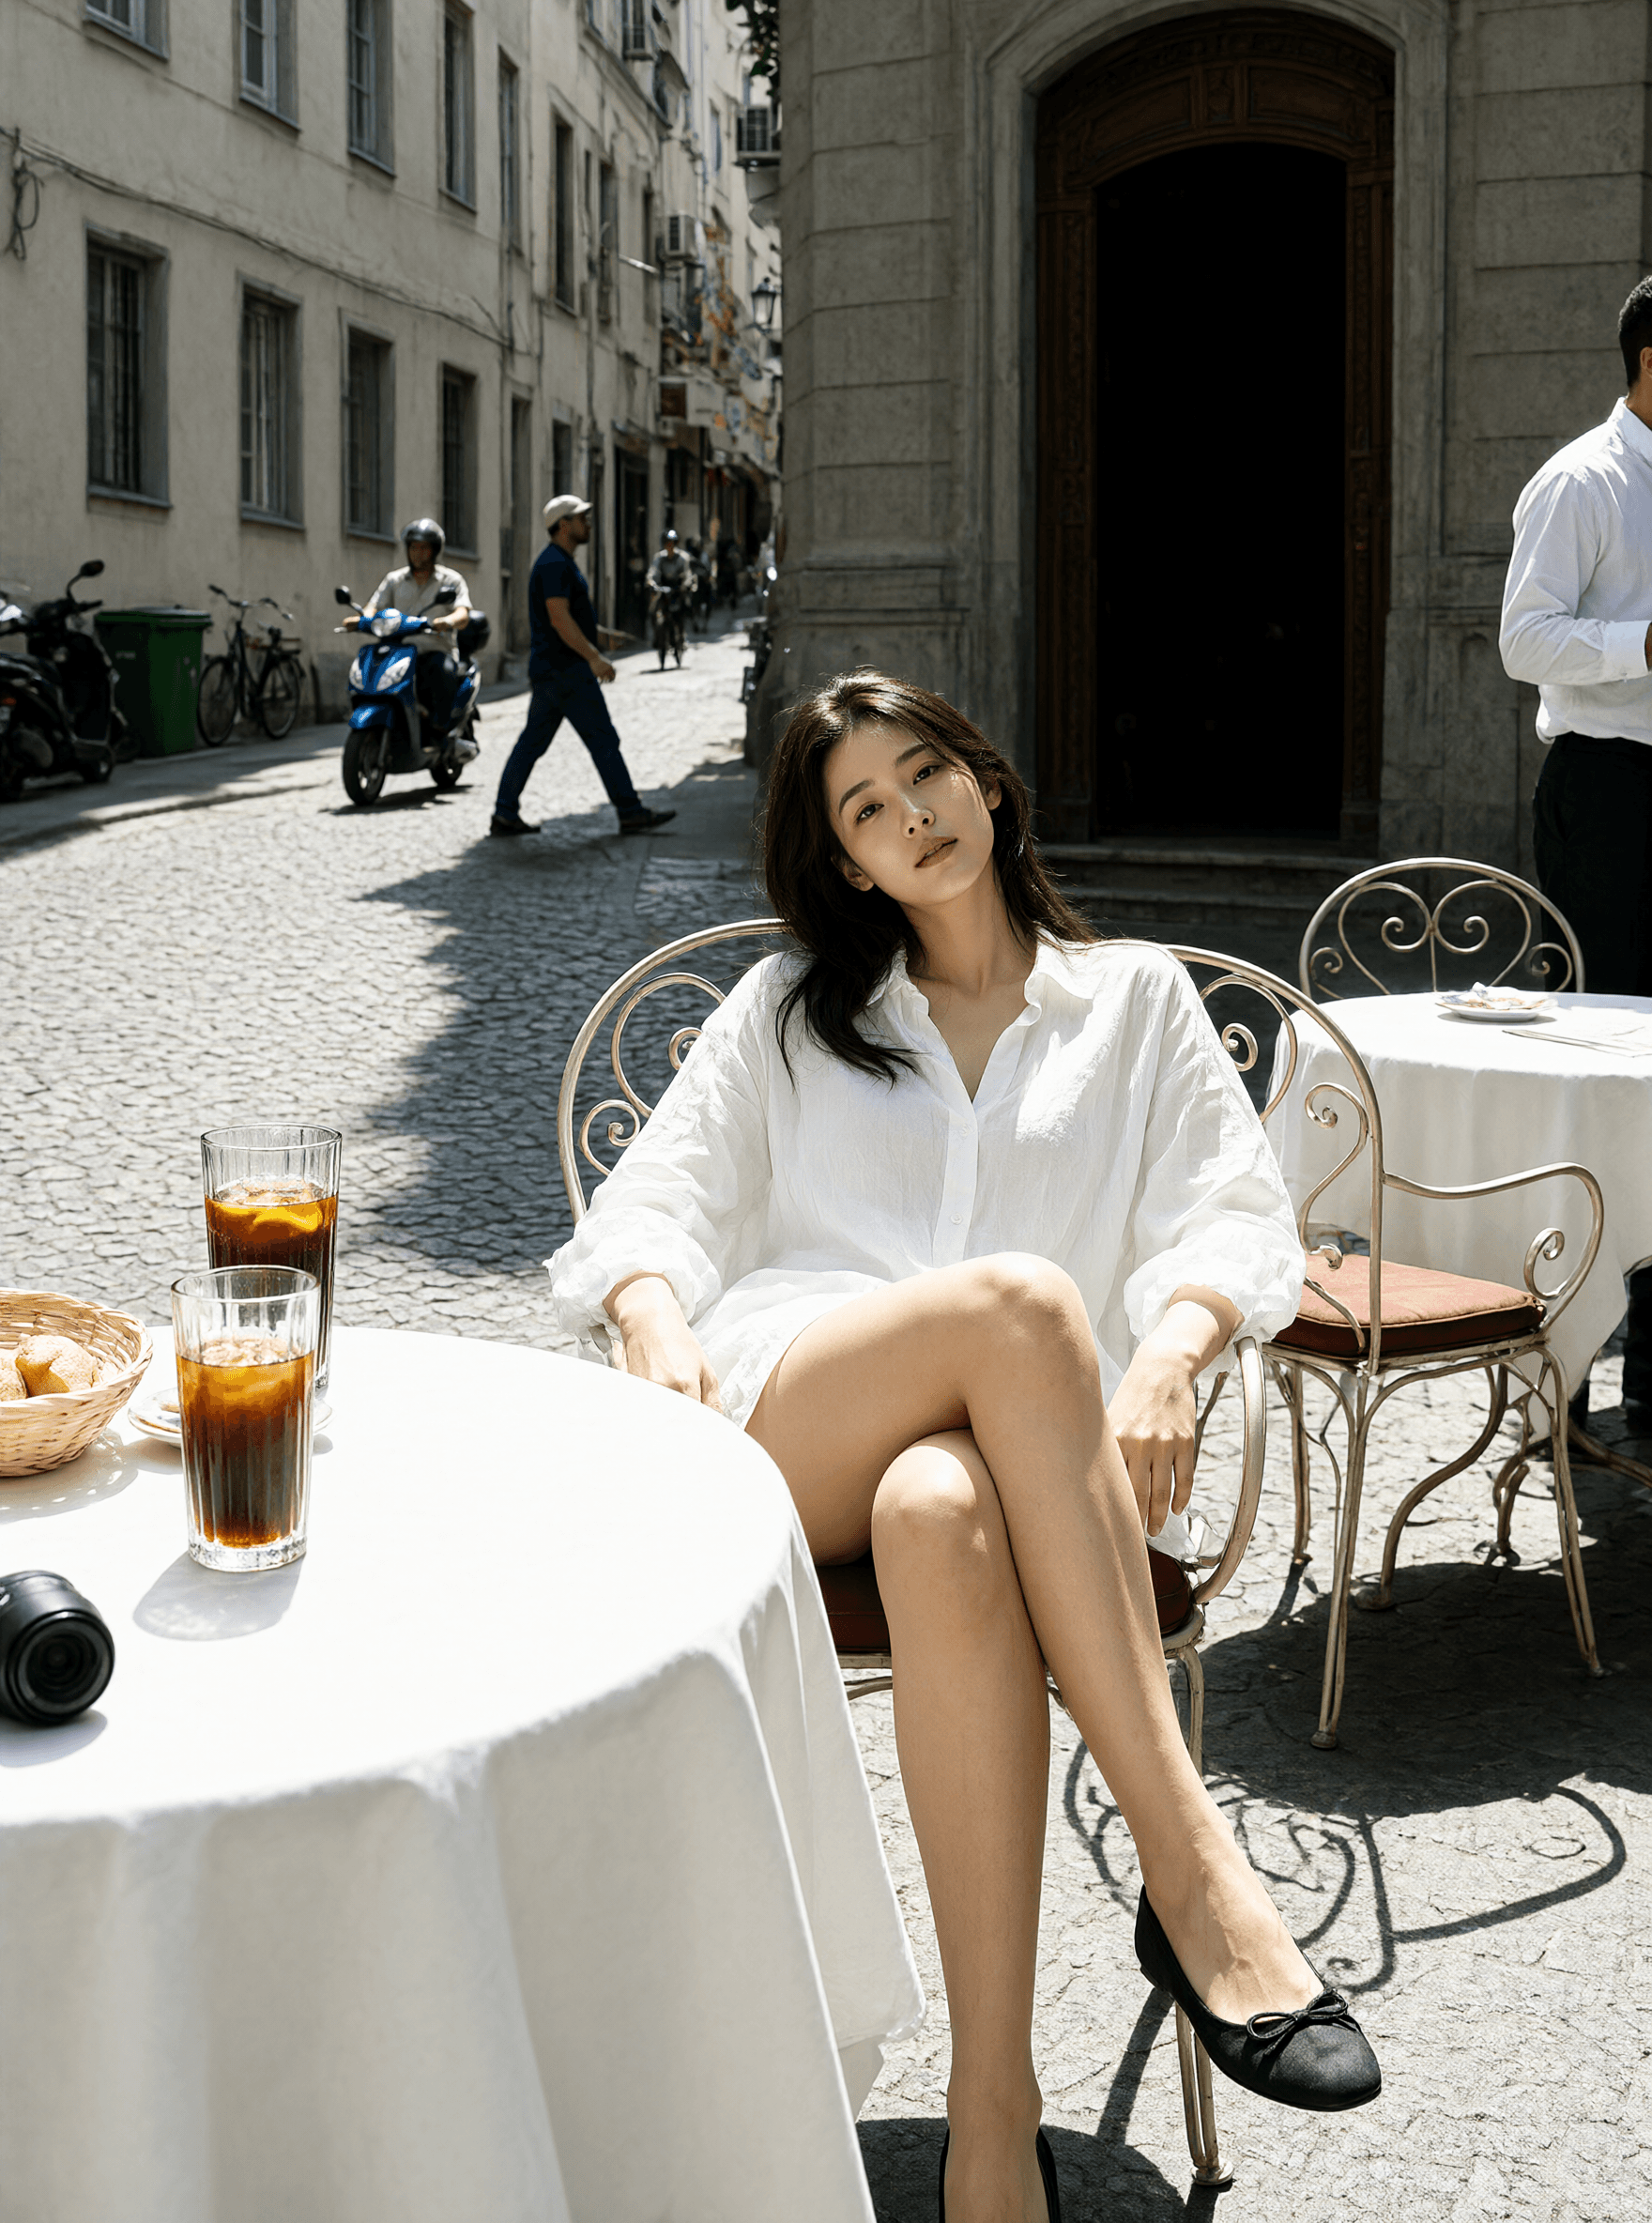
Qwen-Image-2.1-Turbo targets faster generation
Alibaba's Qwen team ships a distilled, few-step variant of its image model built for speed.
Qwen-Image-2.1 Adds RGBA to Image Generation
Alibaba's Qwen team updates its open image model with transparency support and joint text-to-image and editing capabilities.
More in Text → Image
All Text → Image →
Bria's Fibo 2.0 Brings Structured Prompts to Open Image AI
The new text-to-image and editing model leans on structured prompts and multi-reference inputs for more controllable generation.

Black Forest Labs ships FLUX.3 Image Klein for ComfyUI
The lab's latest open image model arrives packaged for ComfyUI with both generation and editing built in.

Black Forest Labs ships FLUX.3 Image Klein
The latest open image model from the FLUX team handles both text-to-image generation and editing, and arrives ready to run in Diffusers.
0 comments
No comments yet. Be the first to weigh in.