EPFL Releases SVI for Streaming Image-to-Video
The new open-source model from Swiss researchers uses a novel chunking method to generate indefinitely long videos from a single still image.
Researchers at Switzerland's EPFL Visual Intelligence for Transportation (VITA) lab have released an open-source image-to-video model called SVI, which stands for Streaming Video from Images. The model tackles one of the key limitations in current AI video generation: creating clips that last more than a few seconds while maintaining temporal consistency.
While many models generate short, fixed-length videos, SVI is designed to produce videos of arbitrary length from a single starting image. It accomplishes this through an autoregressive process that generates the video in overlapping chunks. This "streaming" technique allows the model to extend the animation frame by frame, ensuring smoother and more coherent transitions over longer durations.
SVI is built upon a strong foundation, having been fine-tuned from Stability AI's popular Stable Video Diffusion (SVD) model. The team trained their version on the large-scale WebVid-10M dataset to develop its long-form generation capabilities.
The model and its code are available on the Hugging Face Hub under a permissive MIT license. While still a research artifact, SVI's novel approach offers a promising direction for developers and academics working to overcome the short-form constraints of today's open-source video generation tools.
Sources
- Visit
epfl-vita/svi-model
Hugging Face
More in Image → Video
All Image → Video →
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
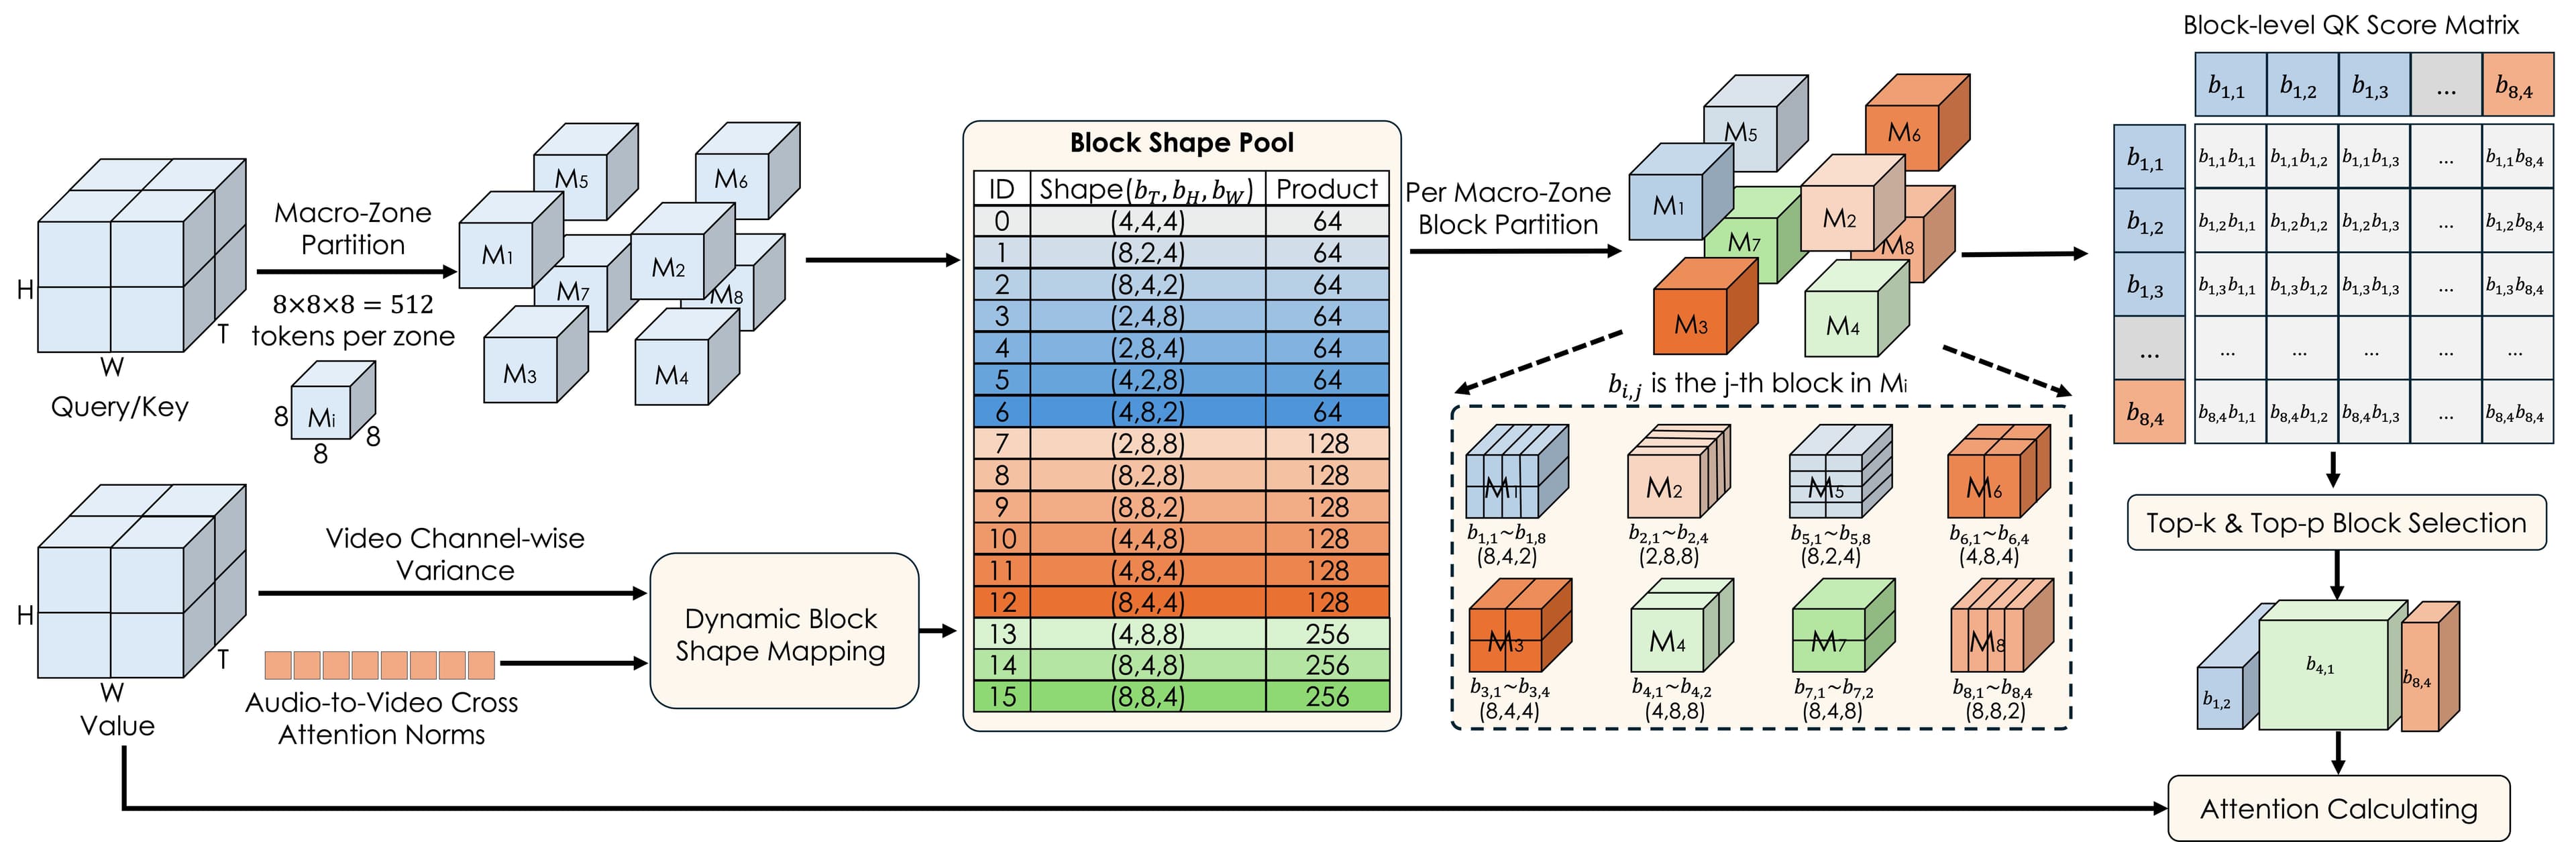
Prism Brings Joint Video-Audio Generation to Diffusion
A new MIT-licensed video diffusion transformer pairs high-resolution image-to-video output with synchronized audio and sparse attention.
Viggle Releases Viggle-Animate for Character Swaps
The open image-to-video model targets character replacement and video editing, distilled from MiniMax-H3.
0 comments
No comments yet. Be the first to weigh in.