Zhipu AI Releases Multilingual GLM-OCR Vision Model
The new vision-language model from the creators of the GLM series is specialized for recognizing and extracting text from images across multiple languages.
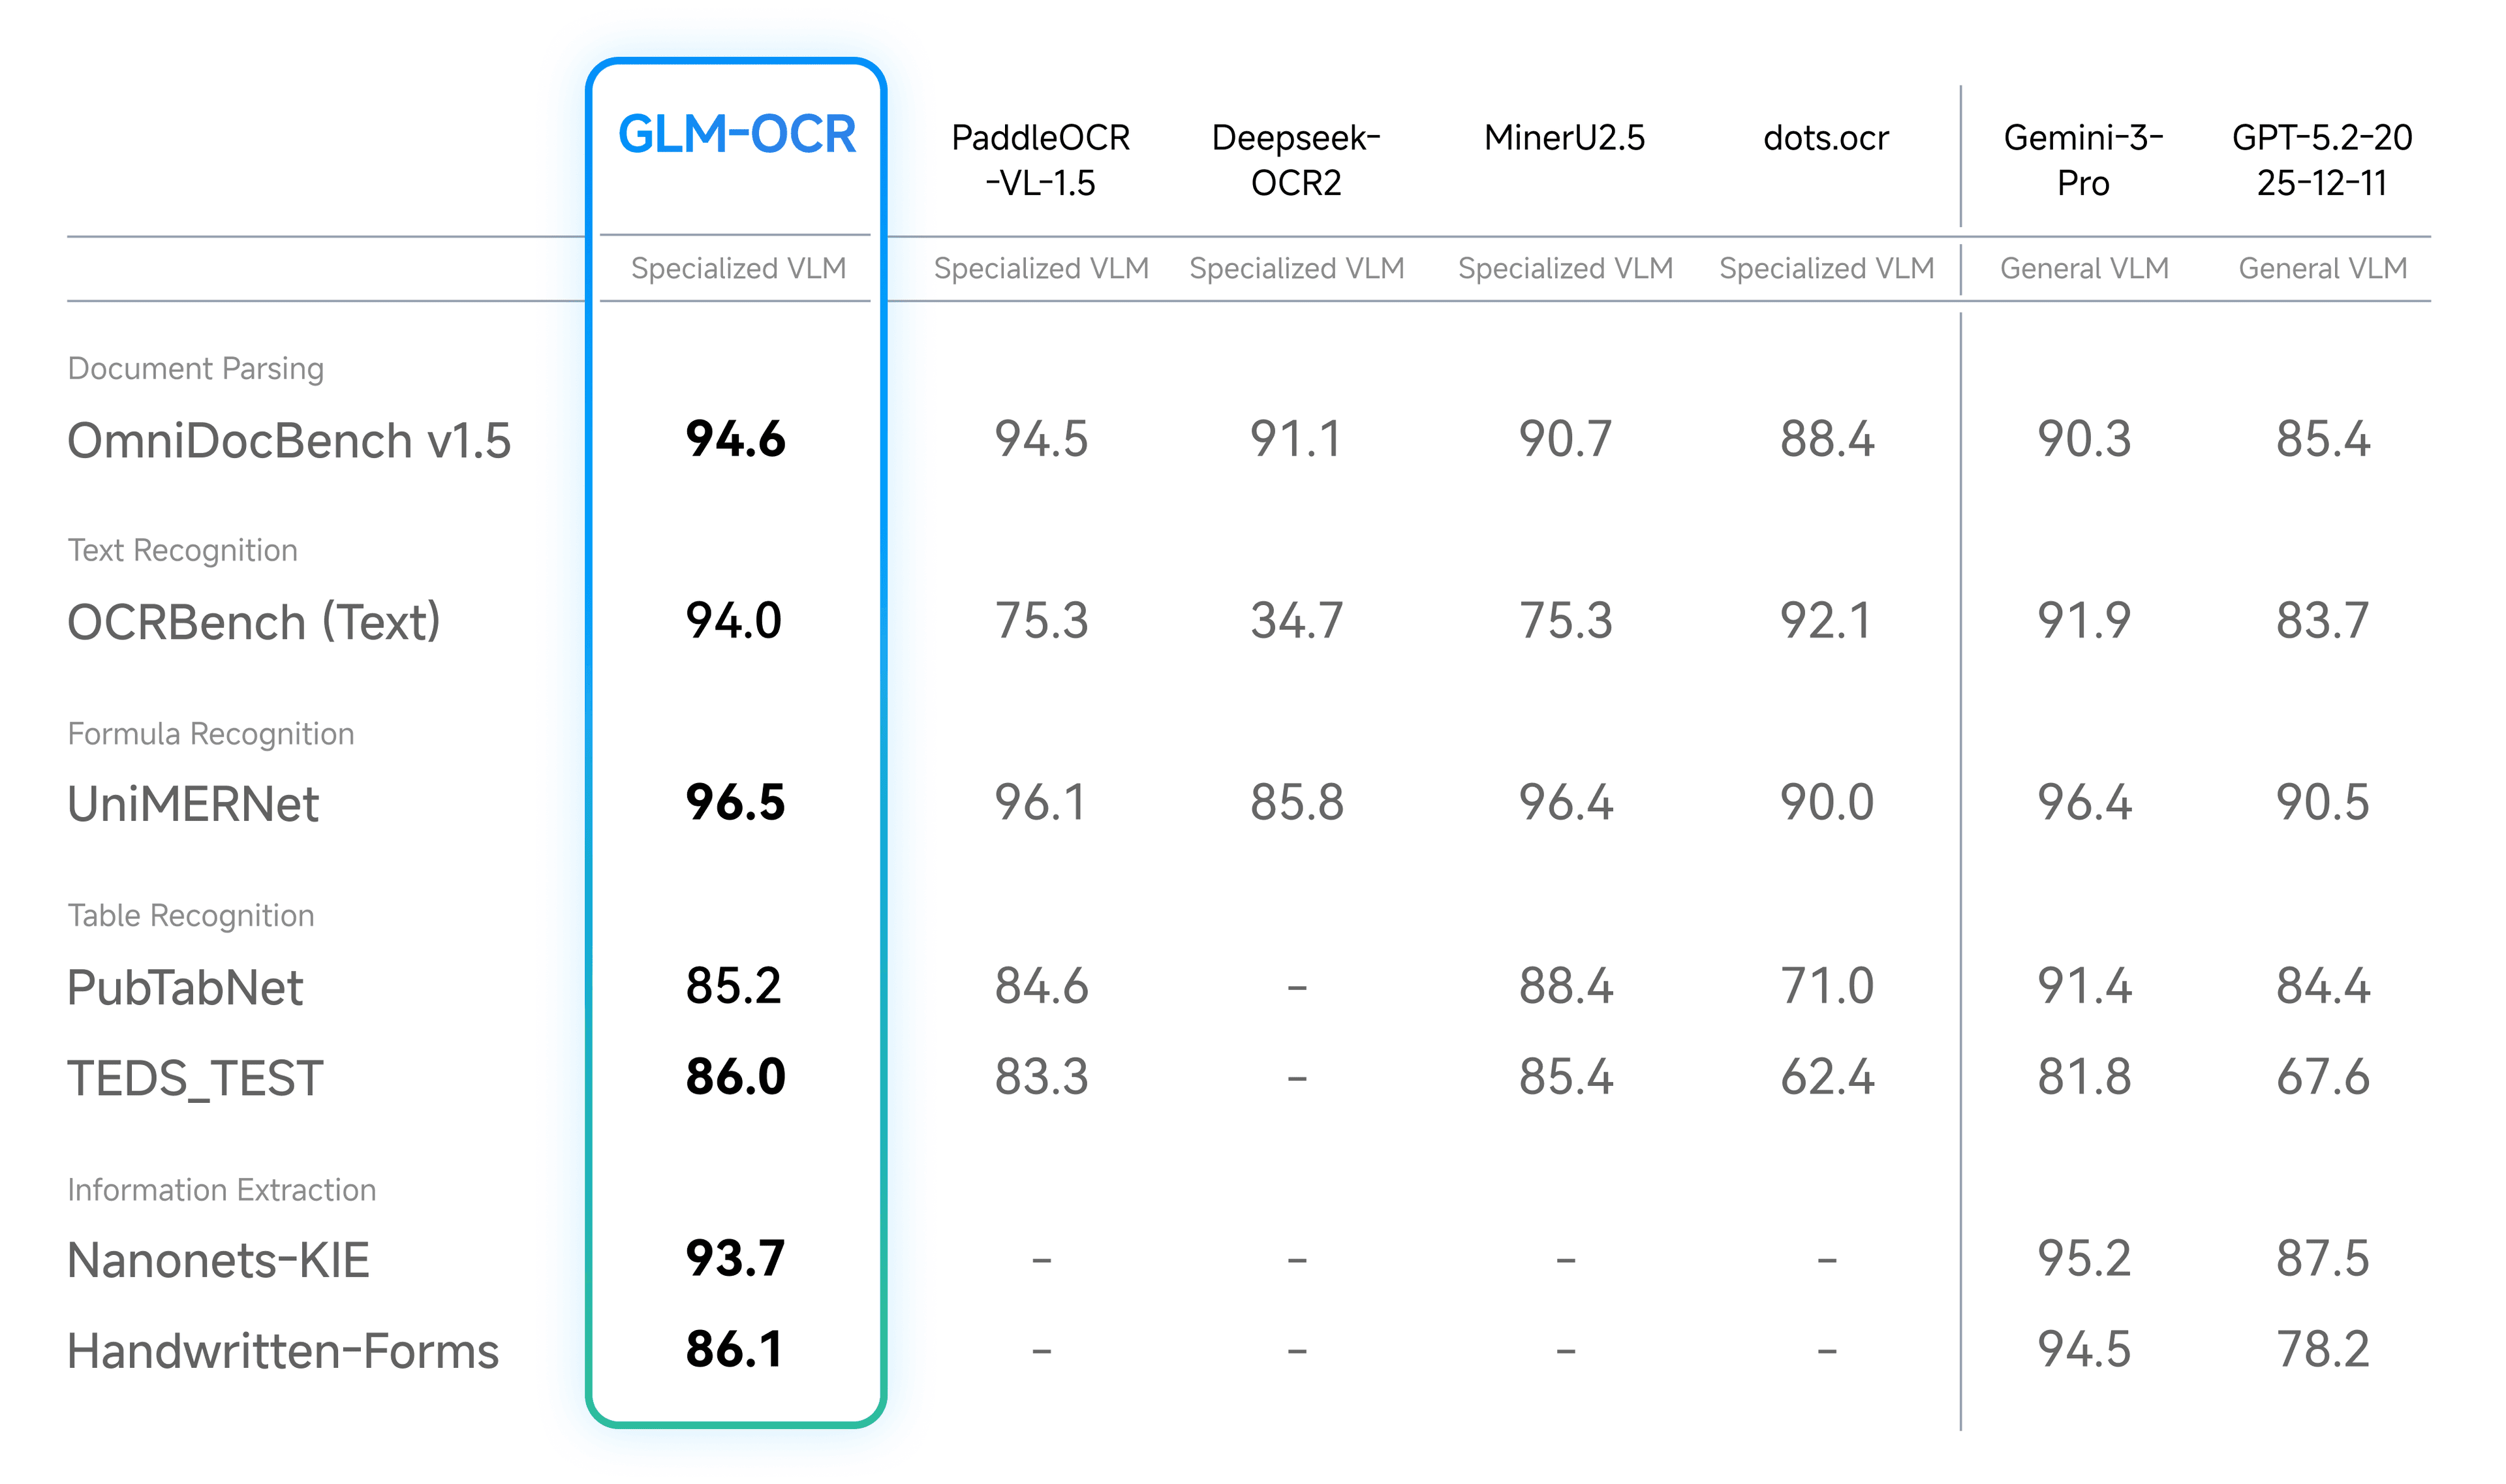
Zhipu AI, the company behind the prominent GLM series of large language models, has released a new open-source model focused on a classic computer vision task: optical character recognition (OCR). The new model, called GLM-OCR, is a vision-language model (VLM) designed specifically to identify and extract text embedded in images.
The key feature of GLM-OCR is its multilingual capability. According to the project's official release page, the model is trained to handle text in Chinese, English, Korean, and Japanese, making it a potentially valuable tool for applications that need to process documents and images from across East Asia and the English-speaking world. You can find the model and usage instructions on its Hugging Face repository.
Why it matters
High-quality OCR is a foundational technology for digitizing documents, parsing user interfaces, and powering accessibility tools. While powerful OCR services are available through proprietary APIs, strong open-source alternatives empower developers to build applications with more privacy and control. GLM-OCR provides a new, specialized tool for this purpose, particularly for developers working with multilingual content.
While Zhipu AI has released the model weights, potential users should note the license. The model is available under a custom license that places limitations on its use for online services, a key distinction from more permissive licenses like Apache 2.0. This restricts its use in certain commercial applications, so developers should review the terms carefully before integrating it into their projects.
Sources
- Visit
zai-org/GLM-OCR
Hugging Face
More from Zhipu AI
All Zhipu AI releases →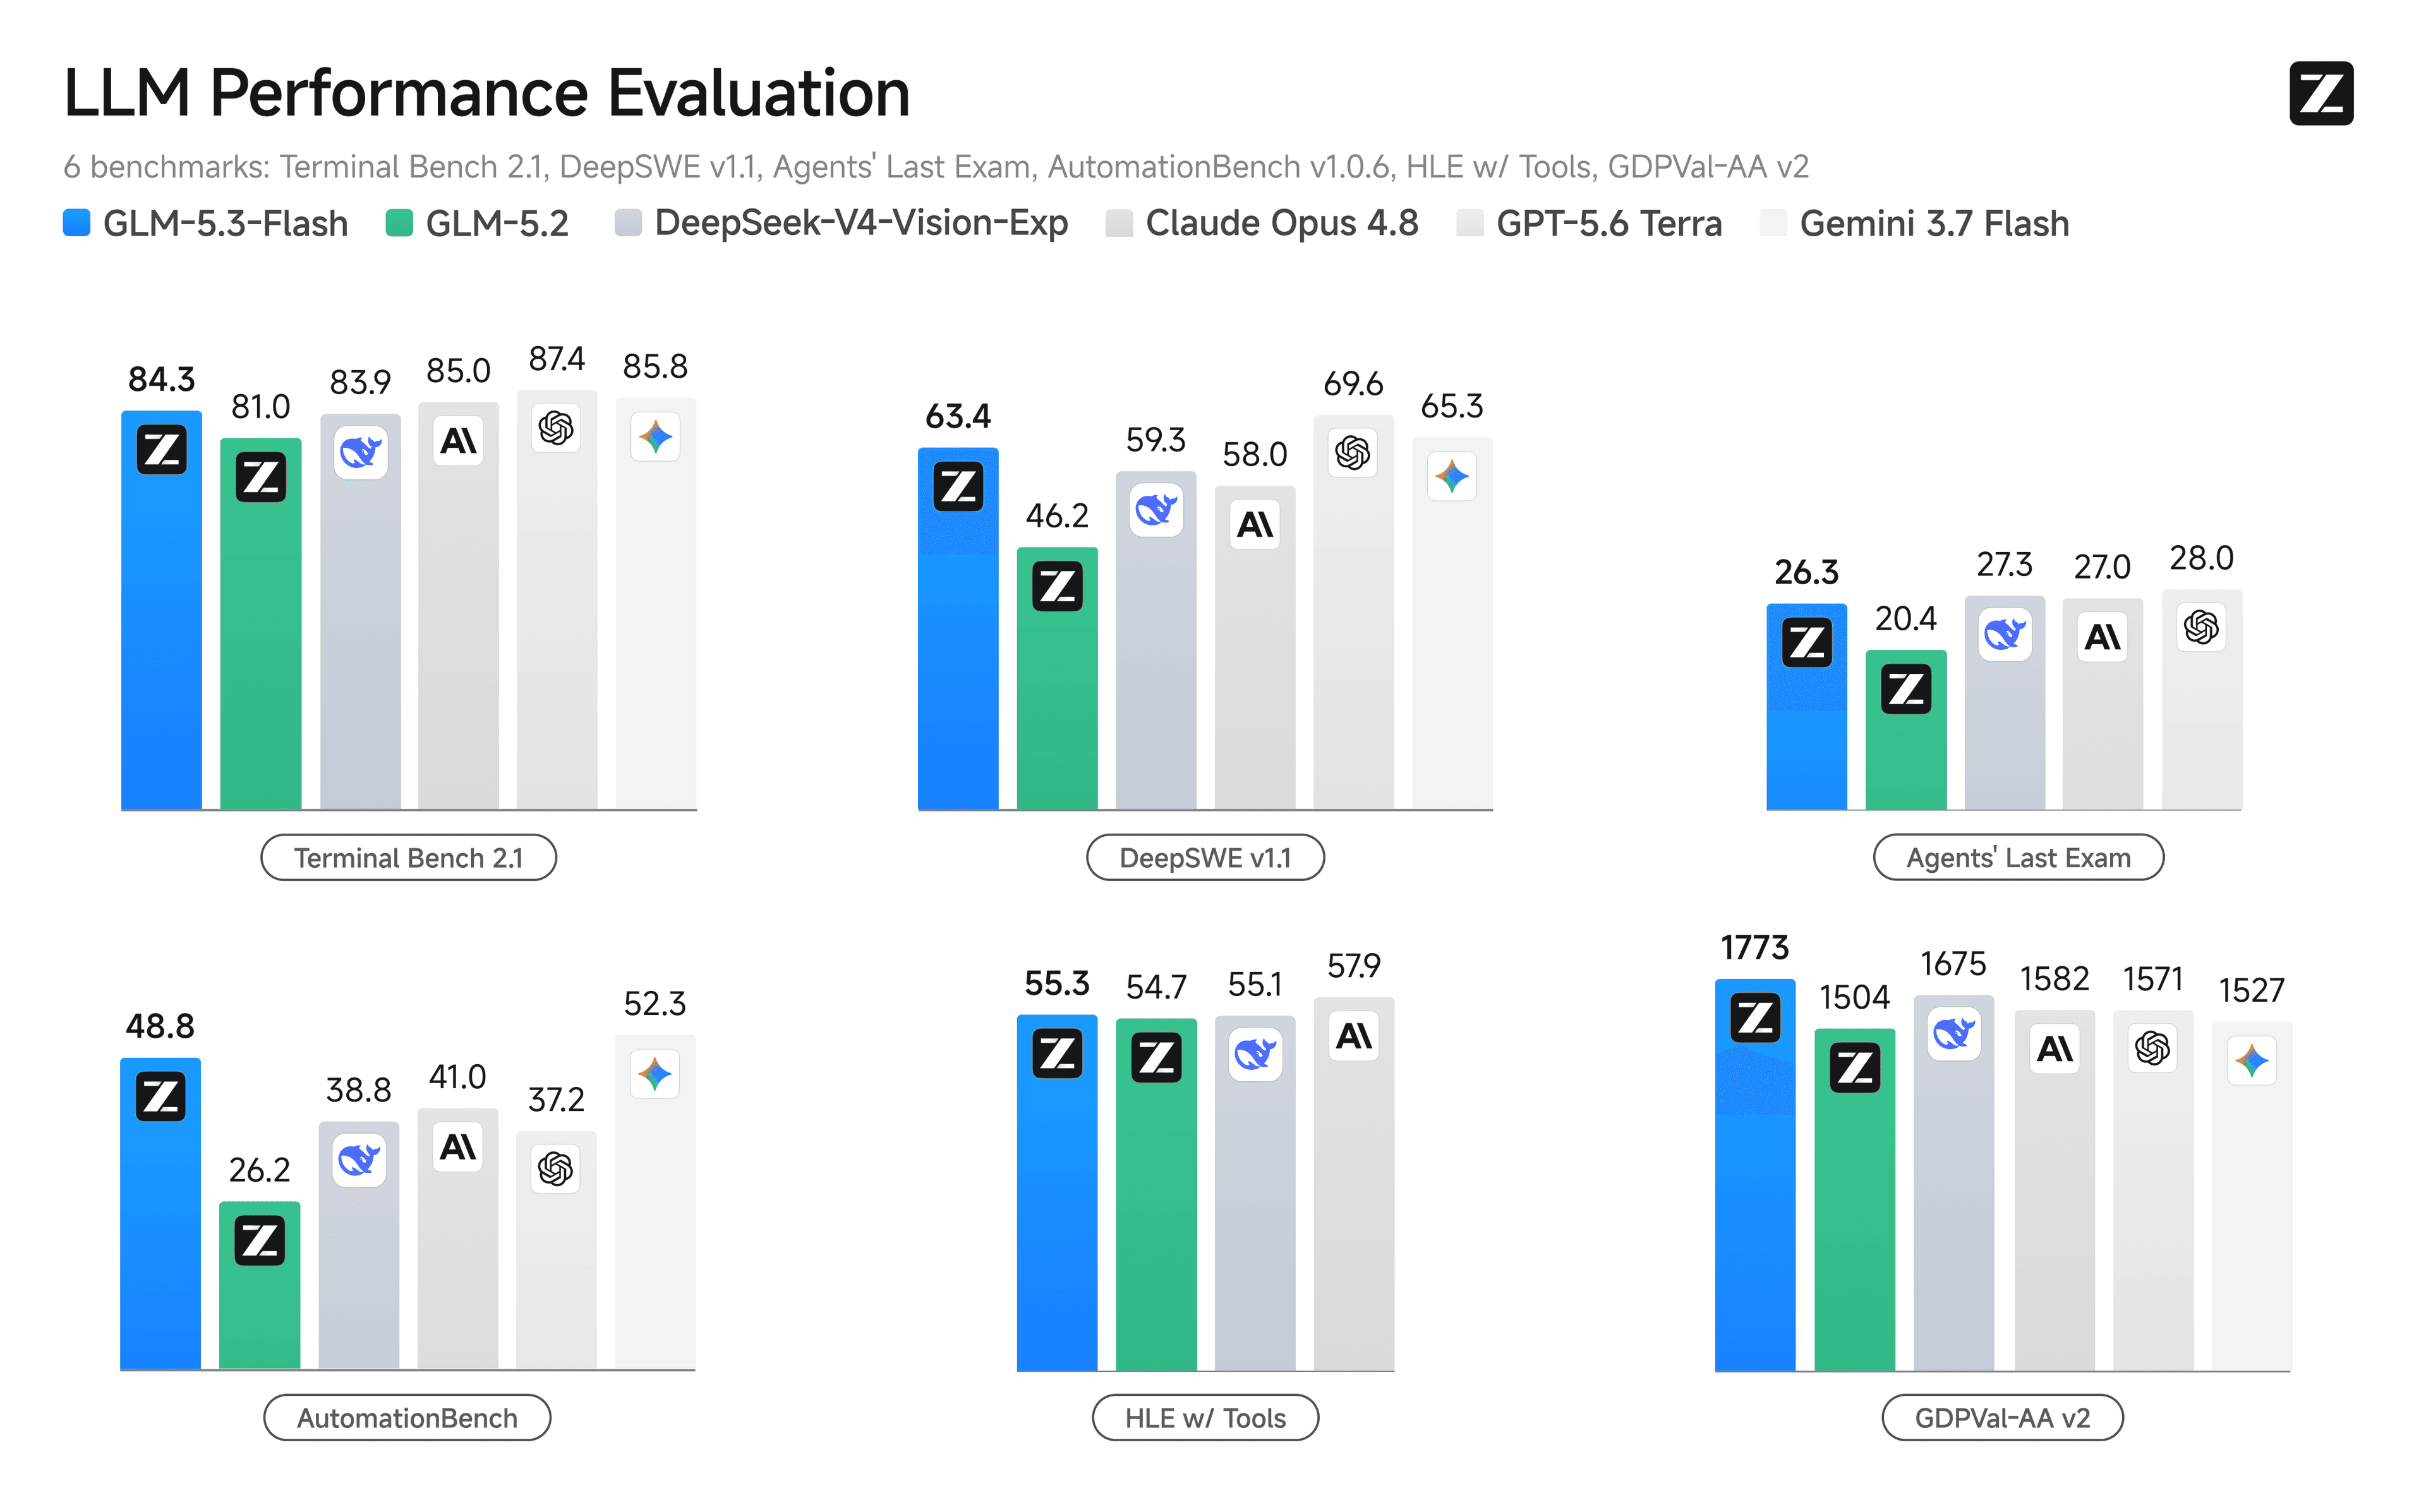
Zhipu releases GLM-5.3-Flash under MIT license
A speed-tuned member of the GLM-5.3 family arrives with open weights and mixture-of-experts design aimed at fast, low-cost inference.
Zhipu's GLM-5.3 Targets Coding at a Fraction of the Cost
The open-weight MoE model from Zhipu AI aims to match frontier closed systems on coding tasks while undercutting them on price.
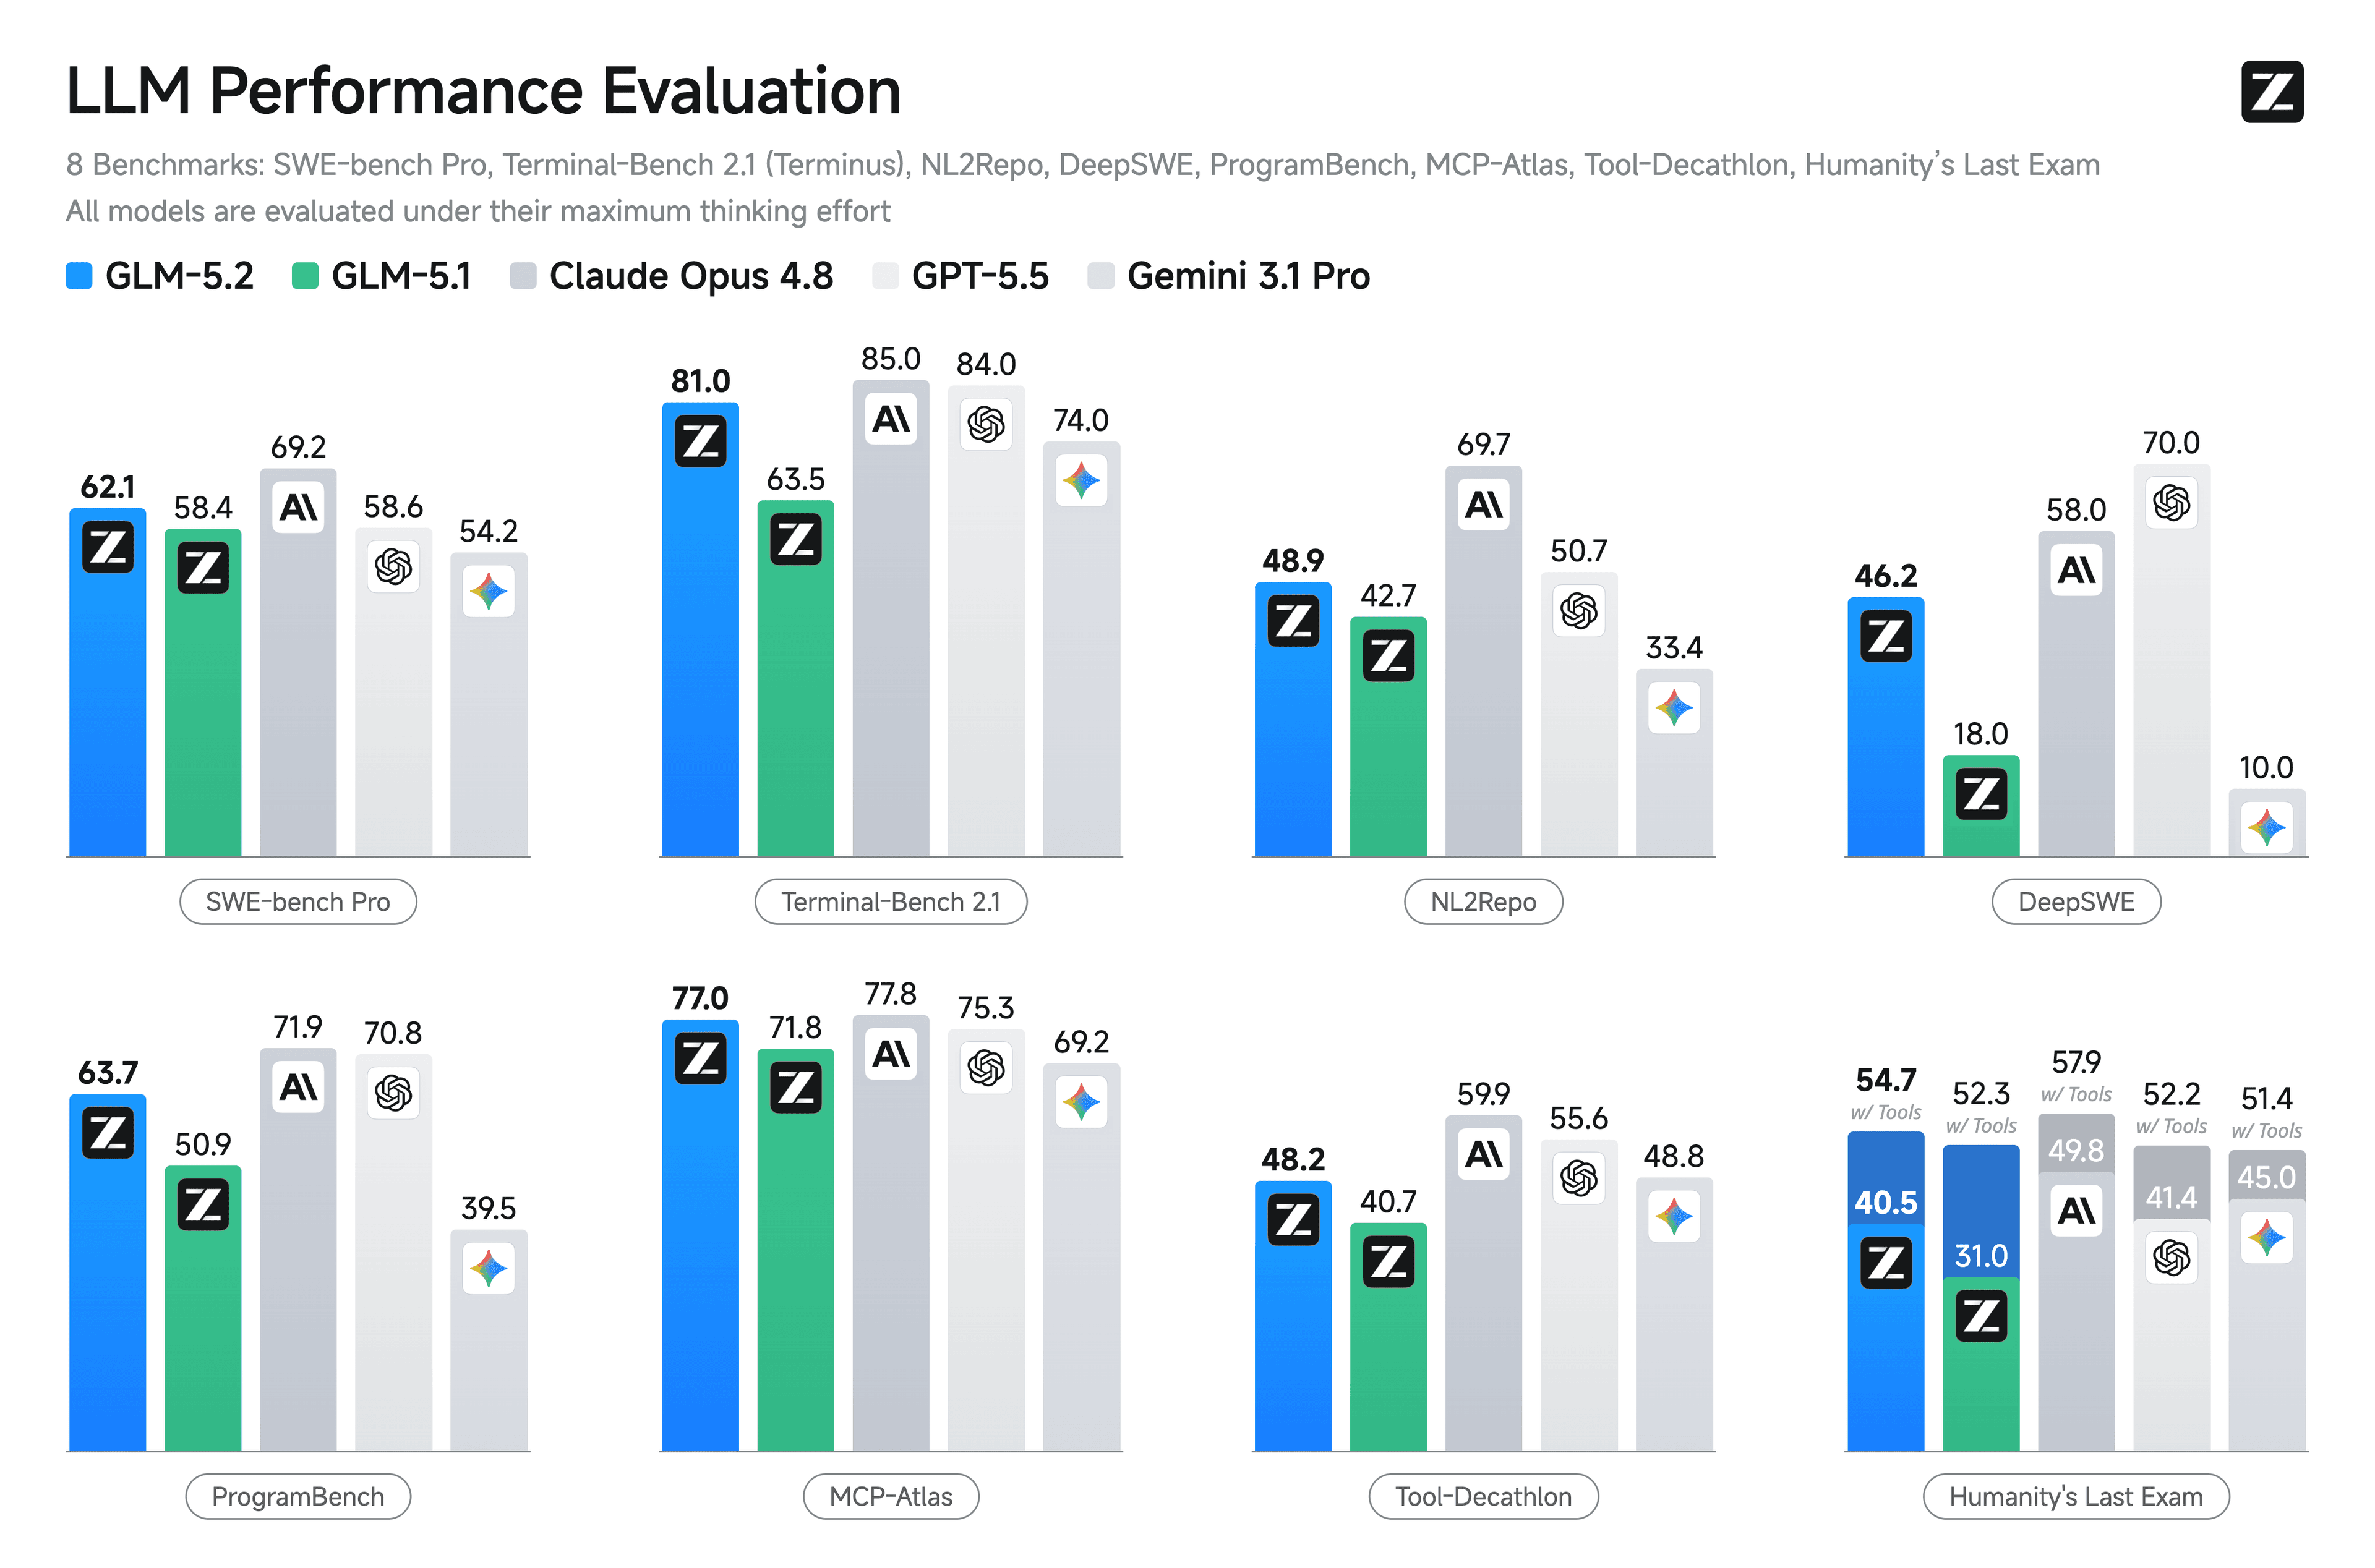
Zhipu AI Releases MIT-Licensed GLM-5.2 MoE Model
The new bilingual model from the Chinese AI firm uses a Mixture of Experts architecture and sparse attention under a fully permissive license.
More in Vision-Language
All Vision-Language →
Microsoft's Mage-VL-Cowork takes on computer-use tasks
A new vision-language agent model aims to operate GUIs, write code, and work the terminal.

Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Baidu releases Unlimited-OCR 2 under MIT license
The multilingual vision-language model targets document text recognition and ships with a permissive license for commercial use.
0 comments
No comments yet. Be the first to weigh in.