Tencent's AuK Bundles Voice Cloning and Speech Editing
The new open-weights model handles zero-shot TTS alongside enhancement and separation, aiming to be a broad speech toolkit rather than a single-purpose voice engine.

Tencent has released AuK, a zero-shot text-to-speech system that arrives with an unusually broad remit. Rather than focusing on a single task, the model spans voice cloning, speech editing, audio enhancement and source separation, according to its Hugging Face repository.
Zero-shot cloning is the headline capability: it lets the model reproduce a target voice from a short reference sample without task-specific fine-tuning. Paired with speech editing—modifying existing recordings rather than synthesizing from scratch—AuK positions itself closer to a production audio toolkit than a standalone TTS demo.
Why it matters
Most open speech models specialize, forcing developers to stitch together separate systems for synthesis, cleanup and separation. Consolidating those functions in one release could simplify pipelines for anyone building voice interfaces, dubbing tools or podcast production workflows.
A few practical caveats remain:
- AuK ships under an "other" license, so teams should read the terms before commercial use.
- Parameter count, supported languages and sample rate are not specified in the release record.
- Voice cloning capabilities raise the usual concerns about consent and misuse.
As with any open cloning model, the value will depend on audio quality and how permissive the license turns out to be. The weights and documentation are available now on Hugging Face.
Sources
- Visit
tencent/AuK
Hugging Face
More from Tencent
All Tencent releases →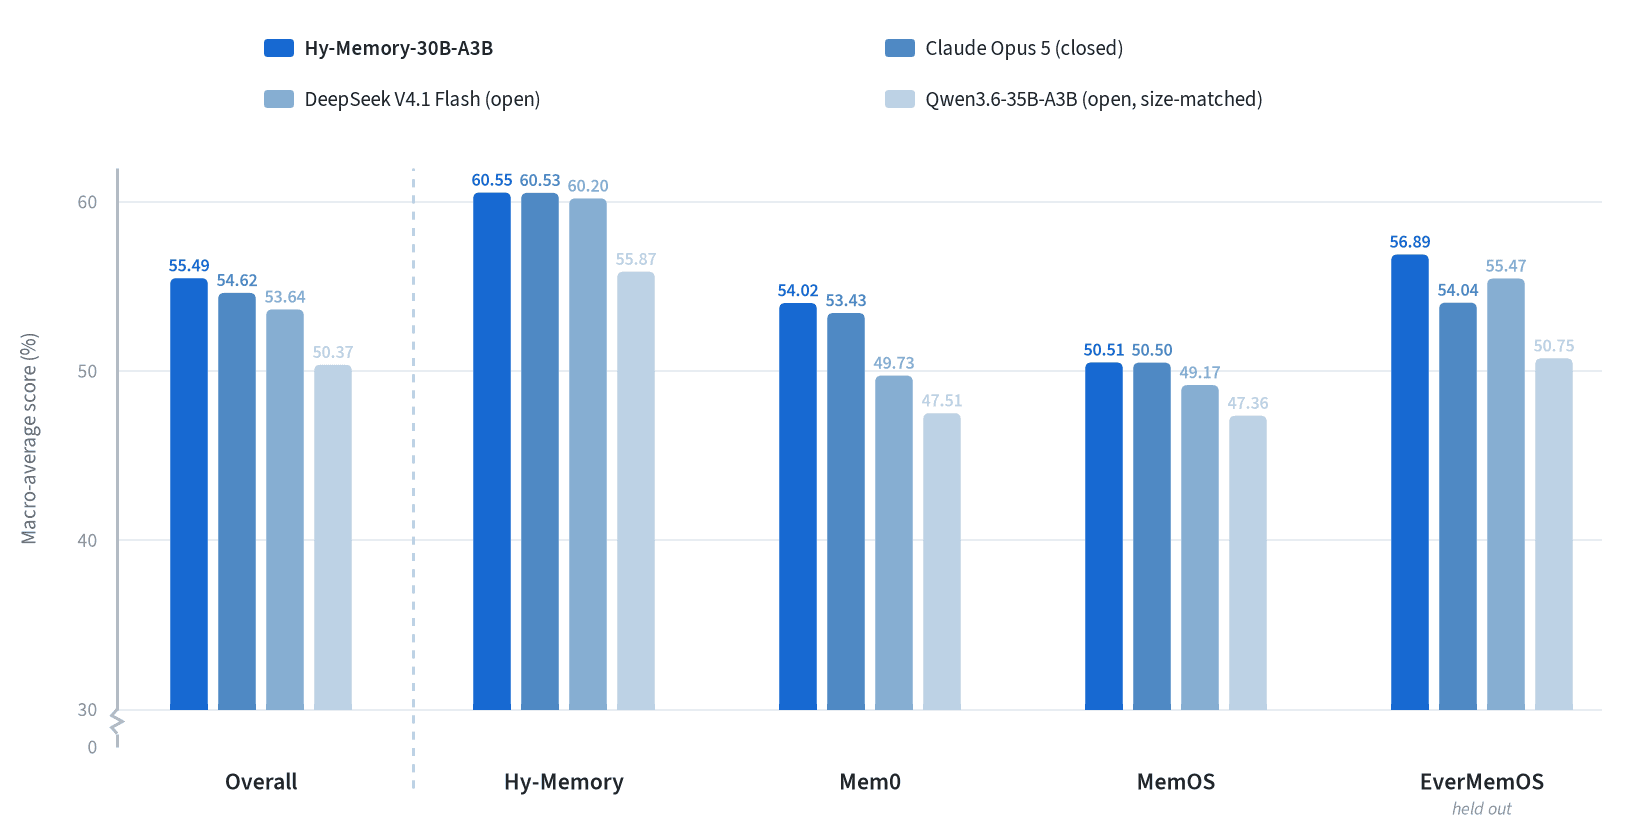
Tencent releases Hy-Memory 30B-A3B under Apache 2.0
A memory-focused mixture-of-experts model activates just 3B of its 30B parameters per token, and ships with a permissive license.
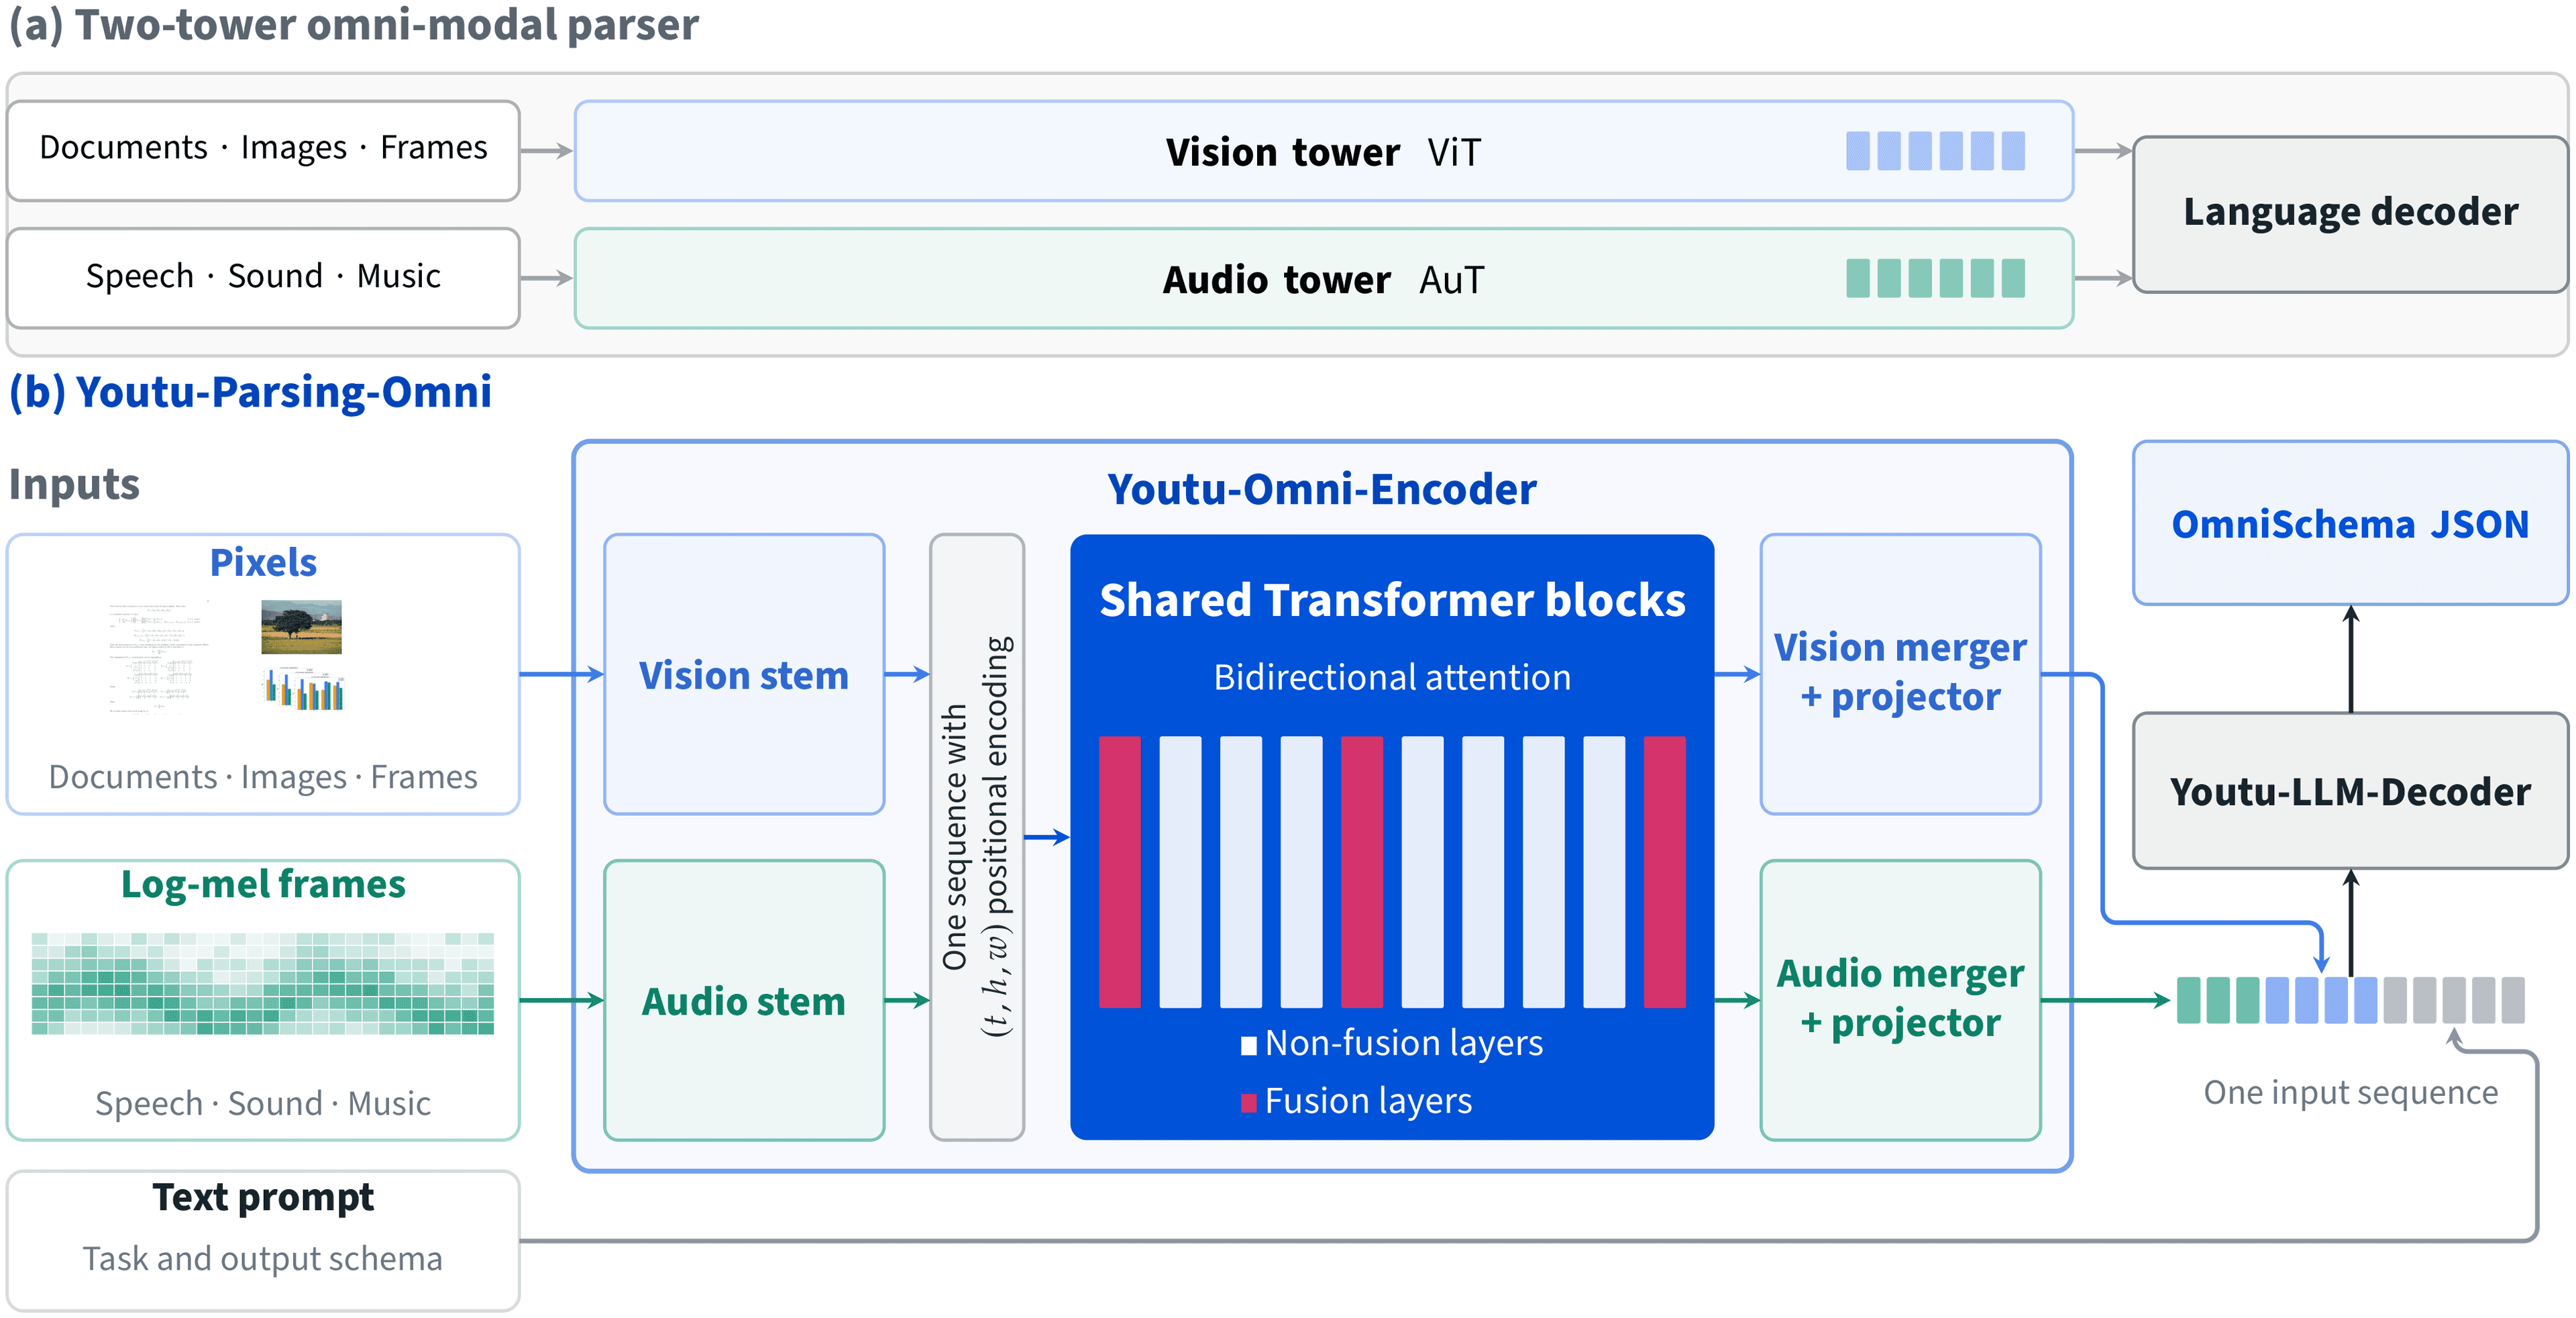
Tencent's Youtu-Parsing-Omni tackles docs, audio, video
A new open-weights parsing model from Tencent extends OCR beyond the page into audio and video inputs.
Tencent's T1 Targets Long-Horizon Terminal Work
A 122B mixture-of-experts model trained with reinforcement learning claims state-of-the-art results on Terminal-Bench.
More in Text → Speech
All Text → Speech →IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.

Fish Audio's Drama 3 brings MoE to open TTS
The open-source speech model pairs a 35B mixture-of-experts backbone with voice cloning and directed performance control.
Nari Labs Ships Qwen3-Based TTS and ASR Models
The startup pairs speech synthesis and recognition built on Qwen3, pitching accuracy, low latency, and lower cost.
0 comments
No comments yet. Be the first to weigh in.