Zhipu AI Releases Open, Bilingual GLM-Image Model
The new text-to-image model is fluent in both Chinese and English, built on the CogView2 architecture and released under a permissive MIT license.
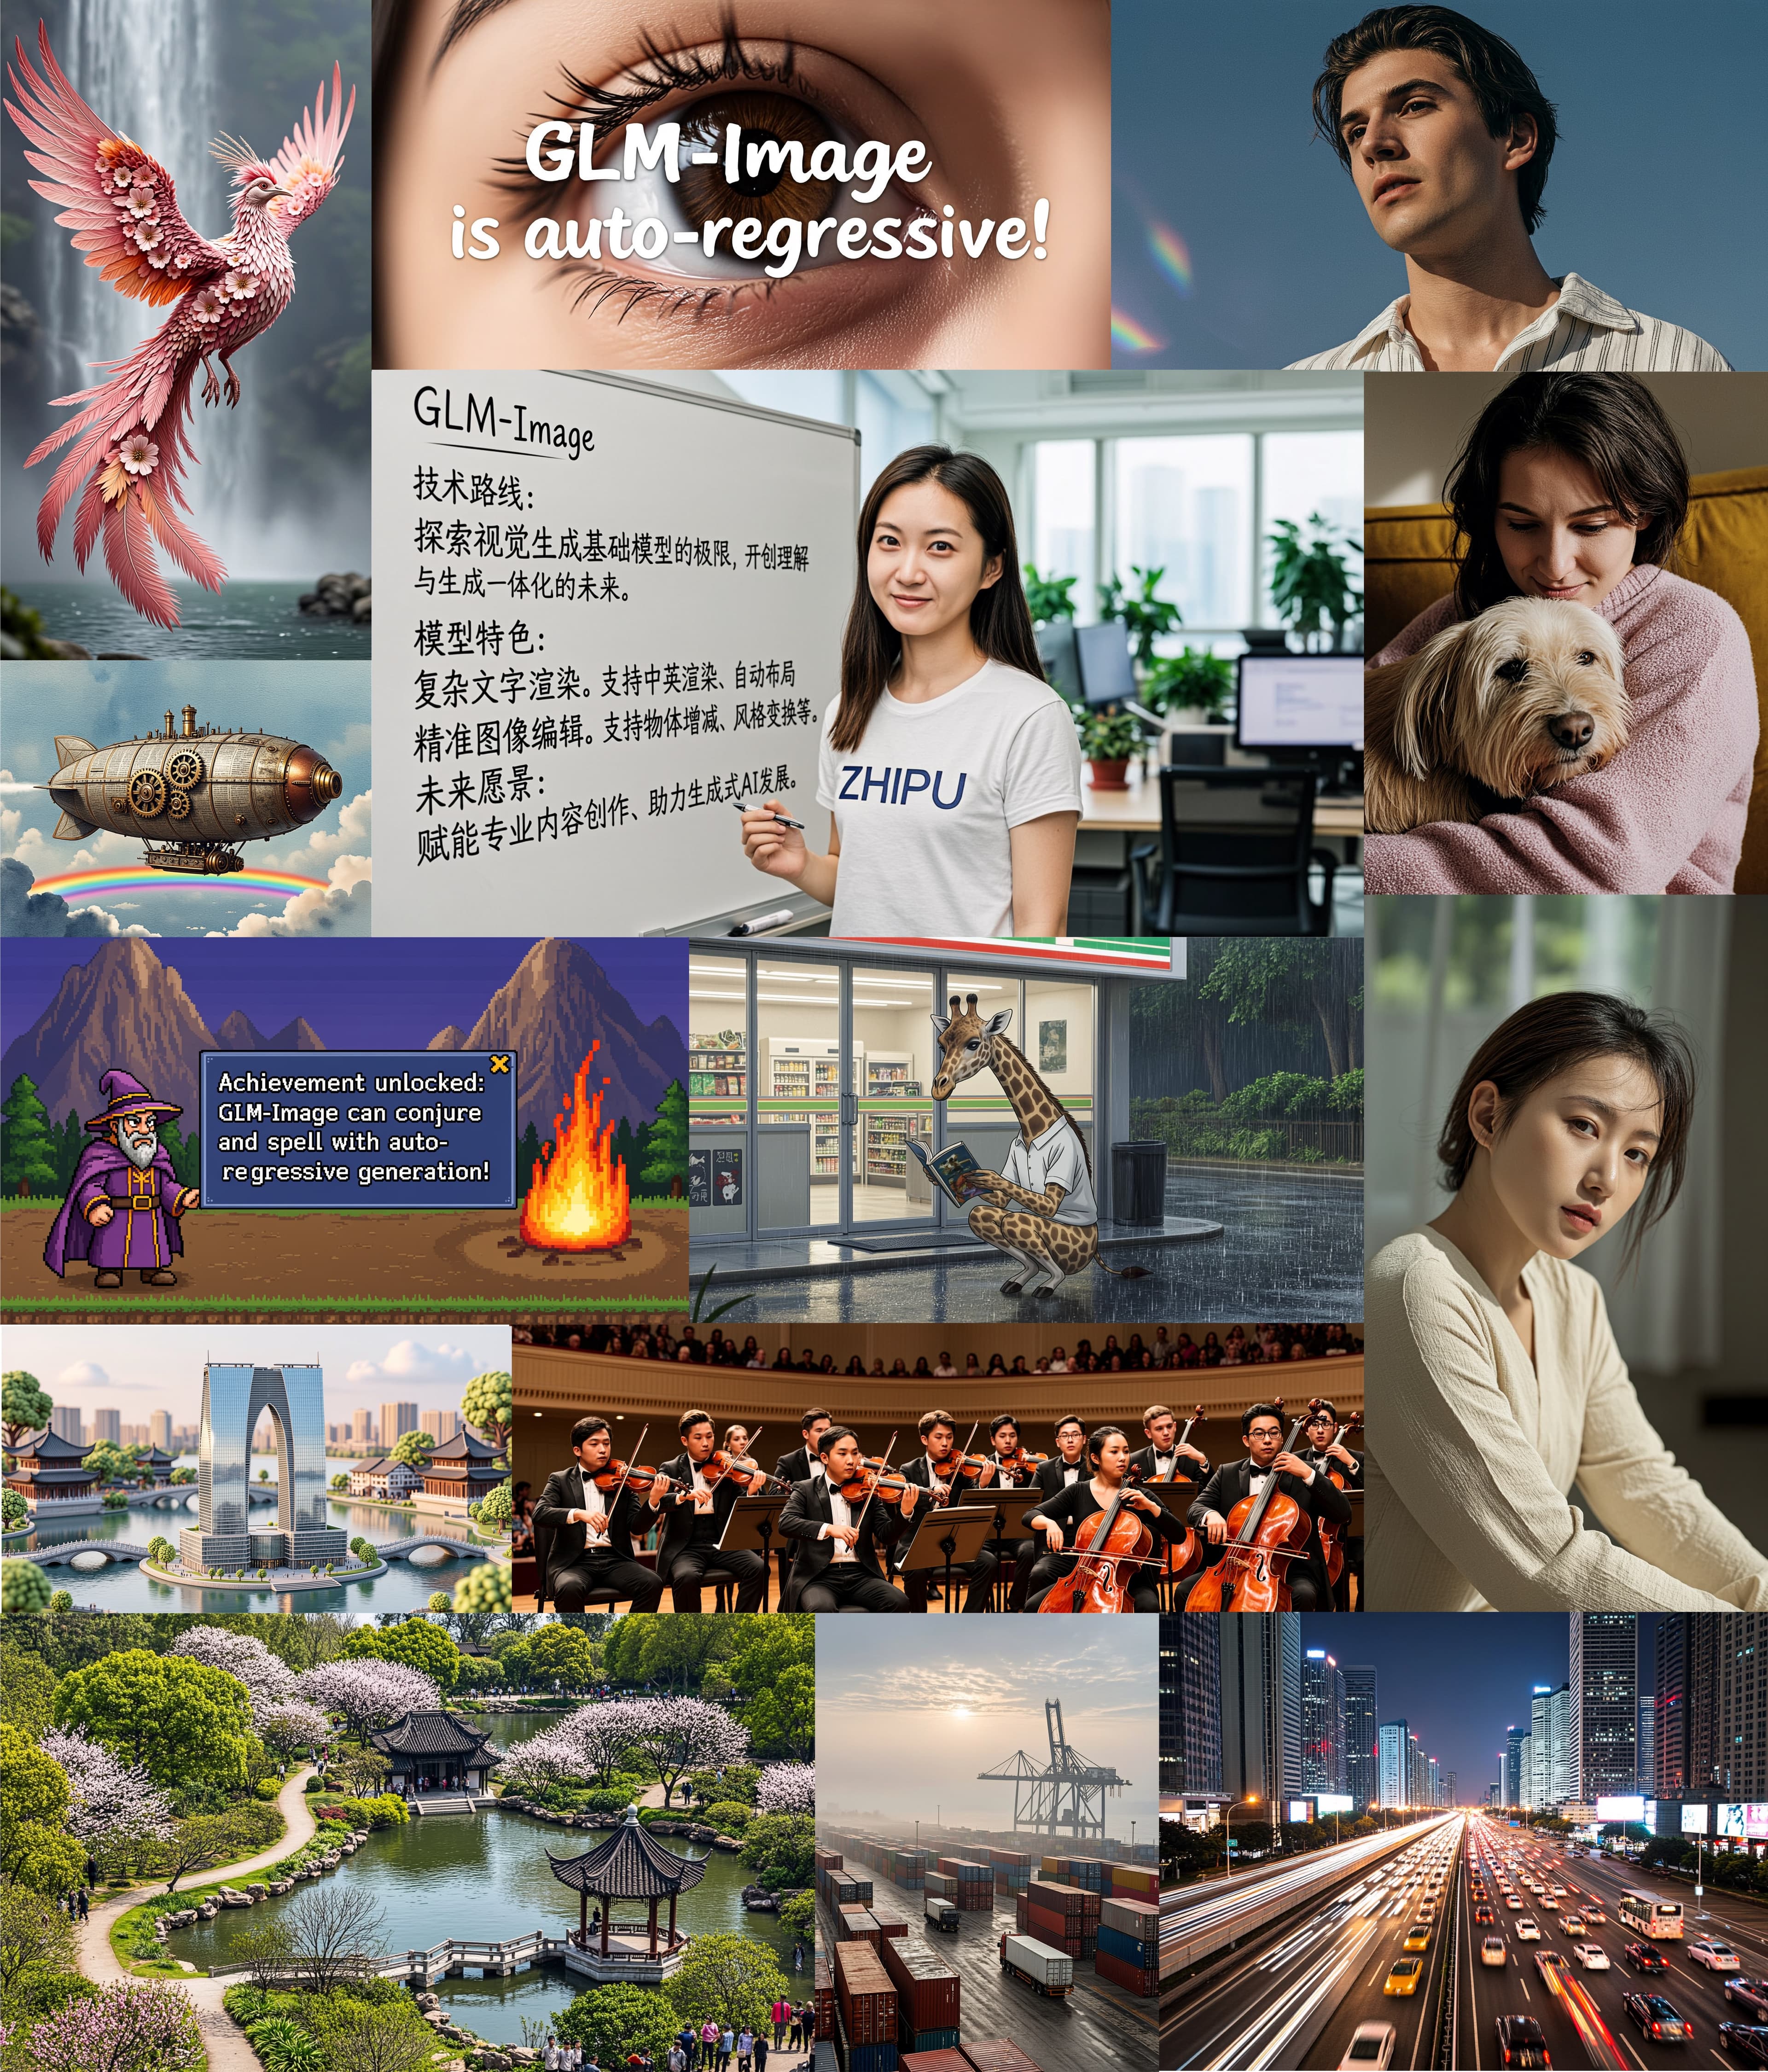
Zhipu AI, a prominent Beijing-based AI research company, has released GLM-Image, a new open-source model for generating images from text descriptions. The model's primary distinction is its native bilingual capability, fluently understanding prompts in both Chinese and English.
This release is a notable contribution to the open-source multimodal landscape, which has historically been dominated by English-centric models. By providing a powerful bilingual tool under a permissive MIT license, Zhipu AI is lowering the barrier for developers and researchers worldwide to build applications that serve a more linguistically diverse audience.
Technical Foundations
GLM-Image is a diffusion model built upon the architecture of CogView2, an earlier powerful text-to-image model from the same research lineage. It works by pairing a Transformer-based text encoder with the diffusion model that synthesizes the final image.
The model and its weights are available for download from the project's Hugging Face repository. This move continues Zhipu AI's pattern of contributing significant models to the open-source community, fostering further innovation in multimodal AI research.
Sources
- Visit
zai-org/GLM-Image
Hugging Face
More from Zhipu AI
All Zhipu AI releases →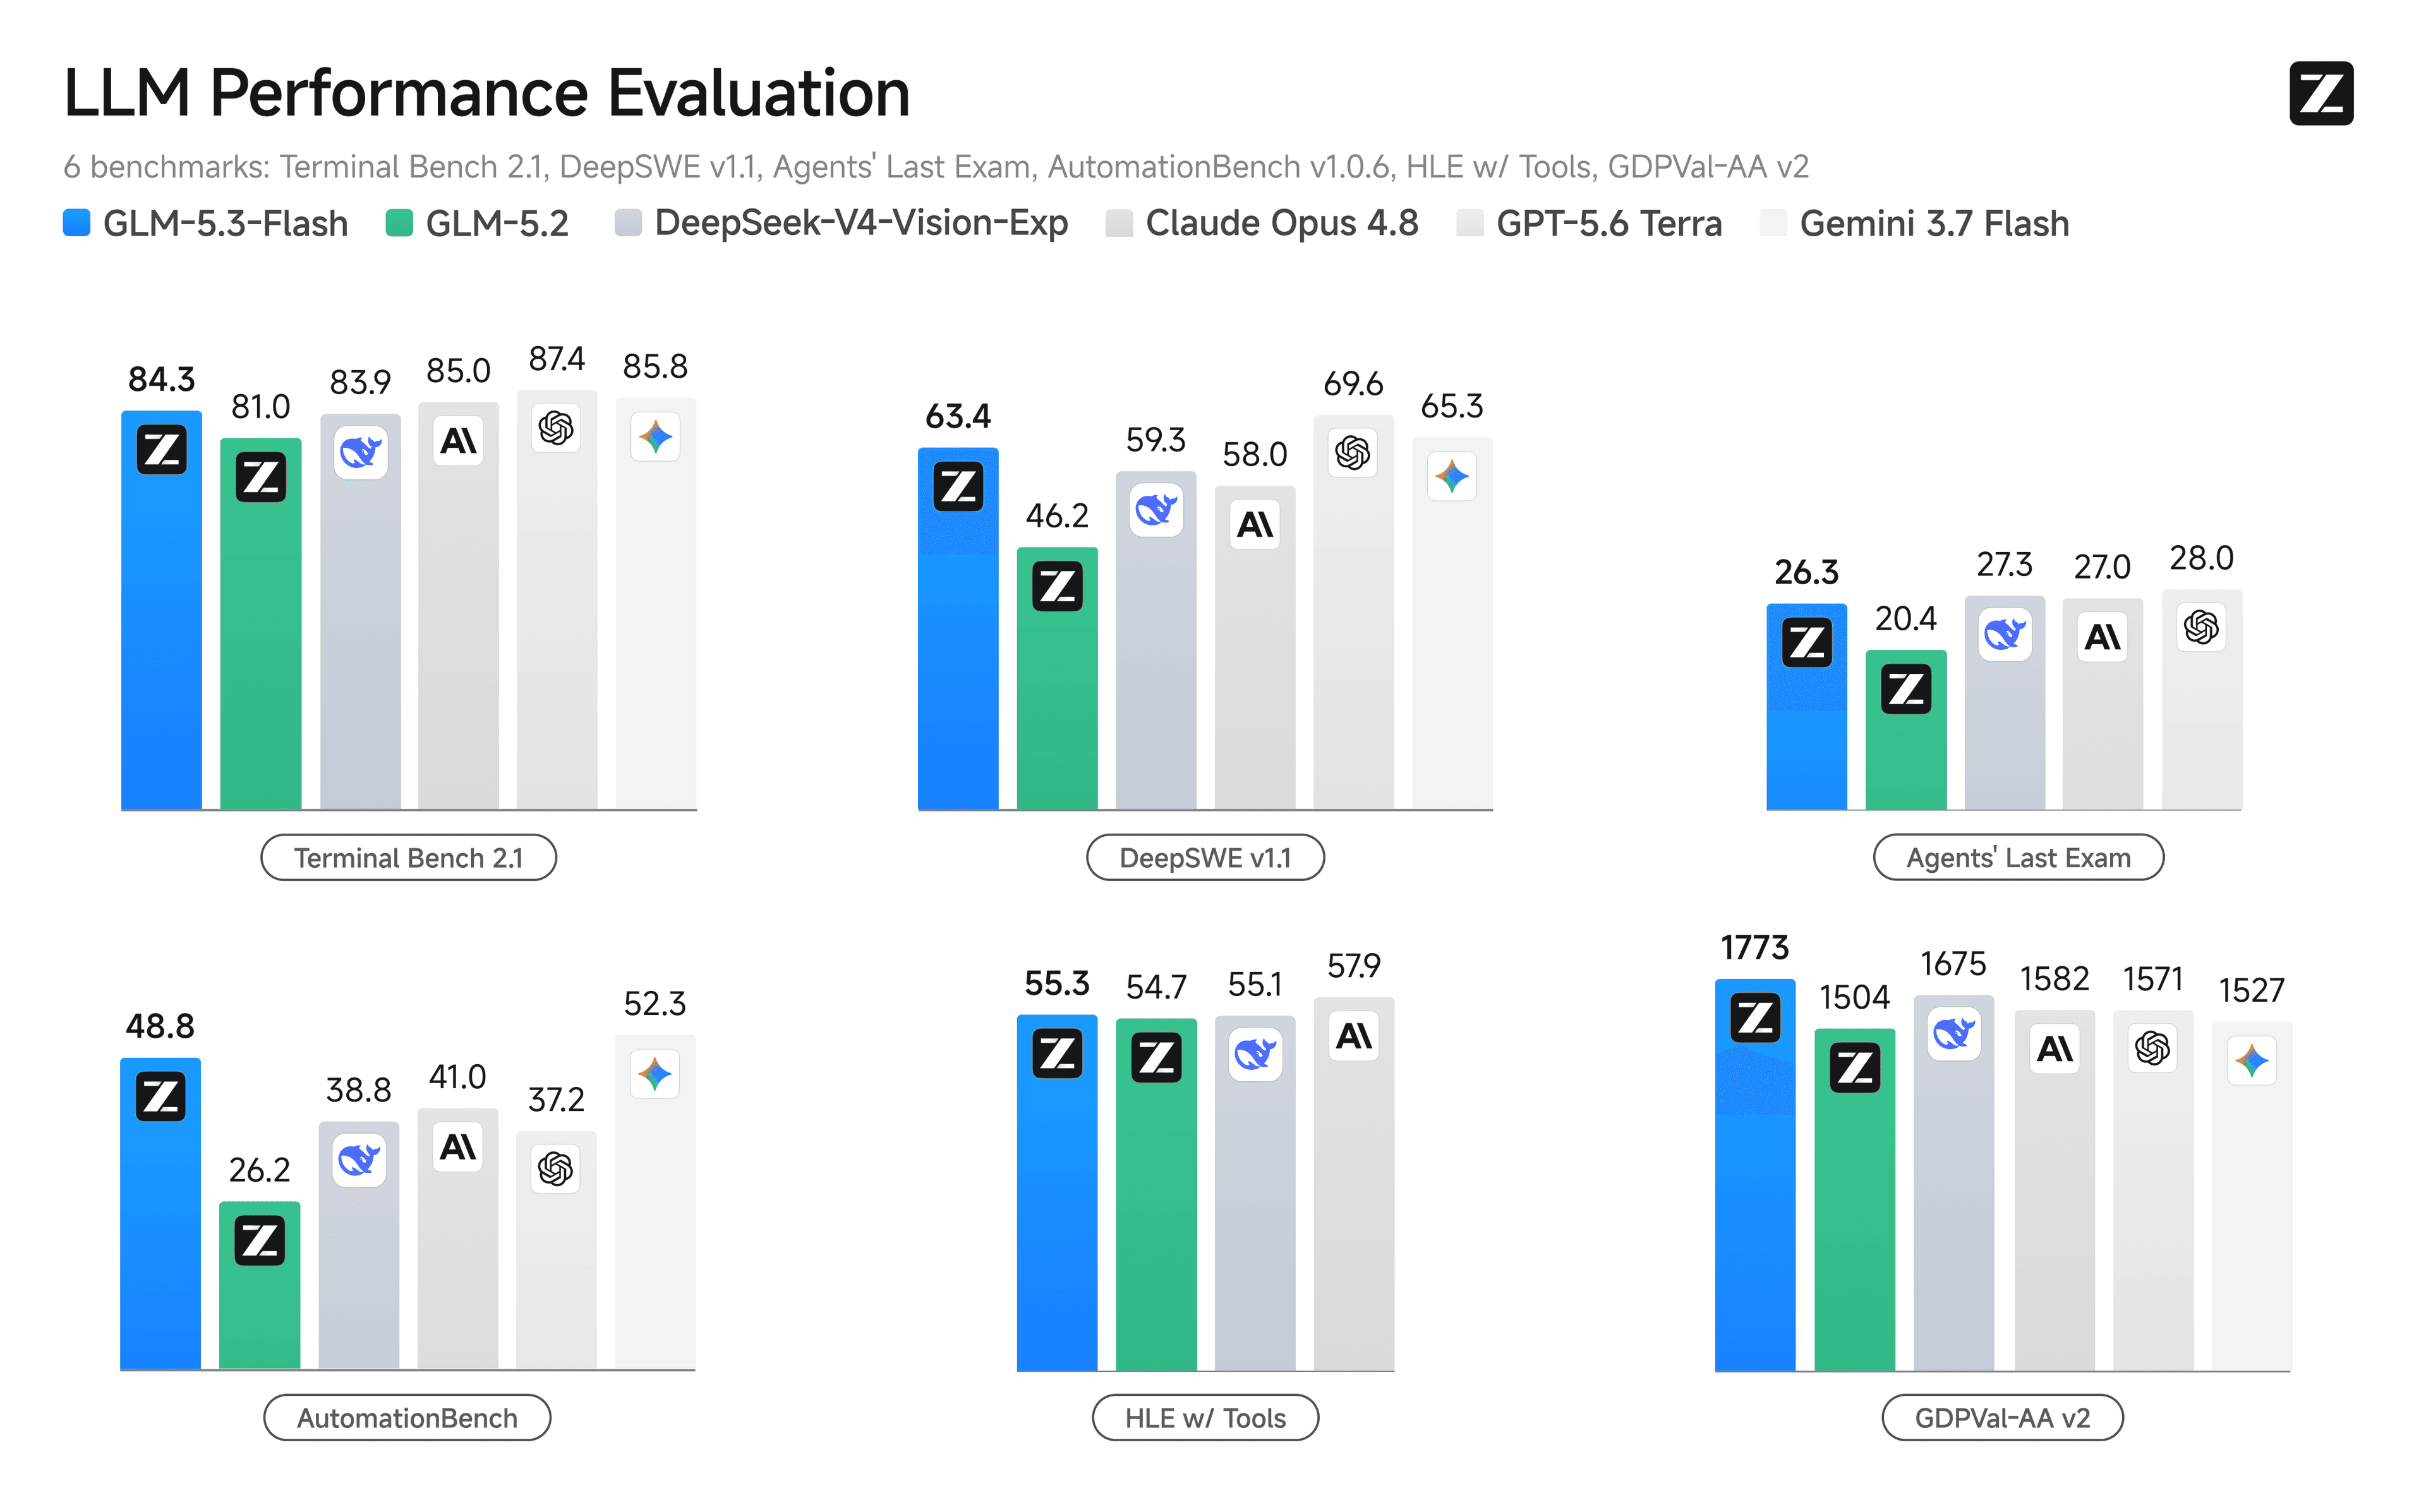
Zhipu releases GLM-5.3-Flash under MIT license
A speed-tuned member of the GLM-5.3 family arrives with open weights and mixture-of-experts design aimed at fast, low-cost inference.
Zhipu's GLM-5.3 Targets Coding at a Fraction of the Cost
The open-weight MoE model from Zhipu AI aims to match frontier closed systems on coding tasks while undercutting them on price.
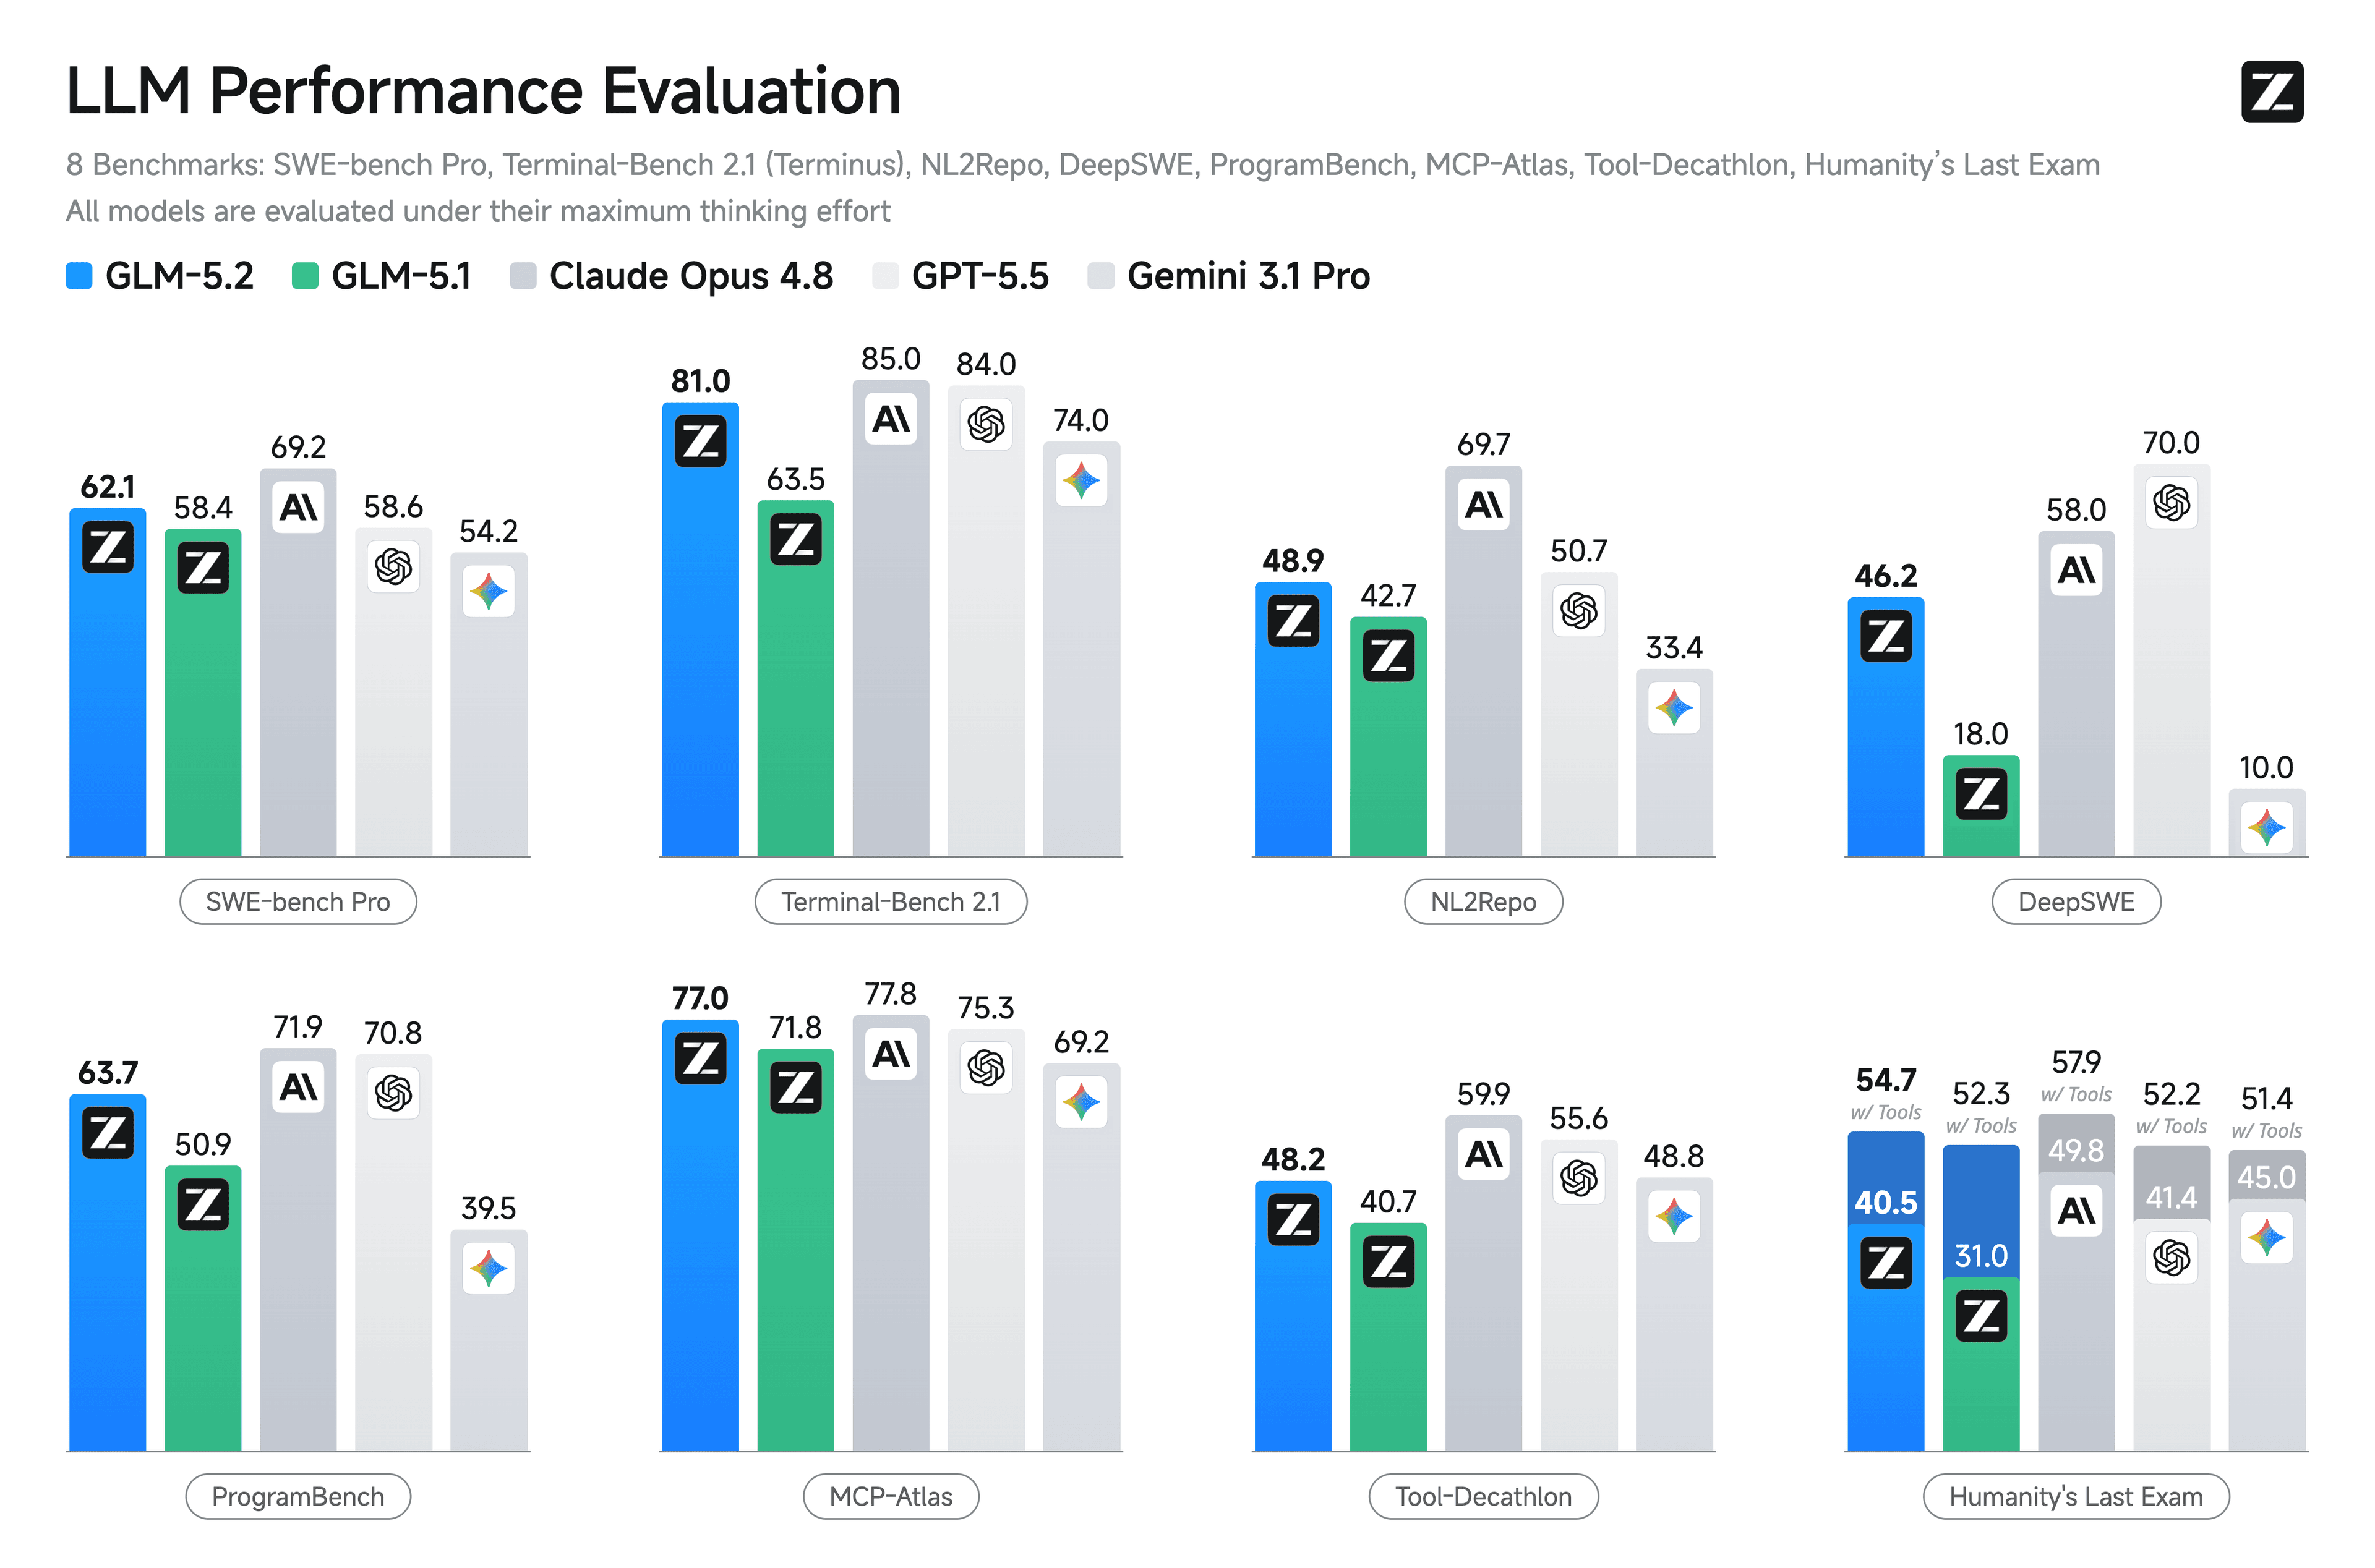
Zhipu AI Releases MIT-Licensed GLM-5.2 MoE Model
The new bilingual model from the Chinese AI firm uses a Mixture of Experts architecture and sparse attention under a fully permissive license.
More in Text → Image
All Text → Image →
Bria's Fibo 2.0 Brings Structured Prompts to Open Image AI
The new text-to-image and editing model leans on structured prompts and multi-reference inputs for more controllable generation.

Black Forest Labs ships FLUX.3 Image Klein for ComfyUI
The lab's latest open image model arrives packaged for ComfyUI with both generation and editing built in.

Black Forest Labs ships FLUX.3 Image Klein
The latest open image model from the FLUX team handles both text-to-image generation and editing, and arrives ready to run in Diffusers.
0 comments
No comments yet. Be the first to weigh in.