Soul-AILab Releases Zero-Shot Singing Voice Model
The new model, SoulX-Singer, can replicate a singing voice from a short audio sample and supports both English and Chinese under a permissive license.
A new open-source model from Soul-AILab aims to make high-quality synthetic singing voices more accessible. Called SoulX-Singer, the model is designed for singing voice synthesis (SVS), allowing users to generate vocal performances from musical scores and lyrics.
The model's key feature is its zero-shot capability. This means it can replicate a specific singer's vocal timbre and style from just a short, five-second audio clip, without requiring any model retraining. This significantly lowers the barrier to entry for creating custom vocal tracks for music production or creative projects.
SoulX-Singer supports generating vocals in both English and Chinese. The project was released under the Apache 2.0 license, a permissive open-source license that allows for both academic and commercial use. This opens the door for developers and musicians to integrate the technology into their own applications and workflows.
The release of models like SoulX-Singer marks a growing trend in open-source AI, moving beyond text and images into more nuanced creative domains like music. By providing powerful tools for vocal synthesis, the project empowers independent creators to experiment with sounds that were once the exclusive domain of professional recording studios. The model is available now on the Hugging Face Hub, complete with usage examples.
Sources
- Visit
Soul-AILab/SoulX-Singer
Hugging Face
More in Music
StepFun's StepAudio 3 Music Plans Before It Plays
The new open model separates musical structure from sound, generating long-form tracks from text prompts with an explicit planning stage.
StepFun's StepAudio 3 Gen Unifies TTS and Music
A single discrete autoregressive model handles speech, voice design, sound effects, and music generation.
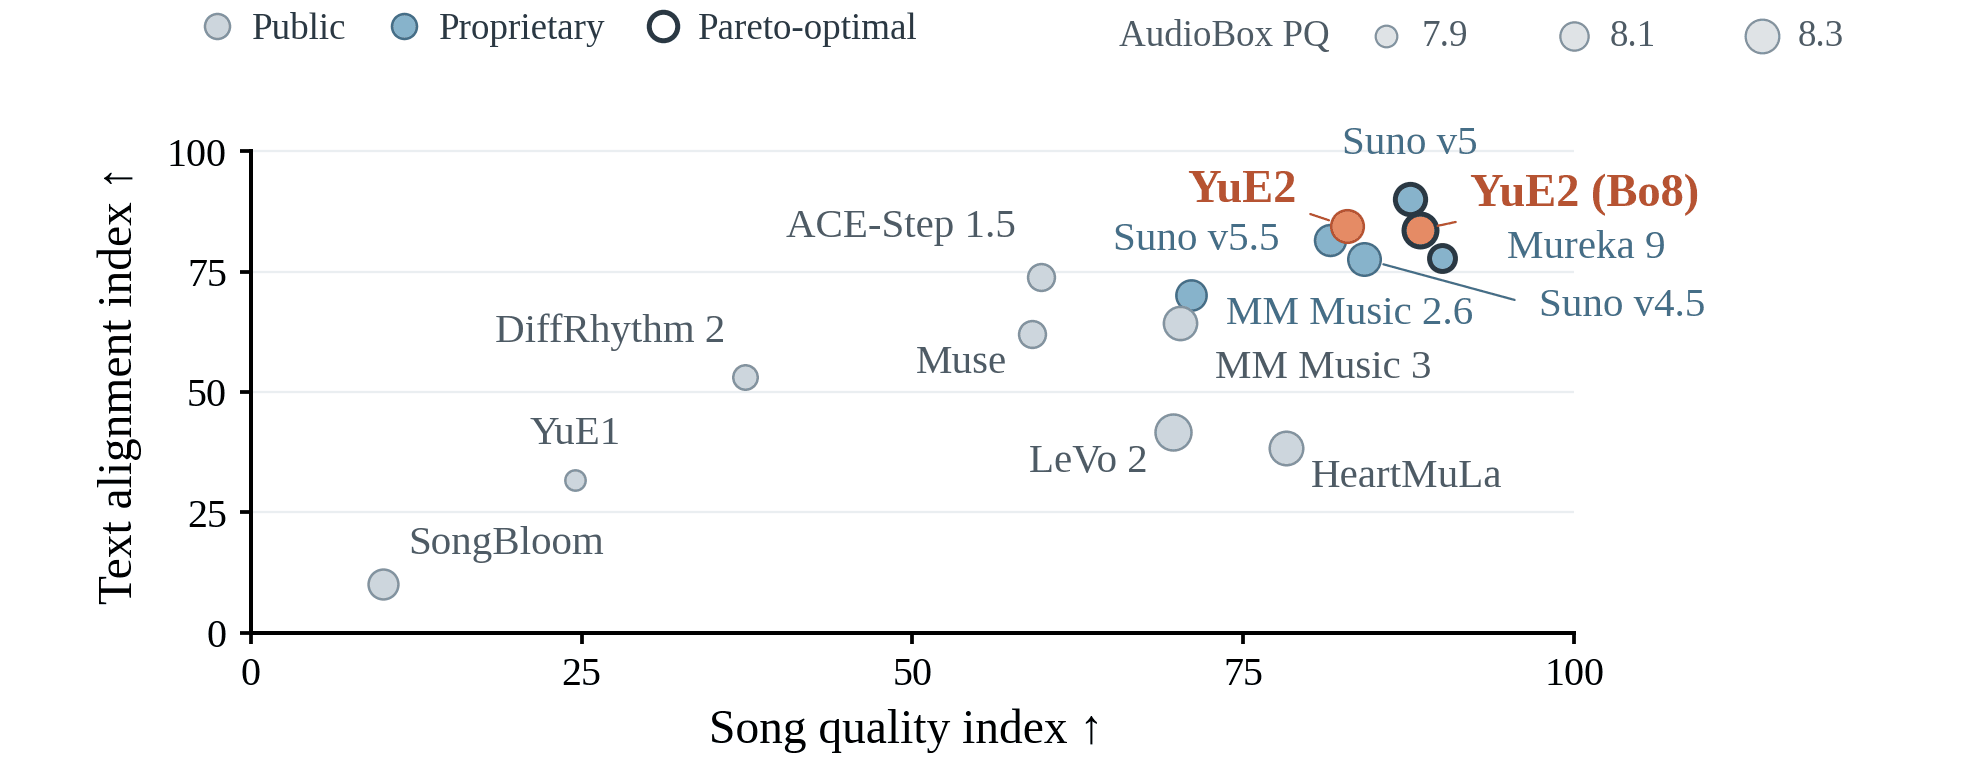
OpenMOSS Unveils YuE2-3B Music Generation Model
The 3-billion-parameter model adds symbolic planning and agentic editing to open-source music generation.
0 comments
No comments yet. Be the first to weigh in.