NVIDIA opens Magpie TTS for multilingual voice agents
The company releases open weights for a low-latency, multilingual text-to-speech model aimed at real-time conversational systems.
NVIDIA has released Magpie TTS Multilingual, an open-weights text-to-speech model designed for building responsive voice agents. According to NVIDIA's announcement on Hugging Face, the model emphasizes low latency and multilingual synthesis — two qualities that matter most when speech is generated on the fly rather than pre-rendered.
The pitch is straightforward: teams building conversational systems often have to choose between the quality of a hosted API and the control of running their own stack. By publishing the weights, NVIDIA is offering the latter, giving developers full deployment control over where and how the model runs.
Why it matters
Voice agents live or die by responsiveness. A few hundred extra milliseconds of delay makes a conversation feel stilted, so a model tuned for real-time generation across multiple languages fills a practical gap for anyone building assistants, IVR replacements, or accessibility tools.
- Open weights, so the model can be self-hosted rather than accessed only through an API
- Multilingual output for cross-language deployments
- Low-latency design aimed at real-time conversational use
NVIDIA distributes the model under a custom license, so teams should review the terms before shipping. Details, including deployment guidance, are laid out in the company's post.
Sources
More from NVIDIA
All NVIDIA releases →NVIDIA's Cosmos 3 Brings Open Interactive World Models
The new open release pushes beyond passive video generation toward simulated worlds that respond to input.
NVIDIA Releases Cosmos 3 for World Simulation
The new open models push NVIDIA's world-foundation effort toward interactive, real-time video generation.
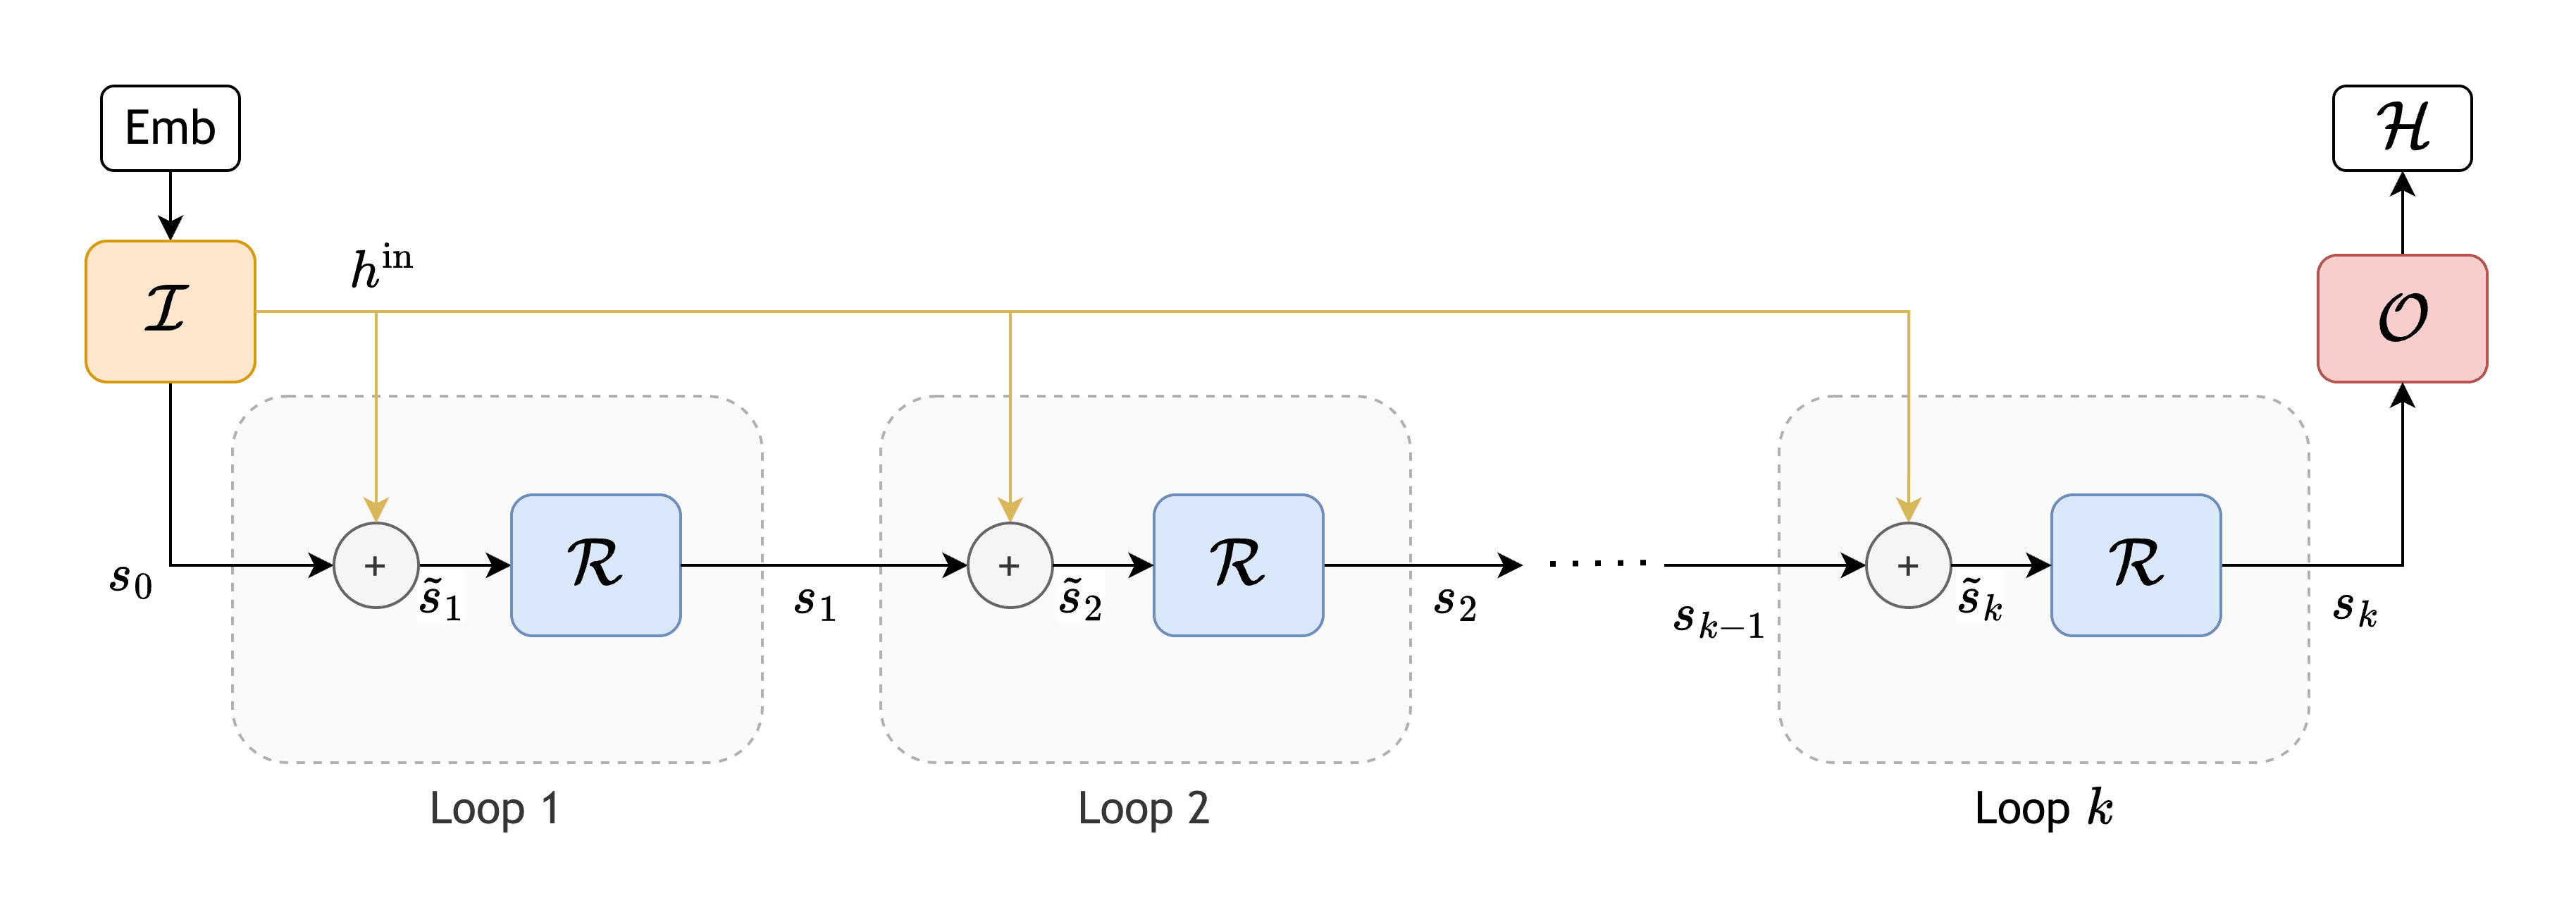
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
More in Text → Speech
All Text → Speech →
Haru-4B Brings Full-Duplex Speech to Six Languages
A compact 4-billion-parameter model handles real-time, two-way voice conversation across six languages in a single system.
Zyphra releases Zonos3-Mini multilingual TTS
The compact open text-to-speech model supports multiple languages and voice cloning from short audio samples.
OpenBMB's Phonon Brings High-Quality TTS On-Device
The new text-to-speech model promises benchmark-topping voice synthesis that runs locally rather than in the cloud.
0 comments
No comments yet. Be the first to weigh in.