LightOn ships a 4B OCR model with visual grounding
LightOnOCR-3-4B pairs document transcription with the ability to point back to where text sits on the page.
LightOn has released LightOnOCR-3-4B, a 4-billion-parameter vision-language model aimed squarely at document understanding. Rather than a general-purpose chat model, it is tuned for the unglamorous but high-value work of turning pages—scans, PDFs, forms—into structured, machine-readable text.
The headline capability is visual grounding: beyond transcribing content, the model can tie its outputs back to specific regions of the source image. That matters for anyone who needs to trust and verify an extraction, since a grounded result can be audited against the original layout instead of taken on faith.
Why it matters
OCR has quietly become one of the most practical uses of multimodal models, and the trend is toward smaller systems that are cheap enough to run at scale.
- At 4B parameters, the model is small enough to deploy on modest hardware while still handling complex layouts.
- Grounding makes it a better fit for compliance, search, and data-pipeline work where provenance is required.
- It arrives under an open weights release on Hugging Face, lowering the barrier for teams to self-host rather than route sensitive documents through an API.
The model is distributed under a custom license, so teams should check the terms before commercial deployment. As with any OCR system, real-world accuracy will depend heavily on document quality and language coverage, which prospective users will want to validate on their own corpora.
Sources
- Visit
lightonai/LightOnOCR-3-4B
Hugging Face
More from LightOn
All LightOn releases →
LightOn Releases OCR-2, a 1B Document AI Model
The new vision model from the Paris-based AI lab uses Mistral architecture to extract text and structure from complex documents like PDFs and forms.
More in Vision-Language
All Vision-Language →
Cactus Compute's Mirage brings vision tasks on-device
The new open vision-language model targets detection, segmentation, and visual Q&A without relying on the cloud.
Thinking Machines ships Inkling-2-Small, an open MoE VLM
The Apache-2.0 vision-language model uses a mixture-of-experts design and lands openly on Hugging Face.
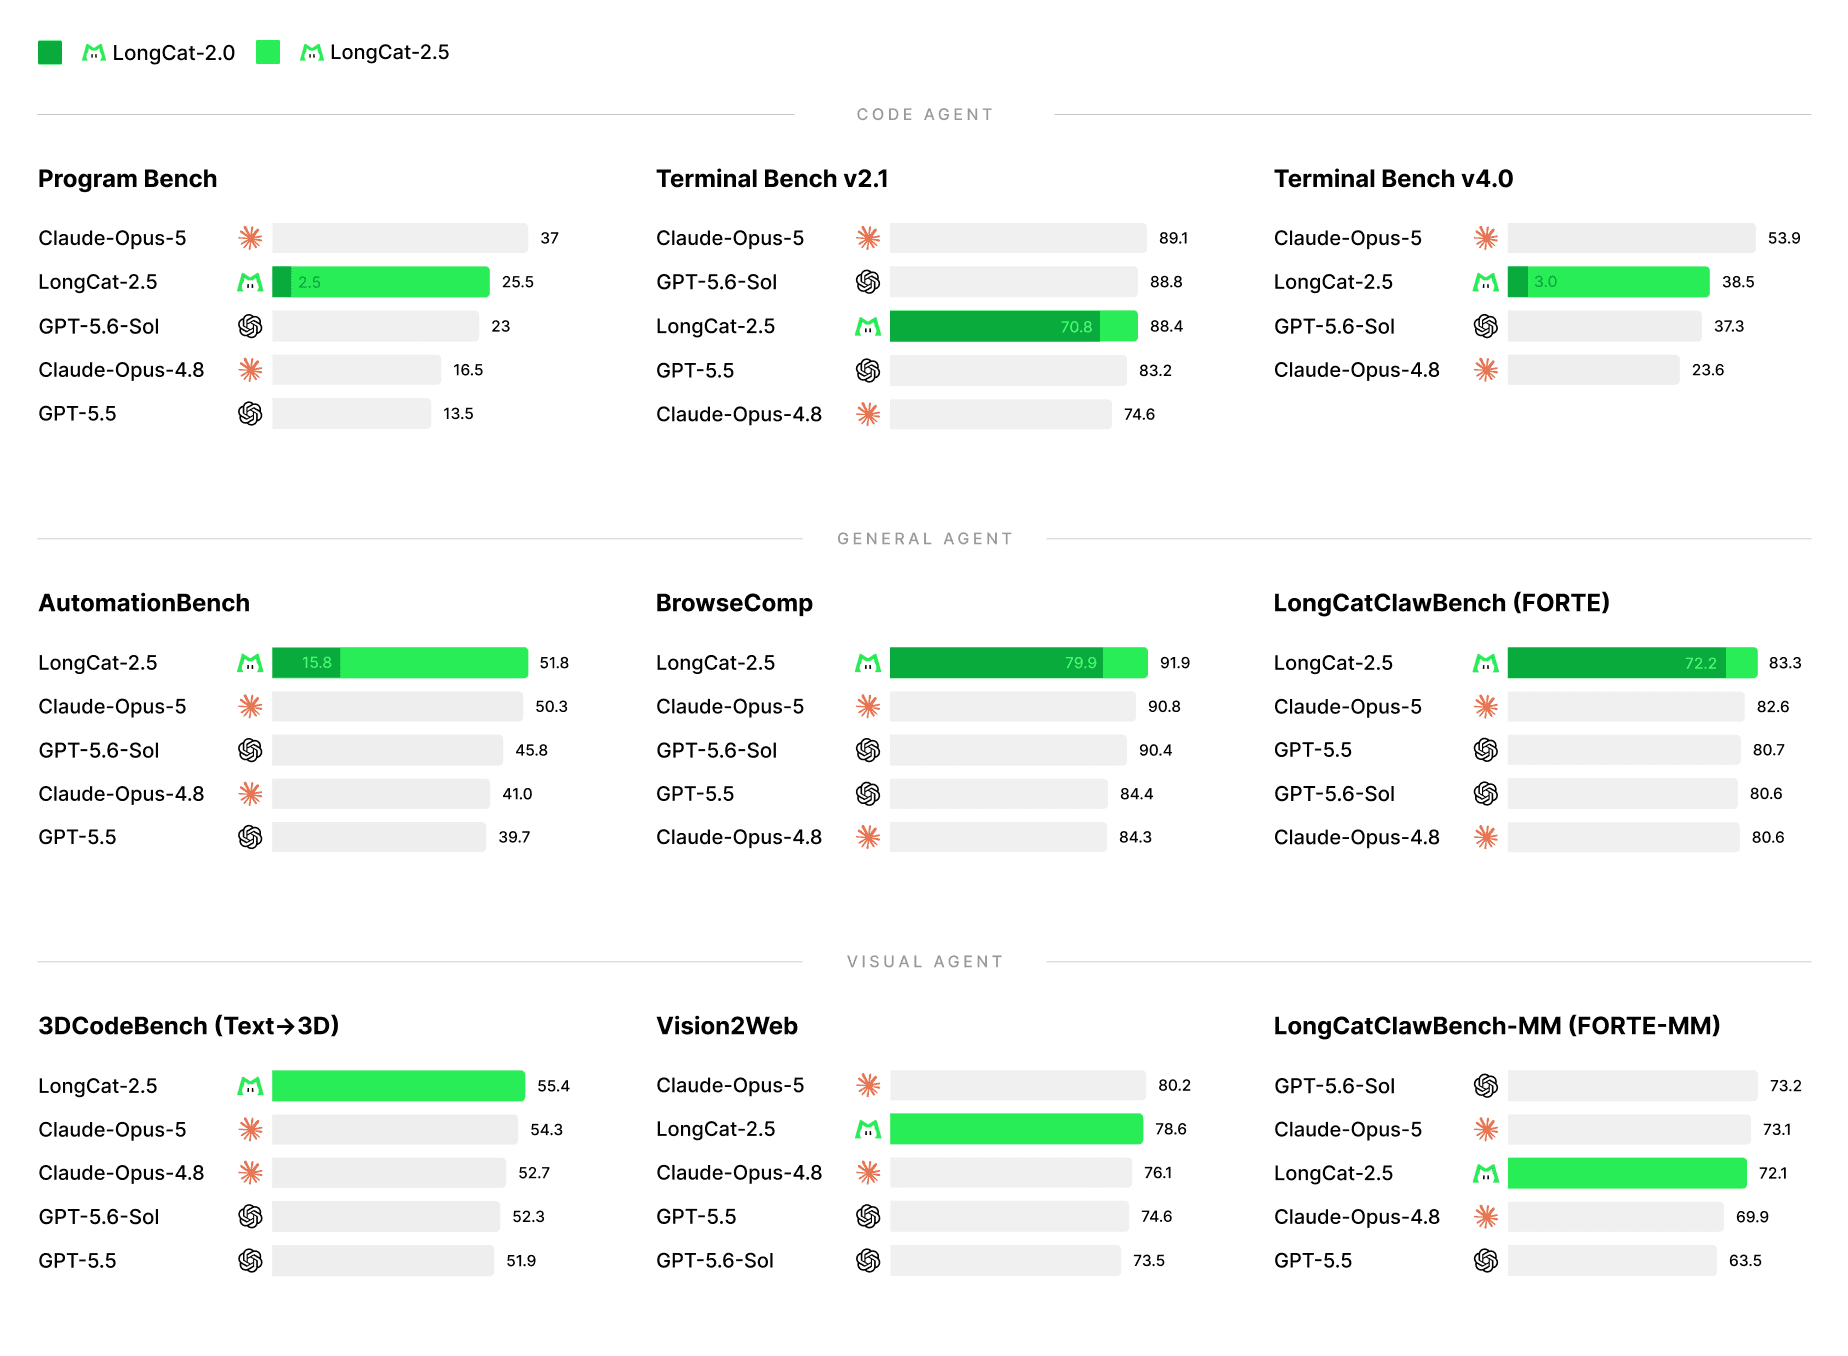
Meituan Releases LongCat 2.5, an MIT-Licensed MoE
The Chinese delivery giant expands its open-model push with a multimodal, agentic mixture-of-experts system.
0 comments
No comments yet. Be the first to weigh in.